
计算点差函数:方法,陷和解决方案
Optics express
|November 14, 2024

概括
精确的光显微镜需要精确的点传播函数 (PSF) 模型. 基于里埃的新方法克服了现有模型的局限性,确保节约能源以进行高质量的图像重建.
科学领域:
- 光学和光子学 在光学和光子学.
- 显微镜成像技术 显微镜成像技术
- 计算物理 计算物理
背景情况:
- 精确的点传播函数 (PSF) 建模对于高质量的光显微镜图像重建至关重要.
- 现有的现实空间PSF模型通常会因为中心附近的采样问题而违反节能.
- 矢量光特性和光学修改需要先进的PSF建模技术.
研究的目的:
- 为计算矢量点分散函数 (PSFs) 引入基于里埃的新技术.
- 为了解决现有的现实空间PSF模型中的节能违规问题.
- 为各种成像模式提供PSF建模的计算效率高和可重复的方法.
主要方法:
- 为矢量PSF计算开发基于富里叶的算法.
- 基于富里埃的新方法与最先进的现实空间PSF模型进行比较.
- 验证满足物理成像条件的方法,包括节能.
主要成果:
- 提出的基于里埃的技术满足成像过程的物理条件.
- 在节能方面表现出优于现有方法的优势.
- 这些方法在计算上高效,可复制,易于适应.
结论:
- 基于里埃的新技术为光显微镜中精确的矢量PSF计算提供了强大的解决方案.
- 这些方法克服了当前真实空间模型的关键限制,确保了物理有效性.
- 开发的方法是多功能,高效,适合各种成像应用.
相关概念视频
 01:14
Standard Deviation of Calculated Results
5.8K
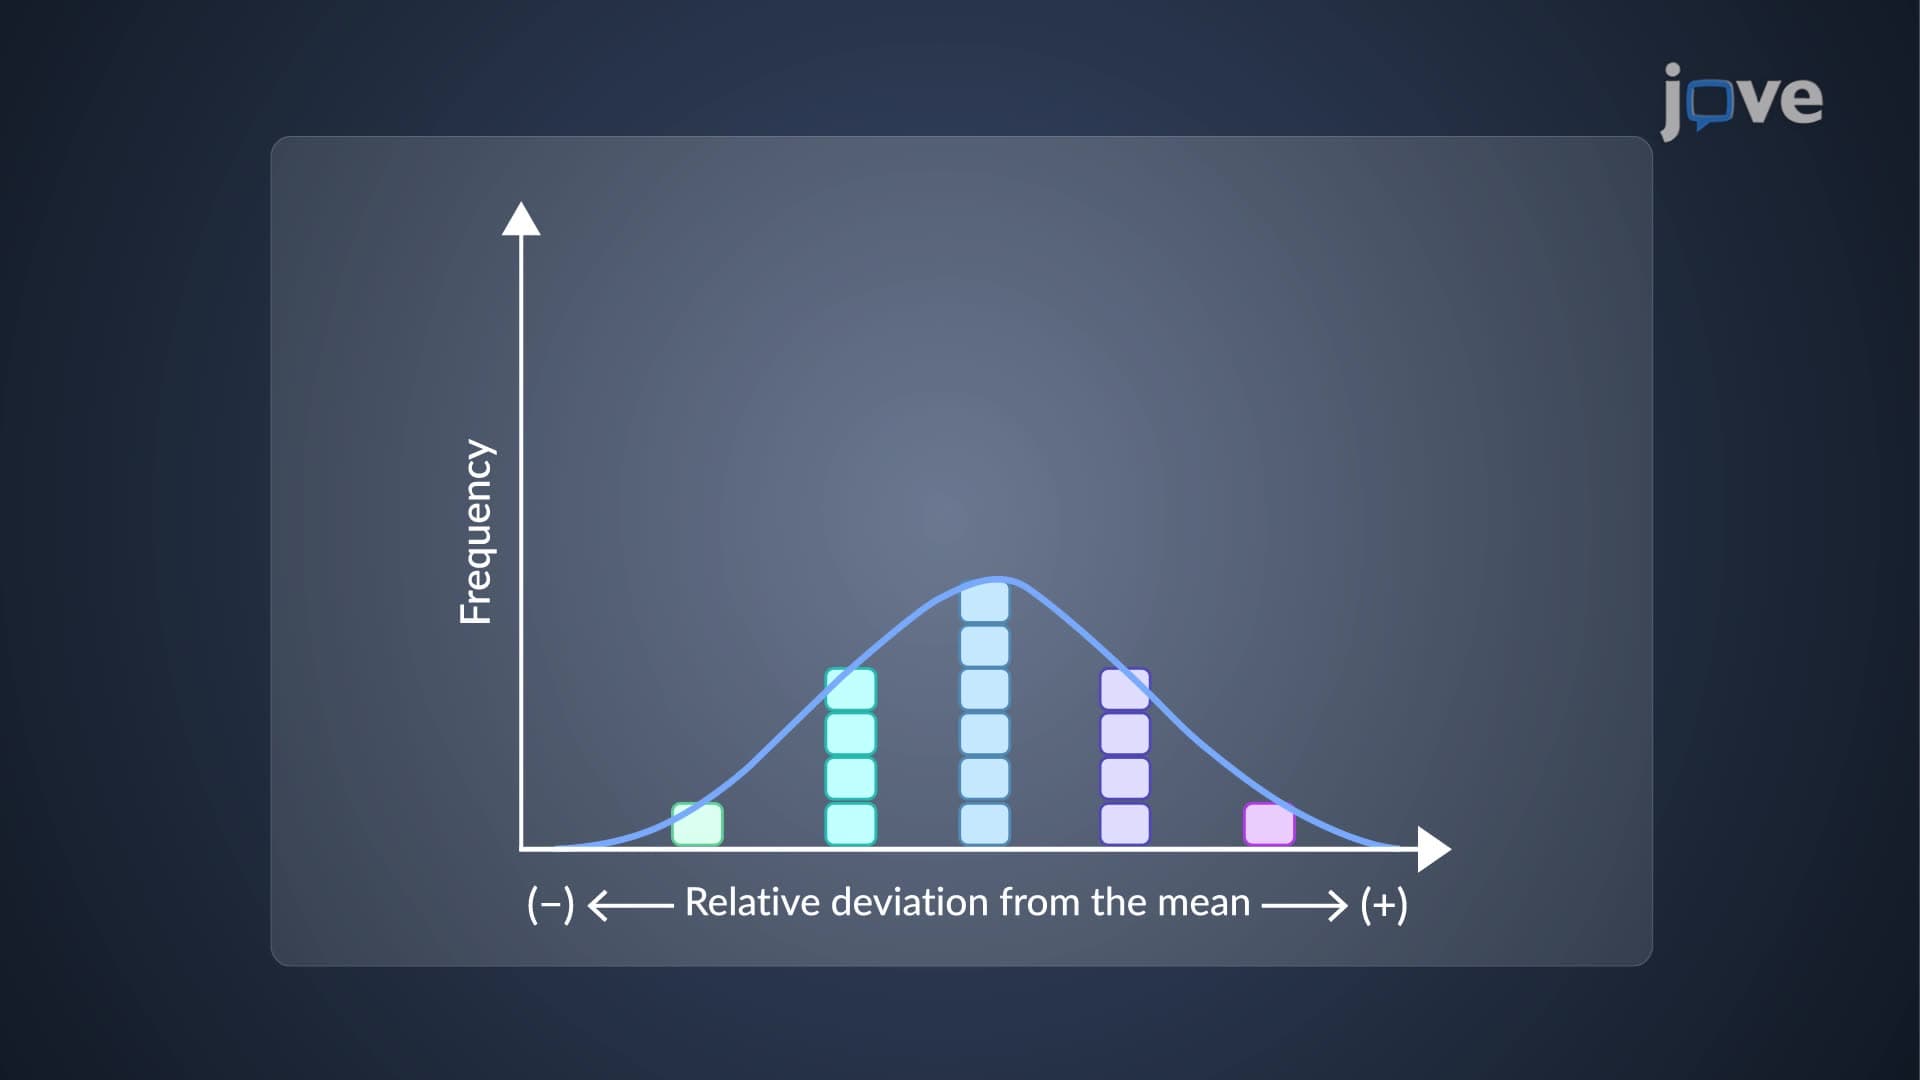
Standard deviation measures the spread of data around the mean value. Many large data sets follow a Gaussian distribution, also known as a normal distribution. This distribution is bell-shaped curved, with the most frequently observed value (mean or central value) in the middle. The farther away from the central value, the greater the deviation from the central value, and the lower the frequency.
A broad Gaussian distribution curve has a wider standard deviation, representing a data set with...
A broad Gaussian distribution curve has a wider standard deviation, representing a data set with...
5.8K
 01:26
Field Procedure for Staking Out Curves
33
Staking out curves is an essential process in construction to ensure the accurate alignment of structures along a curved path. This task involves positioning stakes at calculated locations corresponding to the curve's design, effectively translating plans into physical markers in the field. The process begins by determining the geometric parameters of the curve, including the radius, central angle, and tangent distances. These parameters are critical for identifying key points such as the...
33
 01:18
Microsoft Excel: Plotting Mean, SD, and SE
162
In Microsoft Excel, plotting the mean along with standard deviation (SD) and standard error (SE) helps visualize data variability and reliability. To plot these values, follow these steps:
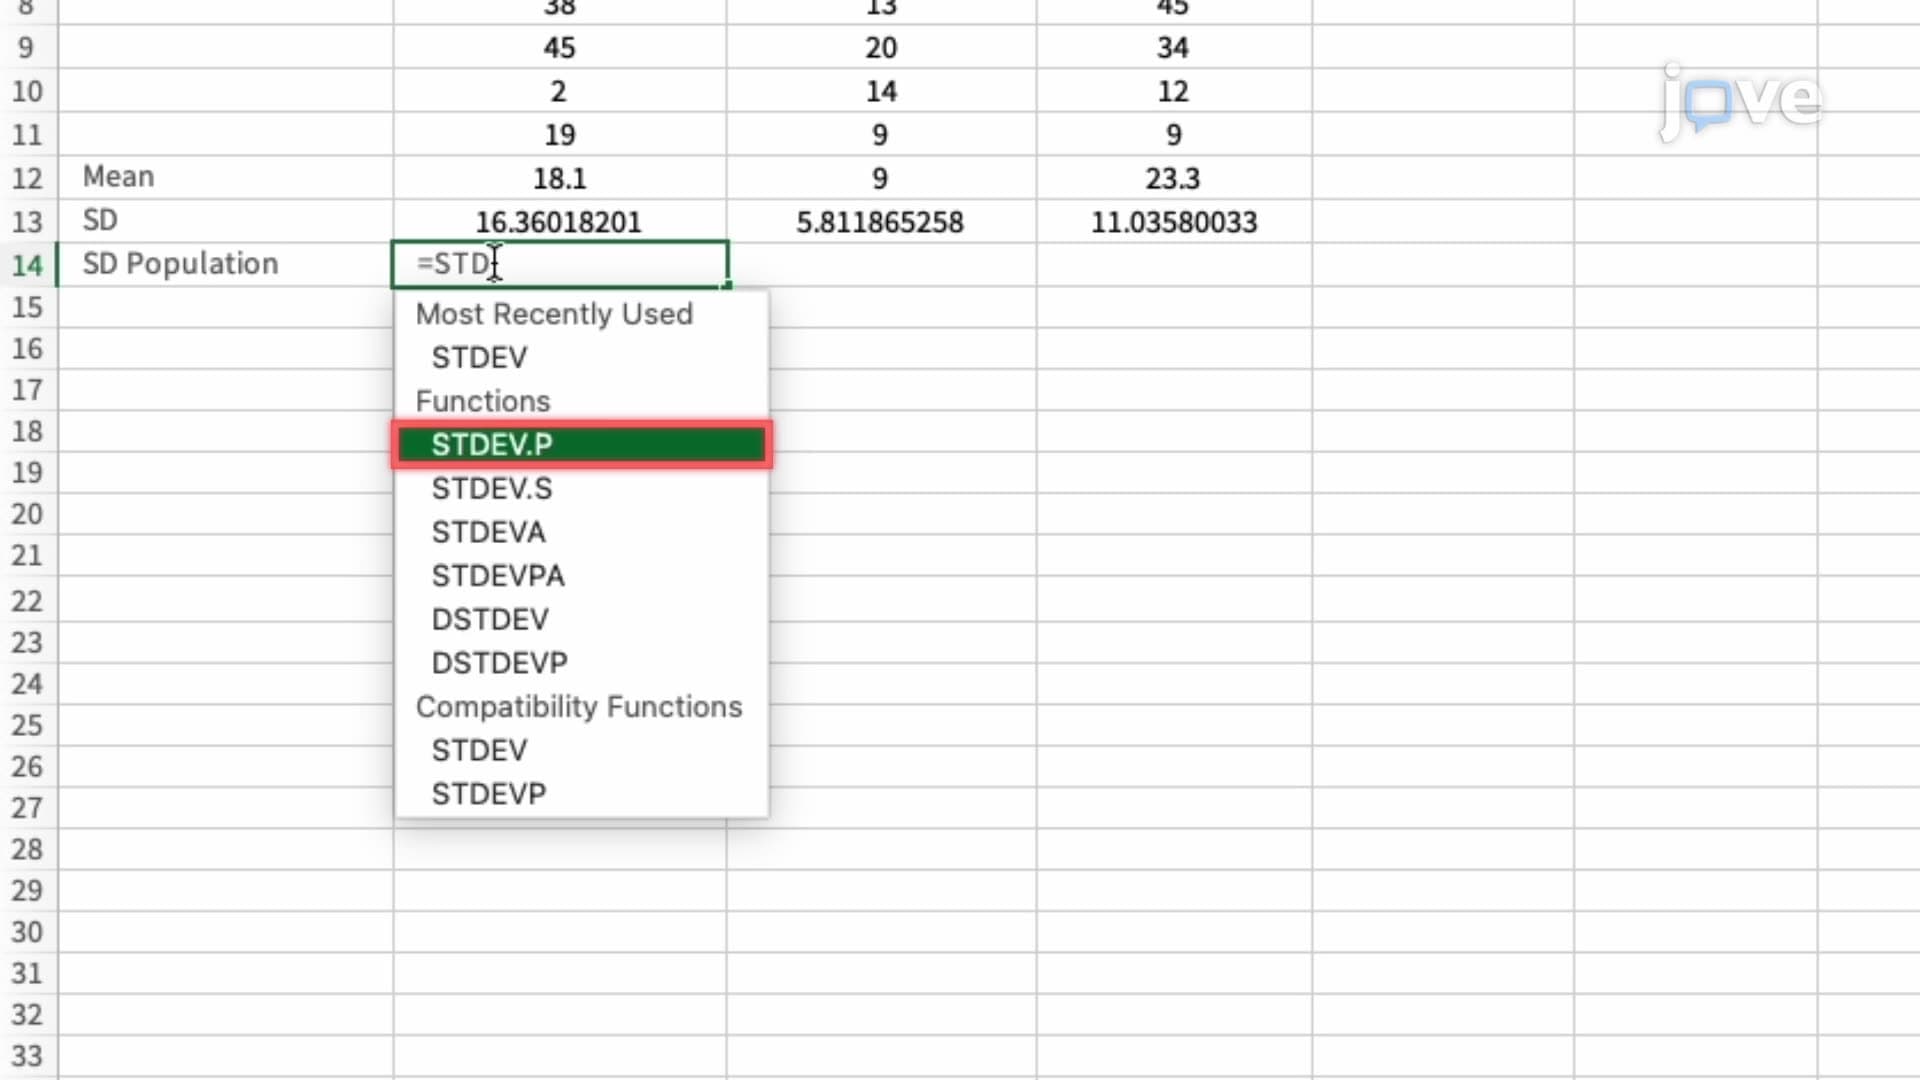
First, calculate the mean, SD, and SE of your data. The mean is obtained using the formula `=AVERAGE(range)`, while SD can be calculated with `=STDEV.P(range)` for a population or `=STDEV.S(range)` for a sample. SE is calculated as `=SD/SQRT(n)`, where `n` is the sample size.
To plot these values, use a bar...
162
 01:08
Calculating Standard Deviation
7.3K
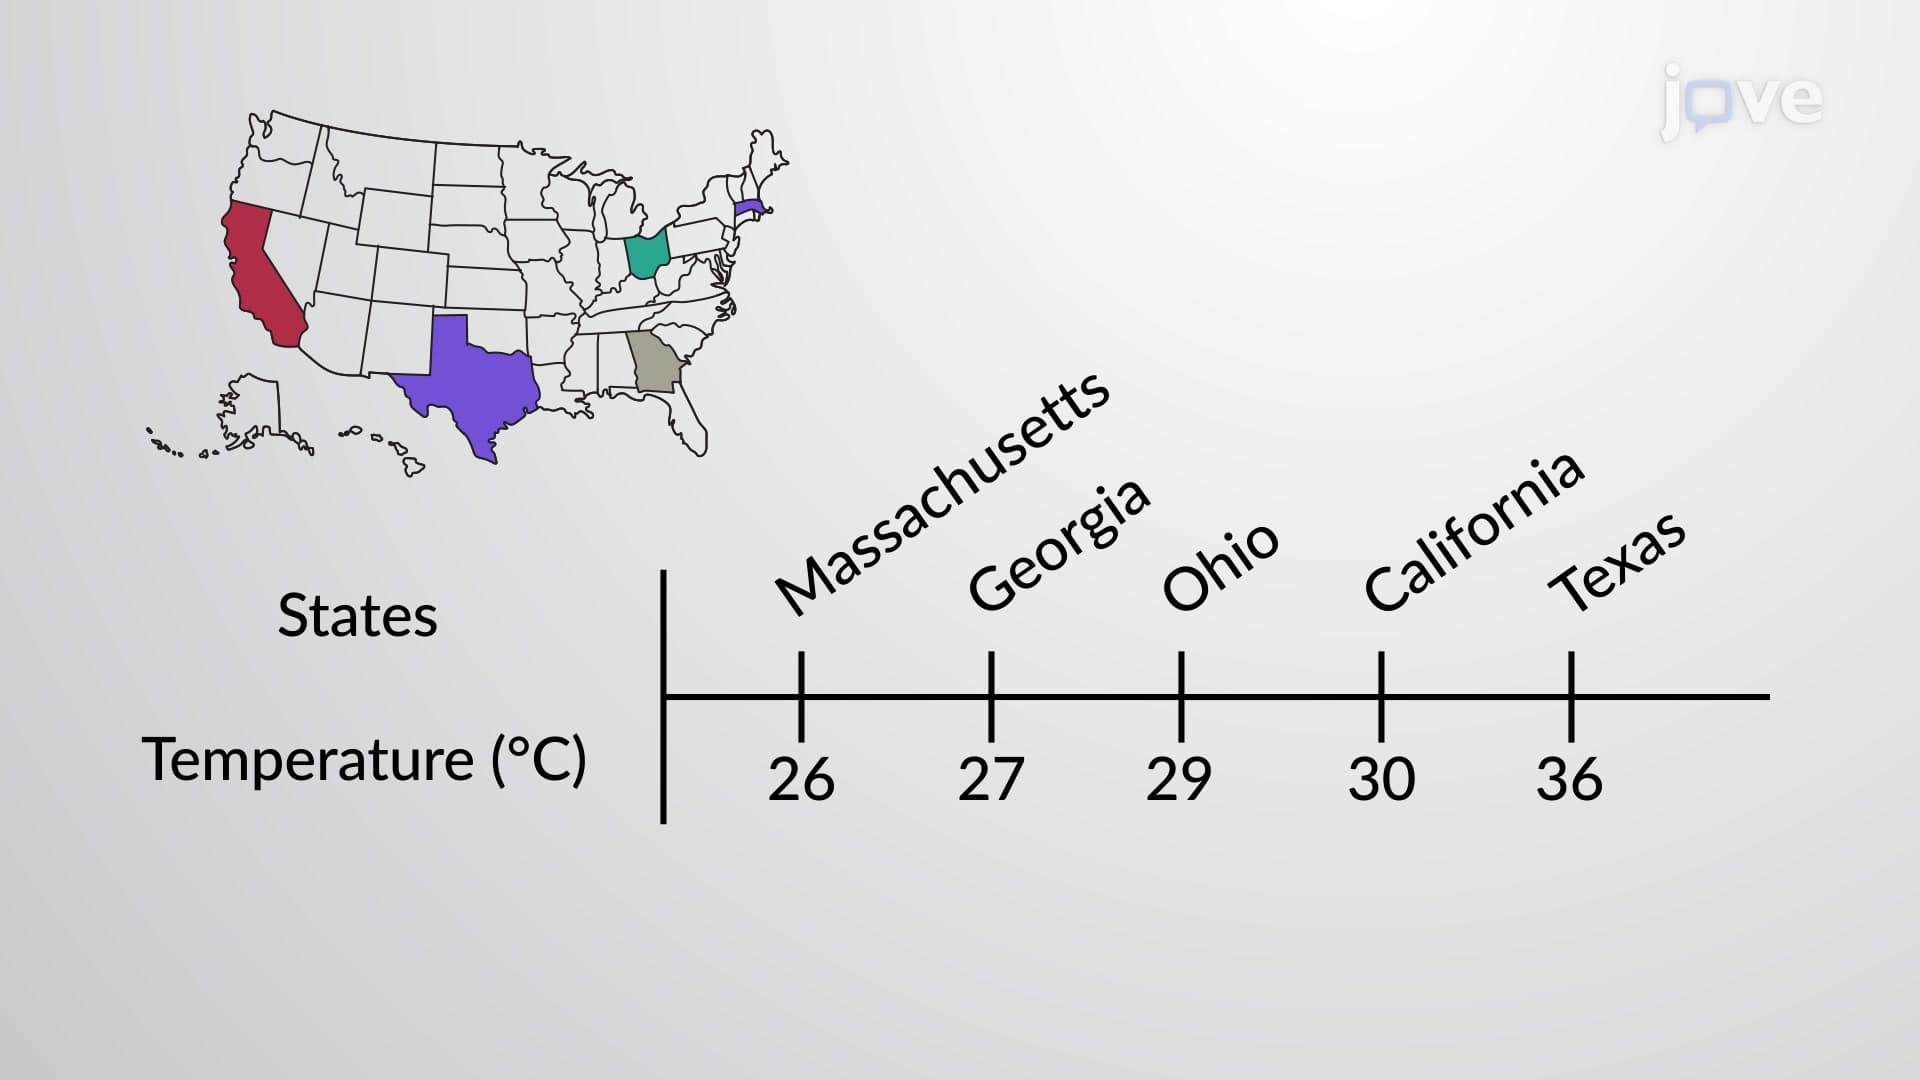
The standard deviation is the most common measure of variation. It is a value that tells us how far a data value is from the mean value in a dataset. Further, the standard deviation is always a positive value or zero.
The standard deviation value is small when all the data is concentrated close to the mean. Here the data exhibits low variation. The standard deviation value is larger when the data values are more spread out from the mean. Here, the data displays high...
The standard deviation value is small when all the data is concentrated close to the mean. Here the data exhibits low variation. The standard deviation value is larger when the data values are more spread out from the mean. Here, the data displays high...
7.3K
 01:24
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
135
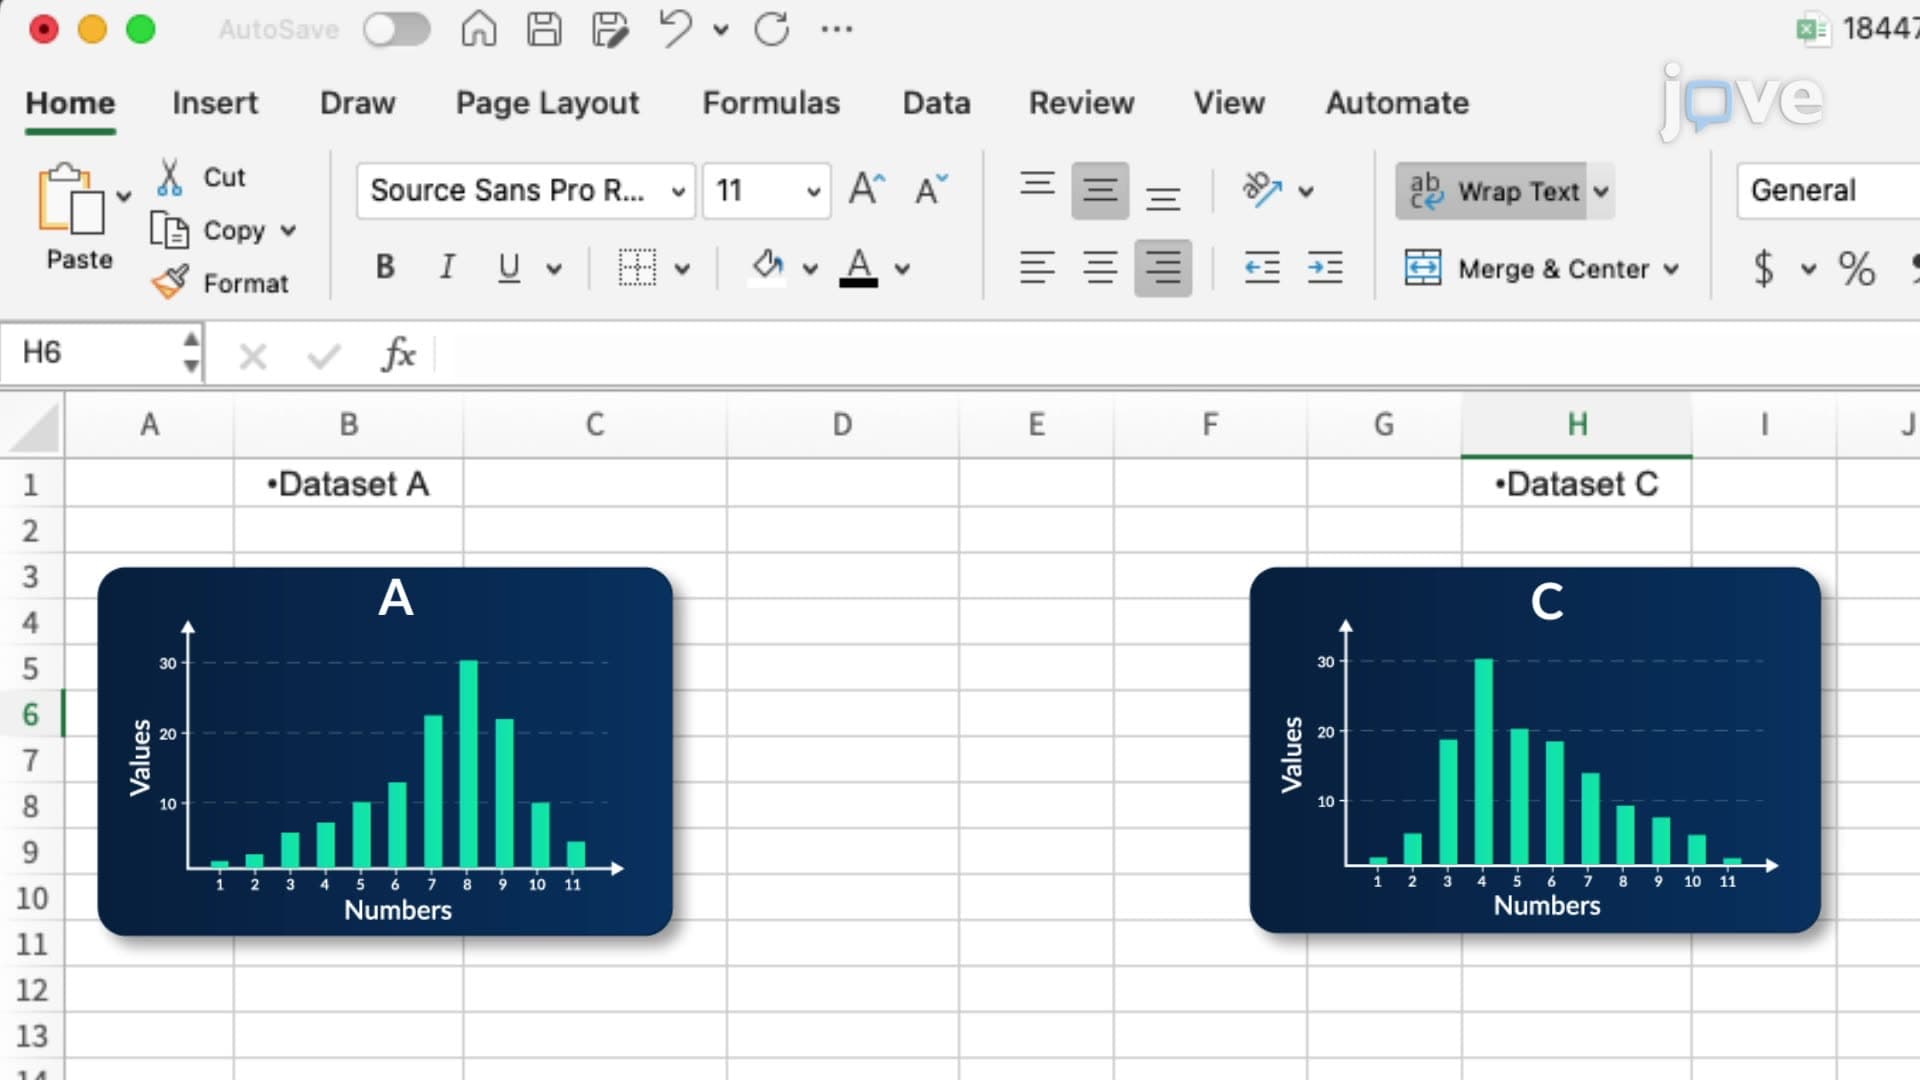
Central tendency refers to the central point or typical value of a dataset. It summarizes the data set with a single value that represents the center of its distribution. The three main measures of central tendency are:
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
135
 01:16
Contaminants and Errors
85
Effective sample preparation is crucial for accurate and reliable laboratory analysis. During this process, two significant sources of error can arise: concentration bias from improper sample splitting and contamination caused by methods used to reduce particle size, such as grinding or homogenization. Identifying and minimizing these potential errors is crucial to ensuring the validity of the analysis.
Another key consideration is determining the appropriate number of samples required to...
Another key consideration is determining the appropriate number of samples required to...
85