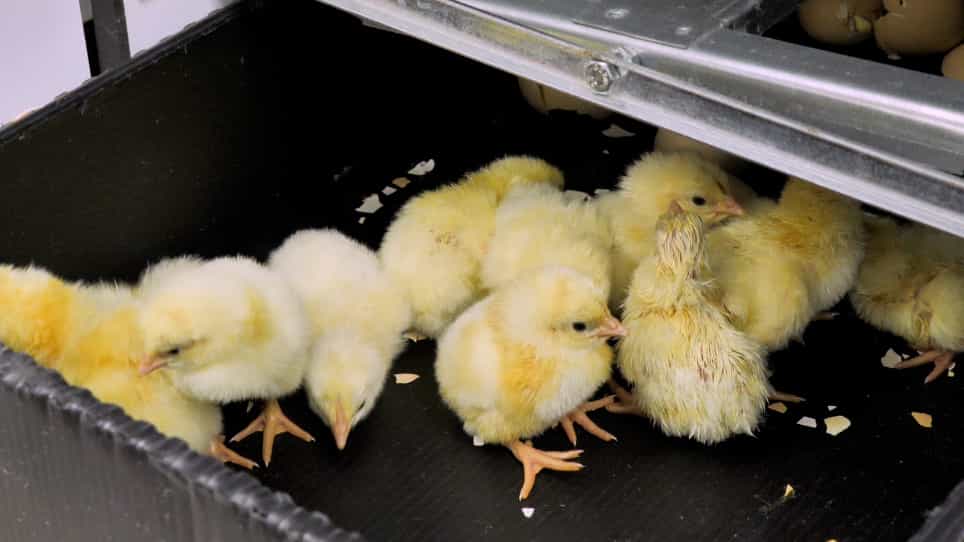

基于机器学习和沙普利的附加解释,预测肉养殖者的蛋生产率和蛋重量
Hengyi Ji1, Yidan Xu1, Ganghui Teng1
1College of Water Resources and Civil Engineering, China Agricultural University, Beijing, China; Key Laboratory of Agricultural Engineering in Structure and Environment, Ministry of Agriculture and Rural Affairs, Beijing 100083, China; Beijing Engineering Research Center for Animal Healthy Environment, Beijing 100083, China.
Poultry science
|November 15, 2024

概括
机器学习模型使用年龄,料摄入量和环境数据准确预测肉养殖蛋的产量和体重. XGBoost表现最好,提供了对提高农场效率的关键影响因素的见解.
科学领域:
- 禽畜科学 禽畜科学 禽畜科学
- 动物育种 动物育种
- 机器学习应用 机器学习应用
背景情况:
- 蛋生产率和蛋重量是肉养殖者表现的关键指标.
- 准确预测这些指标可以显著改善农场经济和战略规划.
- 关于应用机器学习 (ML) 来预测 brojiler繁殖者蛋产量和体重的研究是有限的.
研究的目的:
- 开发和比较ML模型,用于预测 brojiler繁殖者的蛋产量率和蛋重量.
- 确定影响这些预测的关键因素.
- 提高ML模型在这个领域的透明度和可信度.
主要方法:
- 收集了三家家禽舍的年龄,料摄入量,水消耗和环境因素 (温度,湿度,风速) 的数据.
- 训练并验证了七种ML模型:随机森林 (RF),多层感知器 (MLP),支持向量回归 (SVR),最小方程支持向量机器 (LSSVM),k-最近邻居 (kNN),XGBoost和LightGBM.
- 使用Shapley添加式解释 (SHAP) 进行模型解释.
主要成果:
- 在所有数据集中,XGBoost模型在预测蛋生产率和蛋重量方面表现出卓越的性能.
- XGBoost实现了低误差指标:MAE < 2.86%,RMSE < 4.17%,MAPE < 7.03%的蛋生产率;MAE < 0.63g,RMSE < 0.86g,MAPE < 1.1%的蛋重量.
- 确定卵产率的关键预测因素是年龄,料摄入量和有效温度 (ET);对于卵重量,它们是年龄,风速,温度湿度指数 (THI) 和ET.
结论:
- XGBoost 是一种高效的 ML 模型,用于预测 brojler 繁殖者蛋生产率和蛋重量.
- 使用SHAP的模型解释性为生产驱动因素提供了有价值的见解.
- 这项研究提供了通过准确的生产预测优化农场运营,资源配置和利能力的科学基础.
相关概念视频
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:19
Variation
6.7K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:11
Regression Analysis
5.6K
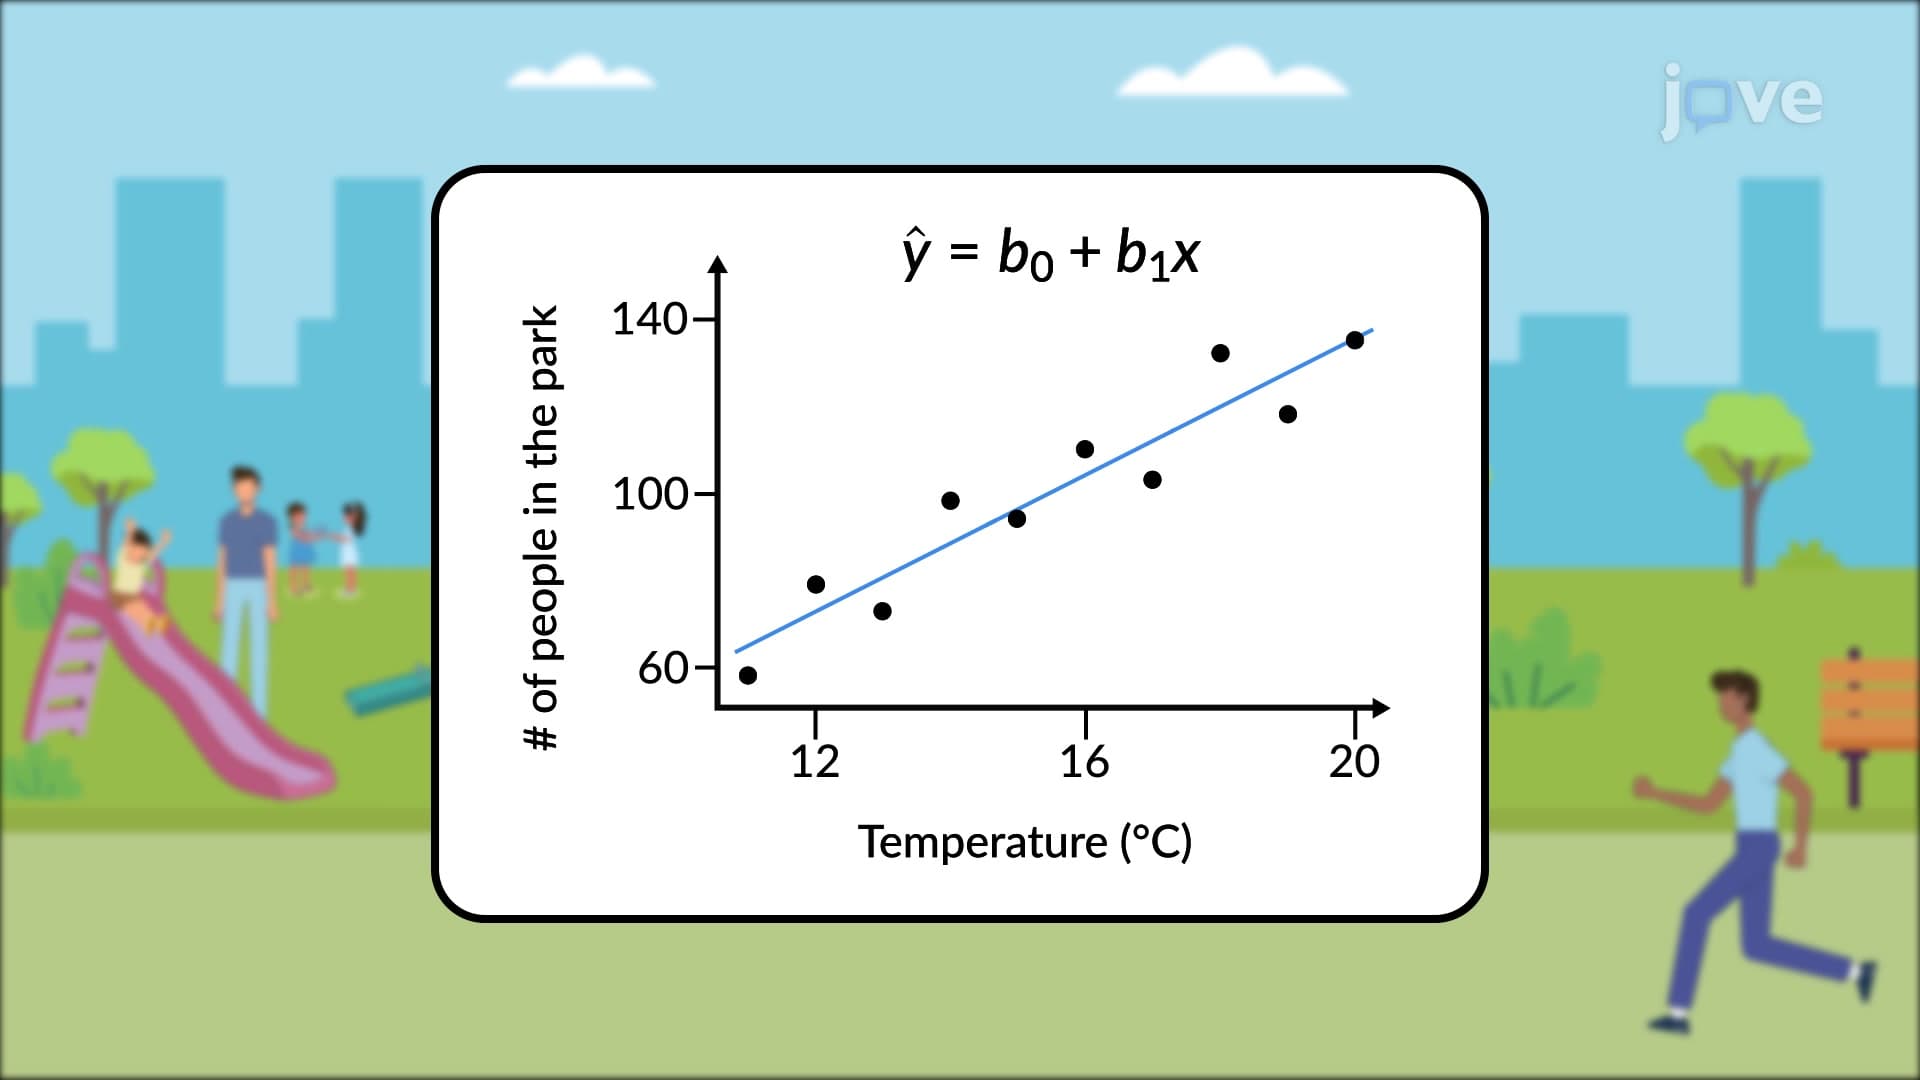
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:18
Microsoft Excel: Regression Analysis
488
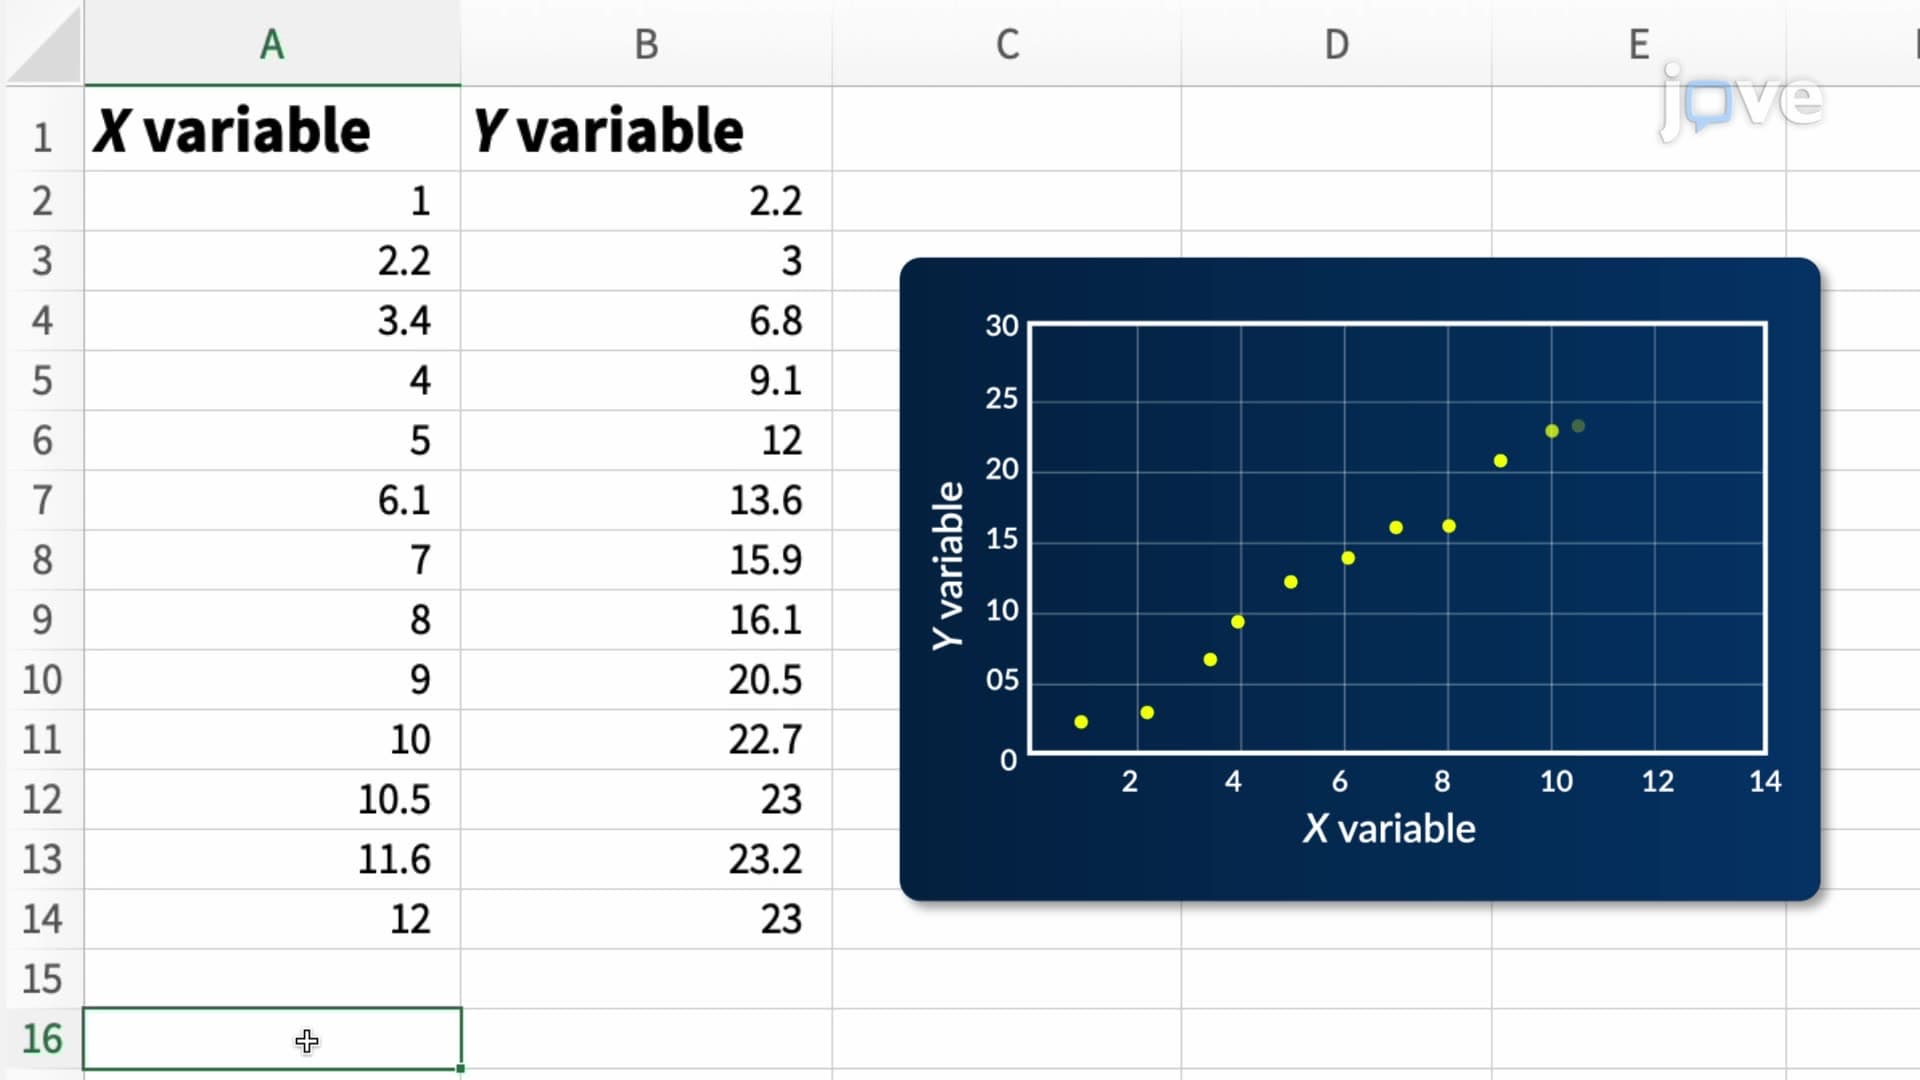
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
488