相关实验视频
Updated: Jun 6, 2025
07:13

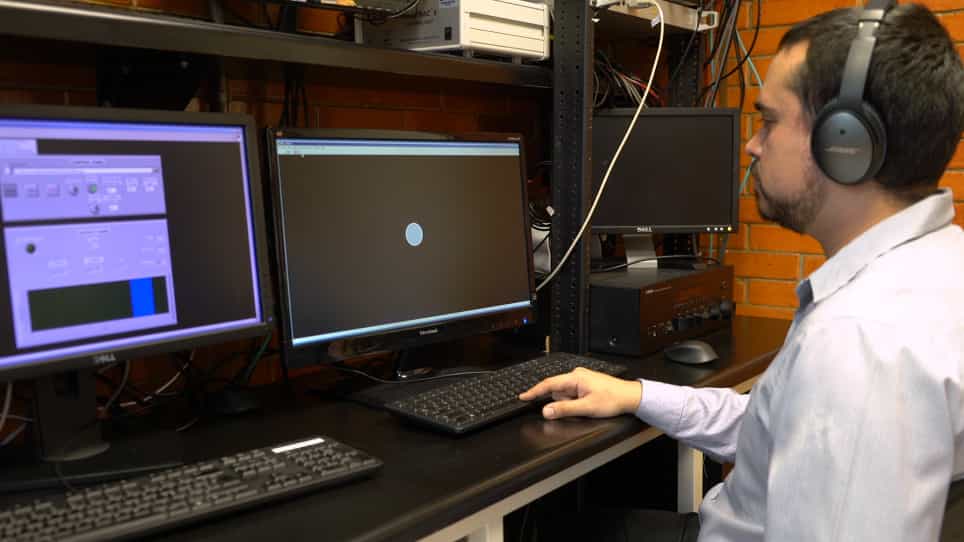
A Two-interval Forced-choice Task for Multisensory Comparisons
Published on: November 9, 2018
10.9K
在Thurstonian IRT模型中的人参数估计的统计基础,用于强制选择和对对比设计
1German Federal Employment Agency, Nuremberg, Germany.
The British journal of mathematical and statistical psychology
|November 27, 2024

概括
这项研究澄清了多变量瑟斯顿物品响应理论 (TIRT) 中的人参估计,用于对对比和强制选择数据. 它详细介绍了量化估计精度的准确方法,并解决了最大概率估计 (MLE) 的偏差.
科学领域:
- 心理测量 心理测量 心理测量
- 统计建模 统计建模
- 项目响应理论.
背景情况:
- 在Thurstonian项目响应理论 (TIRT) 模型中对人参数估计对对比和强制选择 (FC) 数据需要强大的统计基础.
- 目前用于量化估计精度的方法,例如定向信息,具有局限性,特别是当费舍尔信息矩阵不是对角时.
- 关于物件响应理论 (IRT) 和TIRT的误解需要澄清,以便在数据分析中准确应用.
研究的目的:
- 在多变量TIRT框架内详细阐述人参数估计的统计基础.
- 解决和纠正IRT和TIRT中常见的误解.
- 提供准确的方法来量化个人参数估计的精度.
主要方法:
- 使用反向费舍尔信息矩阵用于真实概率和反向戈达姆贝信息用于独立概率估计,对非对称共变量的量化.
- 分析表达式的推导用于真实的概率和费舍尔信息矩阵用于一般化的TIRT模型.
- 实施人参数的最大概率估计 (MLE) 和贝叶斯估计 (MAP),包括偏差量化和校正策略.
主要成果:
- 方向信息不适合量化估计精度,除非费舍尔信息矩阵是对角的.
- 反向的费舍尔信息矩阵和反向的戈达姆贝信息提供了对不对称共变率的准确测量.
- 对概率和信息矩阵的分析表达式使得强大的MLE和贝叶斯估计能够实现,并解决了偏差.
结论:
- 在多变量TIRT中为人参数估计建立了准确的统计基础,用于对对比和FC排名数据.
- 该研究提供了准确量化的修正方法,并解决了MLE中的偏差,提高了TIRT应用程序的可靠性.
- 对分级对对比的衍生边际概率为使用独立概率进行人参数估计提供了一个新的途径.

相关概念视频
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
1.6K
In parametric statistics, two fundamental tests stand out for their utility and wide application: the Student's t-test and goodness-of-fit tests. These tests provide researchers with a robust method for drawing insights from data, testing hypotheses, and making informed decisions based on their findings.
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
1.6K
 01:21
Friedman Two-way Analysis of Variance by Ranks
147
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
147
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
114
Statistical inference techniques, paramount in hypothesis testing, differentiate into two broad categories: parametric and nonparametric statistics.
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
114
 01:25
Choosing Between z and t Distribution
2.7K
The z and the Student t distribution estimate the population mean using the sample mean and standard deviation. However, to decide which distribution to use for a calculation, one needs to determine the sample size, the nature of the distribution, and whether the population standard deviation is known. If the population standard deviation is known and the population is normally distributed, or if the sample size is greater than 30, the z distribution is preferred. The Student t distribution is...
2.7K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:09
Comparing Experimental Results: Student's t-Test
1.5K
The t-test is a statistical method used to compare the sample mean with a population mean or compare two means from two data sets. The test statistic is calculated from the standard deviation, mean, and number of measurements in the data set at a selected confidence interval and then compared to a table of critical values at this confidence level. If the test statistic is smaller than the critical value, the null hypothesis is accepted. In this case, we state that the difference between the...
1.5K