

基于事实的决策树分析,以提高云计算的可靠性
Muhammad Asim Shahid1,2, Muhammad Mansoor Alam1,3,4,5, Mazliham Mohd Su'ud5
1Malaysian Institute of Information Technology, Universiti Kuala Lumpur, Kuala Lumpur, Malaysia.
PloS one
|December 3, 2024

概括
这项研究比较了用于云计算故障预测的五种机器学习算法. 修改后的决策树 (J48) 算法实现了最高的准确性 (97.07%) 与最小的故障预测错误.
科学领域:
- 计算机科学 计算机科学
- 机器学习 机器学习
- 云计算 云计算 云计算 云计算
背景情况:
- 由于成本效益和可扩展性,云计算 (CC) 的采用正在迅速增加.
- 企业正在迁移到云端,以提高可访问性和透明度.
- 准确的故障预测对于可靠的云基础设施至关重要.
研究的目的:
- 为了比较五种机器学习算法的准确性和故障预测能力.
- 确定用于云计算故障预测的最有效算法.
- 建议修改以提高所选择的算法的性能.
主要方法:
- 评估了AdaBoostM1,包装,决策树 (J48),深度学习 (Dl4jMLP) 和天真贝叶斯树 (NB树) 算法.
- 使用二次数据分析进行初始比较.
- 通过80/20,70/30和10倍的交叉验证分割进行了初级数据分析.
- 测量准确率和每个算法的故障预测错误.
主要成果:
- 纯粹的贝叶斯树 (NB树) 显示出高精度 (97.05%) 但时间复杂性差 (1.01s).
- 决策树 (J48) 提供了类似的准确性 (96.78%) 与显著更好的时间复杂性 (0.11s).
- 修改的决策树 (J48) 在验证分割中实现了最高的准确性 (高达97.07%),具有较低的故障预测.
结论:
- 决策树 (J48) 算法,经过修改,对于云计算故障预测非常有效.
- 增强的J48算法平衡了高精度与高效的计算性能.
- 这项研究为提高云系统可靠性提供了强大的解决方案.
相关概念视频
 01:19
Survival Tree
60
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
60
 01:25
Distribution Reliability and Automation
105
Distribution reliability in electrical power systems is critical for ensuring an uninterrupted power supply to consumers at minimal cost. According to IEEE Standard Terms, reliability is the probability that a device will function without failure over a specified time period or amount of usage. For electric power distribution, this translates to maintaining continuous power supply and addressing customer concerns over power outages. Several indices, as defined by IEEE Standard 1366-2012, are...
105
 01:14
Decision Making: Traditional Method
4.0K
The process of hypothesis testing based on the traditional method includes calculating the critical value, testing the value of the test statistic using the sample data, and interpreting these values.
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
4.0K
 01:09
Decision Making: P-value Method
5.3K
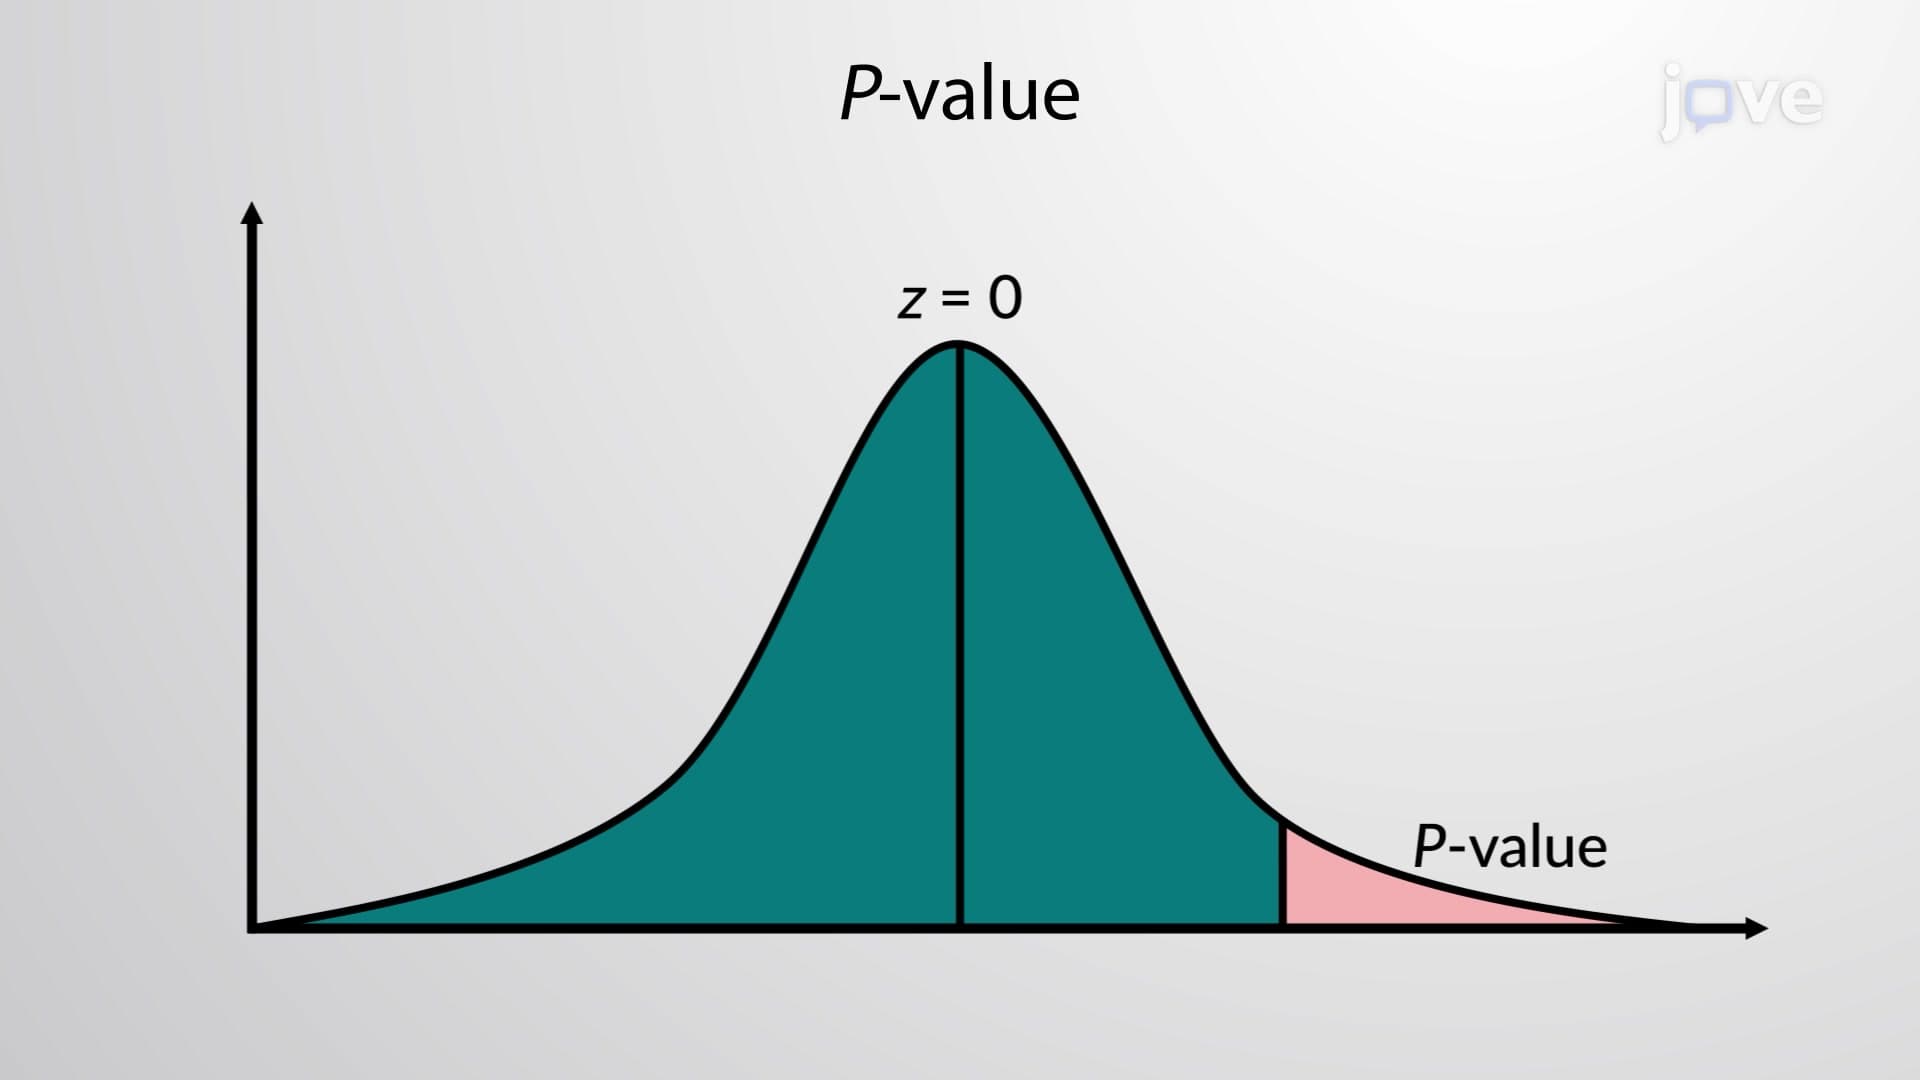
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.3K
 01:29
Reliability and Validity
12.7K
Reliability and validity are two important considerations that must be made with any type of data collection. Reliability refers to the ability to consistently produce a given result. In the context of psychological research, this would mean that any instruments or tools used to collect data do so in consistent, reproducible ways.
12.7K
 01:11
Regression Analysis
5.6K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K