用可解释的机器学习算法预测孟加拉国五岁以下儿童的营养不良和确定其影响预测因子
Md Merajul Islam1,2, Nobab Md Shoukot Jahan Kibria1, Sujit Kumar1
1Department of Statistics, Jatiya Kabi Kazi Nazrul Islam University, Trishal, Mymensingh, Bangladesh.
PloS one
|December 6, 2024

概括
机器学习模型可以预测孟加拉国的儿童营养不良风险. 关键预测因素包括父母的教育,财富和孩子.
科学领域:
- 儿童健康 儿童健康
- 机器学习应用程序 机器学习应用程序
- 全球公共卫生全球公共卫生
背景情况:
- 儿童营养不良是一个关键的全球卫生问题,特别是在孟加拉国等发展中国家.
- 识别和预测营养不良风险对于有针对性的干预措施至关重要.
研究的目的:
- 开发孟加拉国儿童营养不良风险的预测模型.
- 通过使用可解释的人工智能来识别衰老,消耗和体重不足的关键预测因素.
主要方法:
- 利用了孟加拉国人口与健康调查 (BDHS) 2017-18年数据.
- 采用Boruta技术进行预测器选择和XGBoost,随机森林,ANN和后勤回归进行预测.
- 应用了SHapley添加式解释 (SHAP) 来实现模型的可解释性.
主要成果:
- 极端梯度增强 (XGB) 模型在预测营养不良方面表现出卓越的表现.
- 确定了重要的预测因素,包括父亲的教育,母亲的教育,财富和孩子的BMI.
- SHAP分析提供了有关各种社会经济和健康因素影响的详细见解.
结论:
- 综合框架有效预测营养不良风险,并确定关键影响因素.
- 这些发现支持针对性的战略,以打击孟加拉国的儿童营养不良.
相关概念视频
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
27
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
27
 01:19
Variation
6.7K
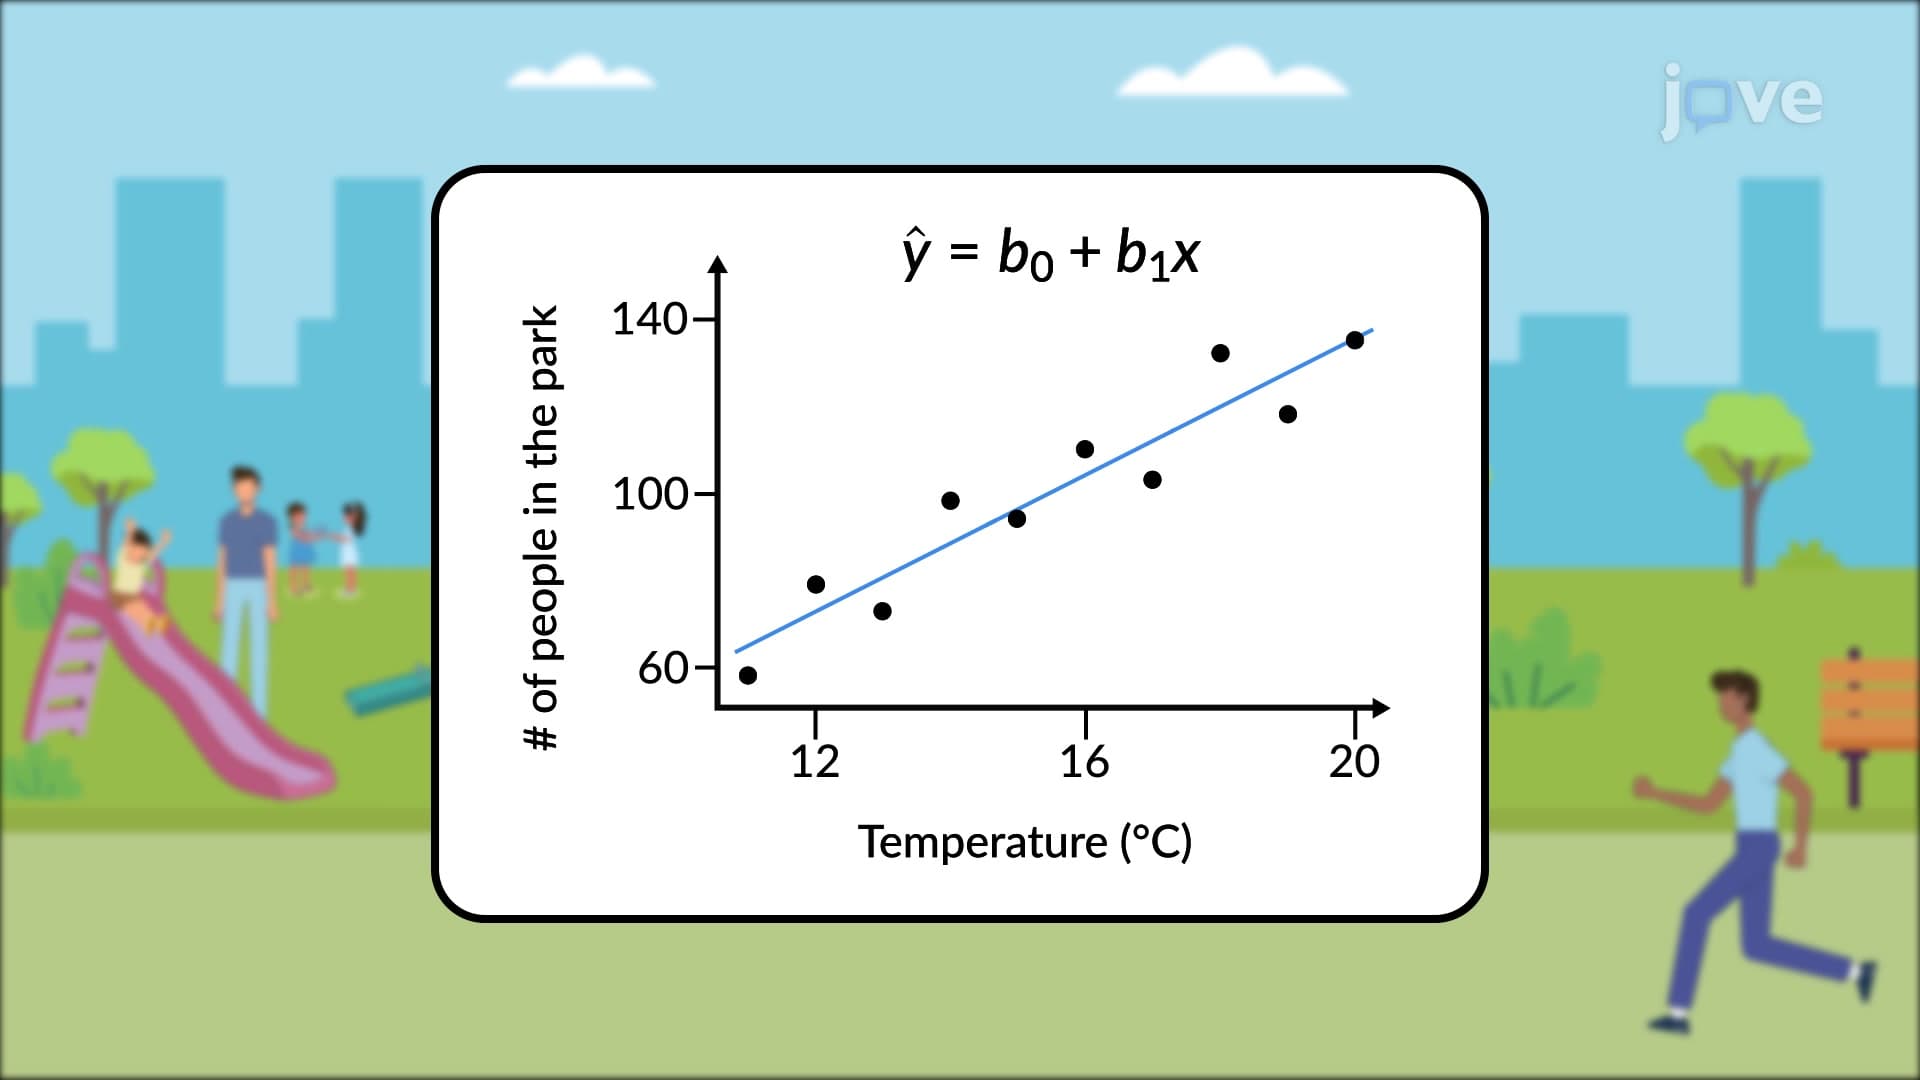
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:11
Regression Analysis
5.6K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K