相关实验视频
Updated: May 29, 2025
13:51

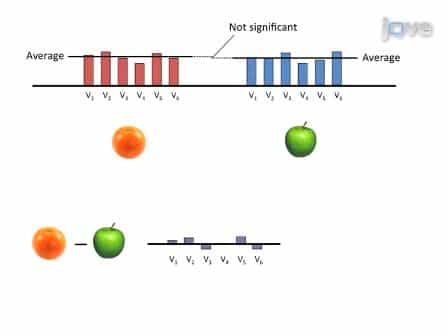
Cross-Modal Multivariate Pattern Analysis
Published on: November 9, 2011
19.9K
心理研究中的交叉验证和预测指标:不要忽略离开-一个-离开
Diego Iglesias1, Miguel A Sorrel2, Ricardo Olmos2
1Faculty of Psychology, Department of Social Psychology and Methodology, Universidad Autónoma de Madrid, 6 Iván Pavlov Street, Cantoblanco Campus, 28049, Madrid, Spain. diego.iglesias@uam.es.
Behavior research methods
|February 3, 2025

概括
本研究引入了一种新的交叉验证 (CV) 方法,用于估计心理研究中的预测误差. 抛出一个 (LOO) 方法显示了R平方度量表的优异性能,提高了预测建模的准确性.
科学领域:
- 心理学研究方法 心理学研究方法
- 统计建模 统计建模
- 行为科学 行为科学
背景情况:
- 越来越多的人对将解释性和预测性研究纳入心理学感兴趣.
- 交叉验证 (CV) 对于估计预测错误至关重要,但需要适应特定环境.
- 现有的CV方法对于特定的预测指标 (如R平方) 有局限性.
研究的目的:
- 评估不同CV方法的性能,以估计回归分析中的预测误差.
- 为了解决目前CV实践中的R平方度的限制.
- 提出和验证一个改进的CV方法用于R平方估计.
主要方法:
- 各种CV技术的比较,包括k-fold和leave-one-out (LOO).
- 在回归分析中使用R平方和另一个指标进行性能评估.
- 两个蒙特卡洛模拟研究和分析许多实验室复制项目的数据.
- 在R包中讨论的CV方法的实施OutR2.
主要成果:
- 抛出一个 (LOO) 交叉验证方法始终显示出估计预测错误的最佳性能.
- 拟议的LOO方法克服了R平方度的传统方法的局限性.
- R包OutR2提供了这些CV方法的可访问的实现.
结论:
- 抛出一个方法 (LOO) 是一种可靠且优越的方法,用于估计心理研究中的预测误差,特别是对R平方度量.
- 准确的预测错误估计对于成功整合预测和解释性研究至关重要.
- 该OutR2 R套件促进了在心理学研究中应用先进的CV技术.
相关概念视频
 01:16
Crossover Experiments
2.7K
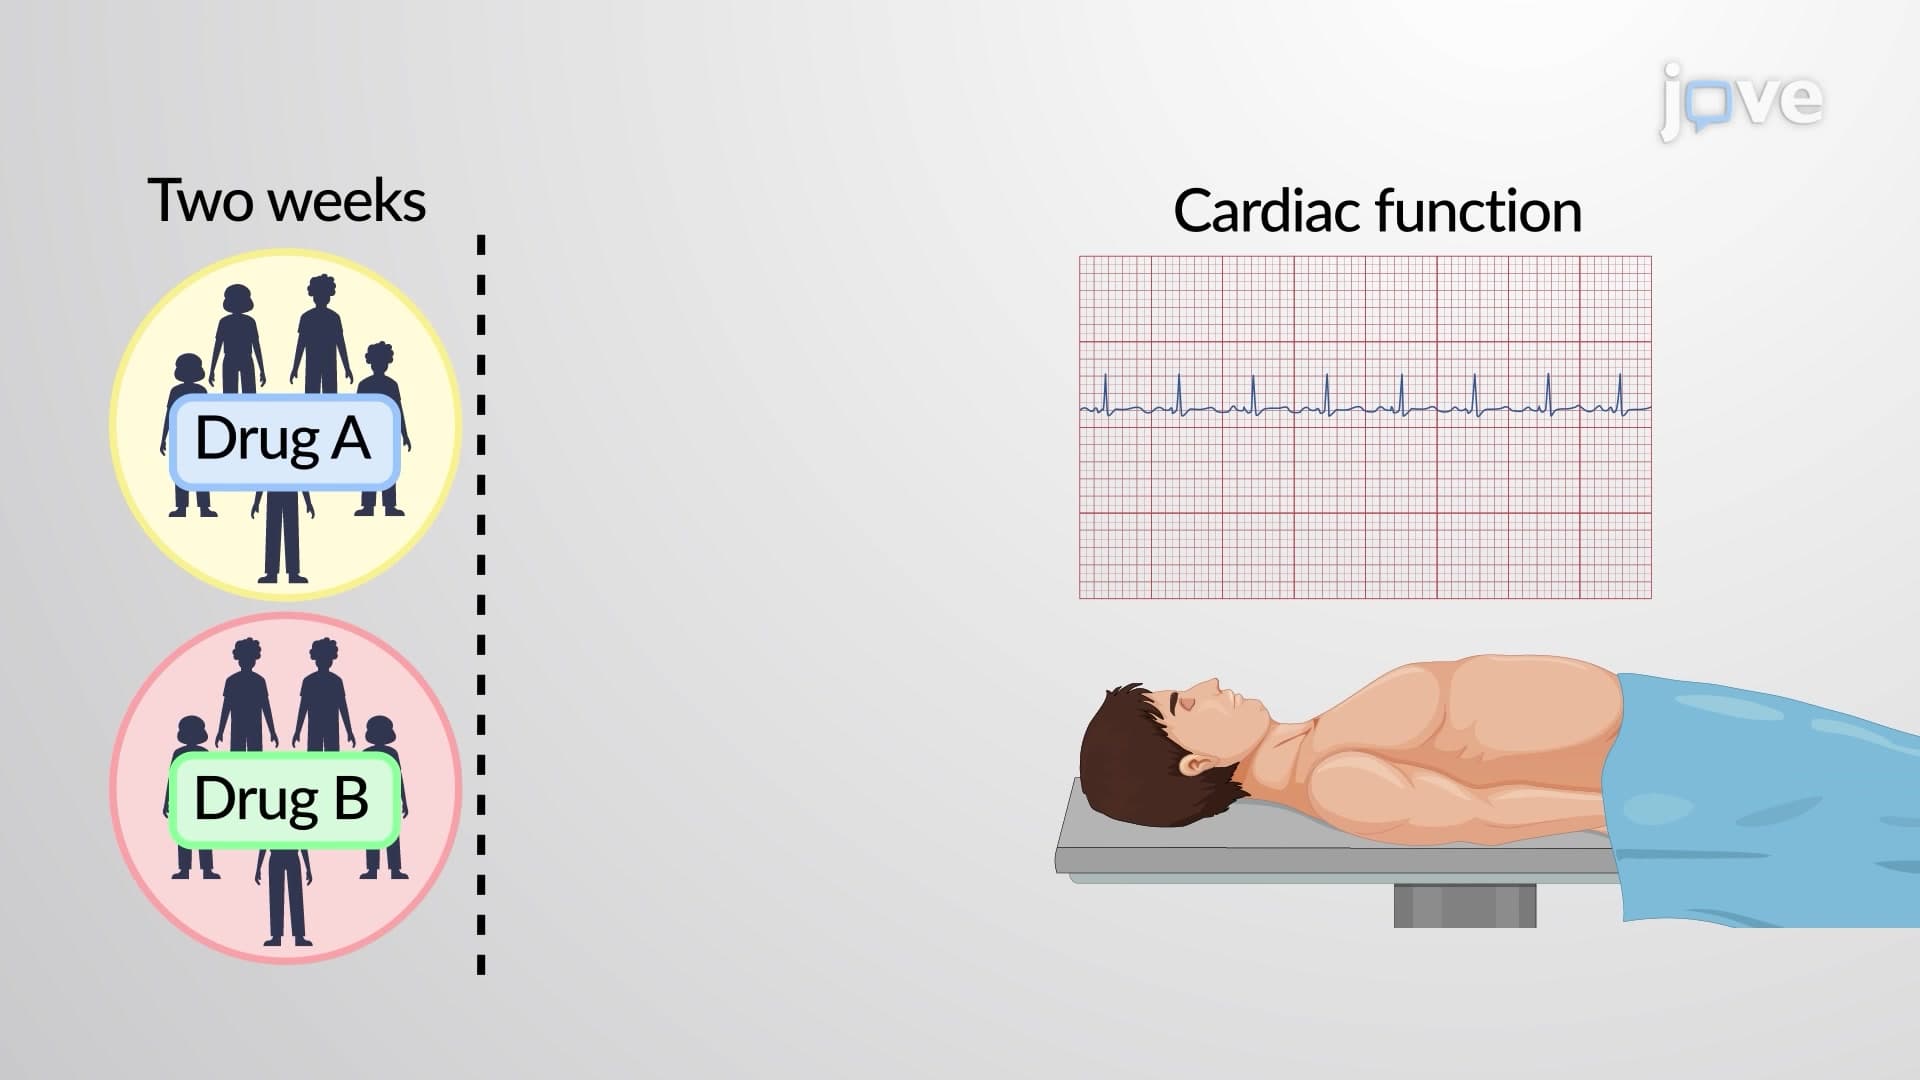
Crossover experiments, also called the repeated-measurements design, is a study design in which all experimental units are exposed to all treatments in different periods. Crossover experiments are generally used in psychology, the pharmaceutical industry, agriculture, and medicine.
Crossover designs are performed even with smaller sample sizes since the samples can act as their controls. These are better than simple randomized trials since patients are exposed to all the treatments.
Crossover designs are performed even with smaller sample sizes since the samples can act as their controls. These are better than simple randomized trials since patients are exposed to all the treatments.
2.7K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 02:01
Group Design
8.9K
The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between...
8.9K
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:08
Outliers and Influential Points
4.0K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.0K