PyViscount:通过随机搜索空间分区验证虚假发现率估计方法
1Department of Chemical and Biological Engineering, The Hong Kong University of Science and Technology, Hong Kong 999077, China.
Journal of proteome research
|February 5, 2025

概括
在猎枪蛋白质组学中验证错误发现率 (FDR) 估计至关重要. PyViscount提供了一种使用随机搜索空间分区的新方法,用于在没有合成数据的情况下进行可靠的FDR验证.
科学领域:
- 蛋白质组学是指蛋白质组学.
- 生物信息学是一种生物信息学.
- 计算生物学 计算生物学
背景情况:
- 错误发现率 (FDR) 估计对于猎枪蛋白质组学方法的开发至关重要.
- 现有的验证协议经常使用操纵的数据集,限制了现实世界的适用性.
- 将估计的FDR与地面真相进行比较可能不会反映自然数据场景.
研究的目的:
- 介绍PyViscount,这是用于FDR估计验证的Python工具.
- 使用随机搜索空间分区开发一个新的验证协议.
- 通过不变的搜索空间和通用光谱,实现准地面真相生成.
主要方法:
- 实现了PyViscount,这是一个用于FDR验证的Python工具.
- 利用随机搜索空间分区进行准地面真相生成.
- 采用了独特的候选和通用实验光谱的不变的搜索空间.
主要成果:
- PyViscount为FDR估计提供了一个新的验证协议.
- 该工具使用自然数据属性生成准基础真相.
- 使用PyViscount的验证结果与现有协议保持一致.
结论:
- PyViscount提供了一个强大的替代方案,用于在猎枪蛋白质组学中验证FDR.
- 该方法避免了合成数据和数据操纵,提高了可靠性.
- 为蛋白质组学从业者提供了对FDR估计方法性能更深入的见解.
相关概念视频
 01:17
Wald-Wolfowitz Runs Test II
174
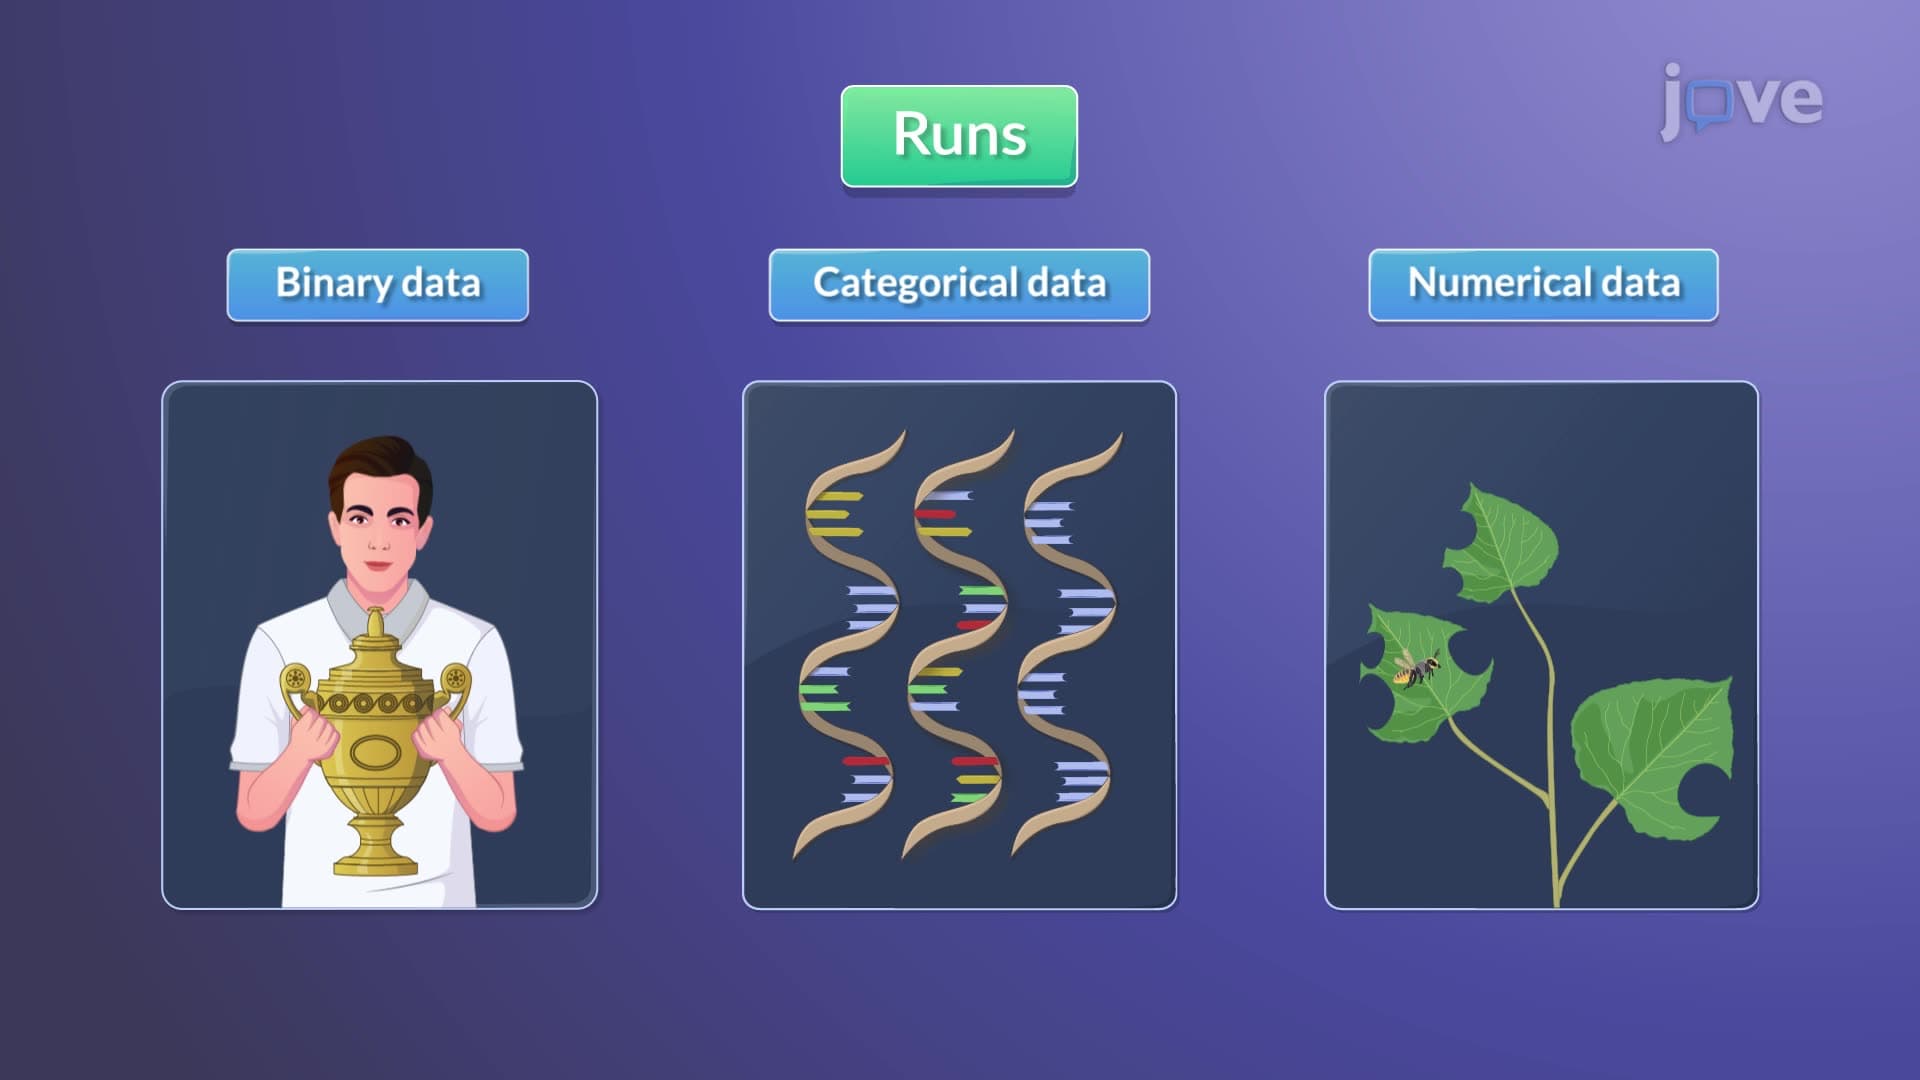
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
174
 01:17
Wald-Wolfowitz Runs Test I
597
The Wald-Wolfowitz test, also known as the runs test, is a nonparametric statistical test used to assess the randomness of a sequence of two different types of elements (e.g., positive/negative values, successes/failures). It examines whether the order of the elements in a sequence is random or if there is a pattern or trend present. This nonparametric test applies to any ordered data despite the population and sample data distribution, even if a higher sample size is available.
The test works...
The test works...
597
 01:08
Fisher's Exact Test
316
Fisher's exact test is a statistical significance test widely used to analyze 2x2 contingency tables, particularly in situations where sample sizes are small. Unlike the chi-squared test, which approximates P-values and assumes minimum expected frequencies of at least five in each cell, Fisher's exact test calculates the exact probability (P-value) of observing the data or more extreme results under the null hypothesis. This feature makes it especially valuable when the assumptions of...
316
 01:19
Testing a Claim about Standard Deviation
2.4K
A complete procedure to test a claim about population standard deviation or population variance is explained here.
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
2.4K
 01:16
Unusual Results
3.1K
Unusual results are those that have a very low chance of occurring. Unusual results can be identified using probabilities and the range rule of thumb. In problems involving probability, unusual results can be observed in 2 instances – an unusually high number of successes or an unusually low number of successes.
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
3.1K
 01:13
Randomized Experiments
6.7K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.7K