

增长参数估计的可变性 - 调整尺度和重新参数化的作用
Maha Rockaya1, József Baranyi1
1Doctoral School of Food Science and Nutrition, University of Debrecen, Hungary.
Food microbiology
|February 14, 2025

概括
这项研究通过分析错误估计来提高预测微生物学模型的可靠性. 调整尺度和重新参数化改进了参数估计,这对于准确的食品安全决策至关重要.
科学领域:
- 预测性微生物学 预测性微生物学
- 食品安全科学 食品安全科学
- 统计建模 统计建模
背景情况:
- 预测性微生物学模型对于食品安全至关重要.
- 在模型参数中准确的错误估计对于可靠的预测至关重要.
- 现有的模型可能在参数估计可靠性方面存在局限性.
研究的目的:
- 分析预测微生物学模型中错误估计的可靠性.
- 证明重新缩放和重新参数化的应用,以提高可靠性.
- 为了比较Baranyi和Roberts模型 (BRM) 和Gompertz函数 (GF) 的可靠性.
主要方法:
- 使用主要模型,如Baranyi和Roberts (BRM) 和Gompertz函数 (GF) 的适合生长参数.
- 在模型参数上应用重新缩放和重新参数化技术.
- 分析标准错误的分布,以估计最大特定增长率.
- 在参数估计中对变化和相关性来源进行分类 ("湿"和"干").
主要成果:
- 调整尺寸和重新参数化可以改善线性,同型多样性,并降低模型复杂性.
- 这些技术减轻了影响参数估计的统计 ("干燥") 关系.
- 巴拉尼和罗伯茨模型 (BRM) 匹配显示了一个更接近线性回归的错误结构.
- 在使用传统的t分布假设来构建置信区间时,BRM更可靠.
结论:
- 调整尺寸和重新参数化是提高预测微生物学模型可靠性的宝贵工具.
- 与戈默茨函数相比,巴拉尼和罗伯茨模型在参数估计和置信区间构建方面表现出更高的可靠性.
- 改进的错误估计对于食品安全应用中可靠的决策至关重要.
更多相关视频
 07:38
Saccharomyces cerevisiae Exponential Growth Kinetics in Batch Culture to Analyze Respiratory and Fermentative Metabolism
Published on: September 30, 2018
41.7K
 11:41
Real Time and Repeated Measurement of Skeletal Muscle Growth in Individual Live Zebrafish Subjected to Altered Electrical Activity
Published on: June 16, 2022
1.9K
相关概念视频
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
334
Parametric survival analysis models survival data by assuming a specific probability distribution for the time until an event occurs. The Weibull and exponential distributions are two of the most commonly used methods in this context, due to their versatility and relatively straightforward application.
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
334
 01:26
Distributions to Estimate Population Parameter
4.0K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.0K
 01:11
Variability: Analysis
125
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
125
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:06
What are Estimates?
4.9K
It isn't easy to measure a parameter such as the mean height or the mean weight of a population. So, we draw samples from the population and calculate the mean height or mean weight of the individuals in the sample. This sample data acts as a representative measure of the population parameter. These sample statistics are known as estimates.
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
4.9K
 01:19
Variation
6.7K
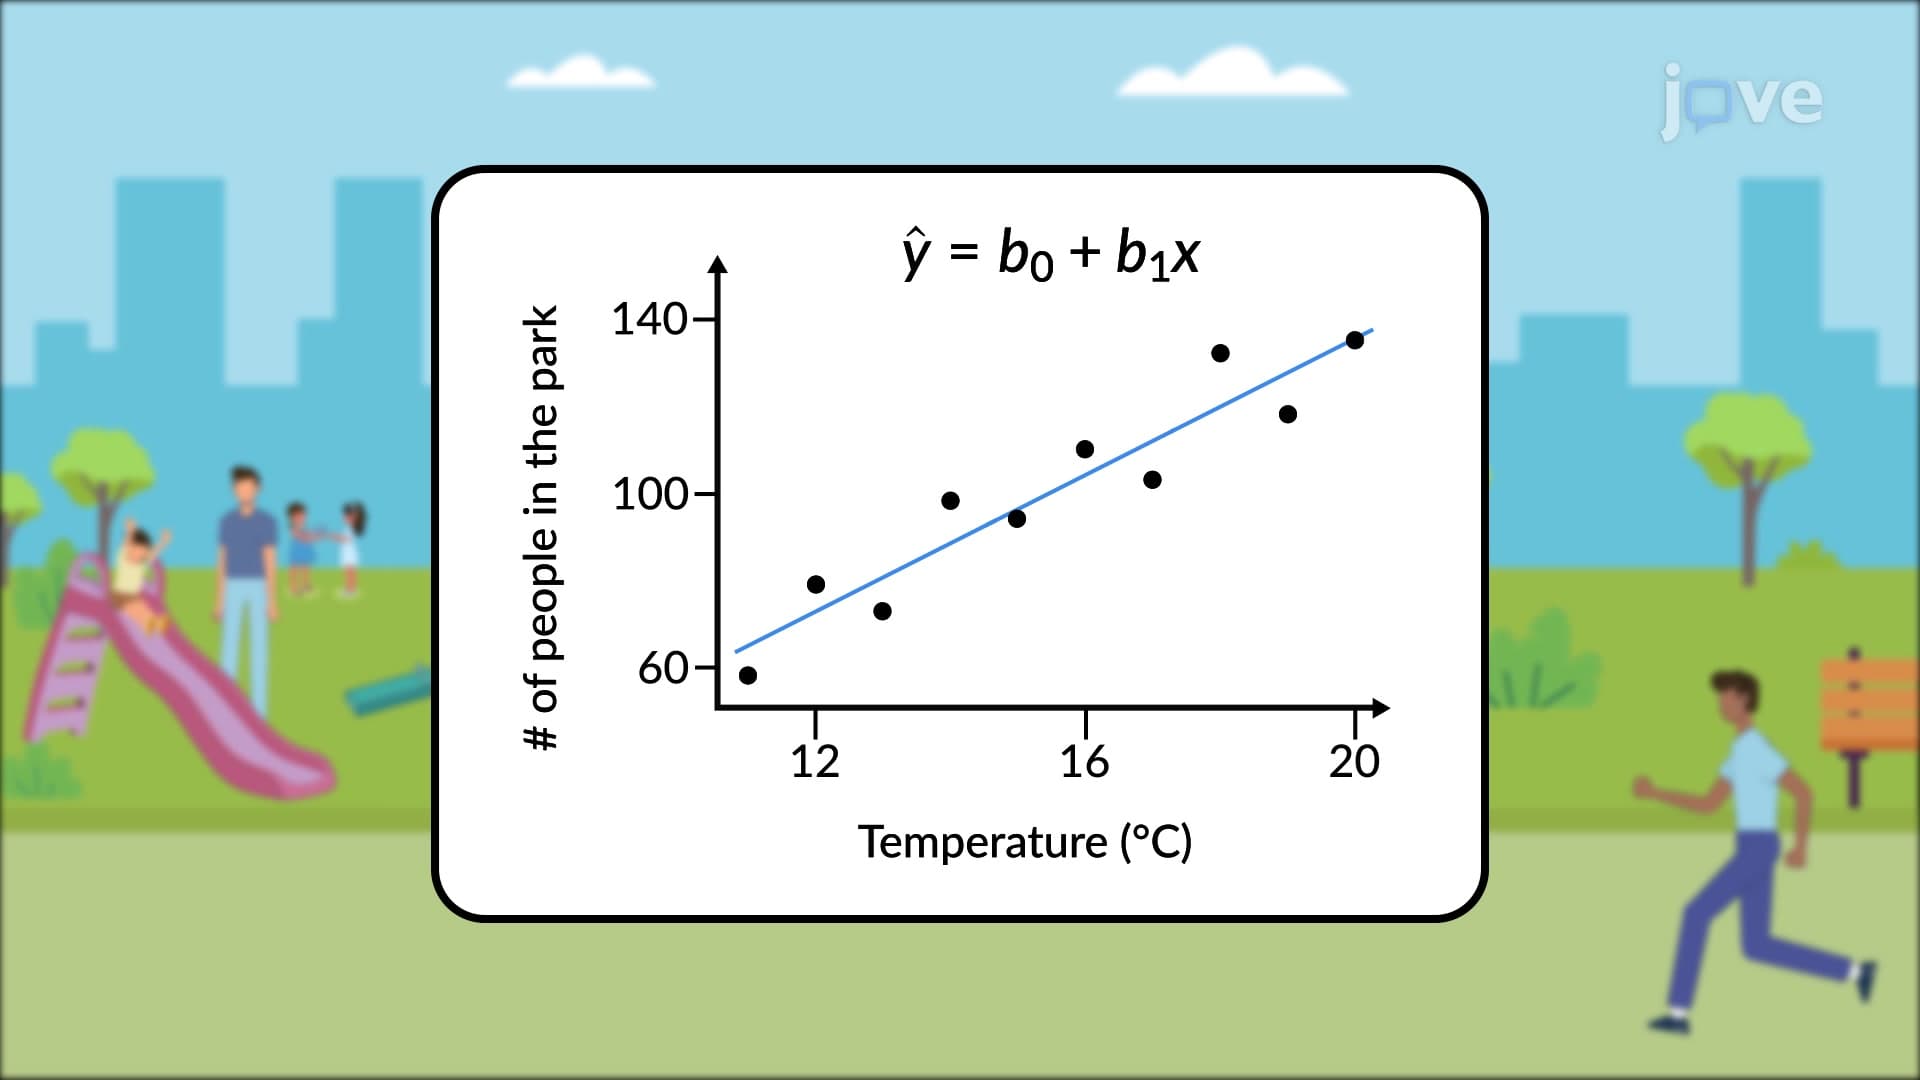
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K