
对混合效应的模型选择 位置尺度模型与LOO或WAIC差异的置信区间
Yue Liu1, Fan Fang2, Hongyun Liu3,4
1Institute of Brain and Psychological Sciences, Sichuan Normal University, Chengdu, China.
Multivariate behavioral research
|February 18, 2025

概括
使用置信区间的顺序方法提高了贝叶斯模型选择准确性,用于混合效应的位置尺度模型 (MELSMs),而不是点估计. 这种方法可以提高模型的性能,特别是在更简单的模型或更大的样本大小的情况下.
科学领域:
- 贝叶斯统计学 贝叶斯统计学
- 统计建模 统计建模
- 计量经济学 计量经济学 计量经济学
背景情况:
- 交叉验证 (LOO) 和广泛适用的信息标准 (WAIC) 是贝叶斯模型选择的标准.
- 目前的做法往往依赖于点估计,忽视了模型合适指数固有的不确定性.
- 这种监督会导致在复杂的统计分析中做出低于最佳的模型选择.
研究的目的:
- 介绍和评估一个新的序列方法,用于贝叶斯模型比较.
- 拟议的方法使用LOO或WAIC的置信区间,解决点估计中的不确定性.
- 评估这种顺序方法在选择混合效应位置尺度模型 (MELSMs) 的有效性.
主要方法:
- 一项模拟研究旨在将拟议的顺序方法与传统的点估计方法进行比较.
- 重点是选择合适的混合效应位置规模模型 (MELSM).
- 使用信心区间 (具体为90%) 来评估适应指数 (LOO和WAIC).
主要成果:
- 顺序方法在特定条件下 (简单的真实模型,规模模型中的大型随机拦截,大样本大小) 与点方法相比,显示出更高的模型选择精度.
- 通过顺序方法选择的模型表现出更好的统计特性:更高的功率,更窄的可信区间,固定效应的标准误差减少,随机效应的偏差更低.
- 只有在小的1级样本大小中才出现LOO和WAIC之间的显著差异,在均或异质残余差异的情况下有利于LOO.
结论:
- 序列模型比较方法,利用置信区间,为MELSMs的贝叶斯模型选择提供了更强大的方法.
- 这种技术通过考虑估计不确定性来提高模型选择的可靠性.
- 这些发现为使用贝叶斯统计学的研究人员提供了宝贵的指导,特别是在处理混合效应模型时.
相关概念视频
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
340
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
340
 01:21
Confidence Intervals
6.1K
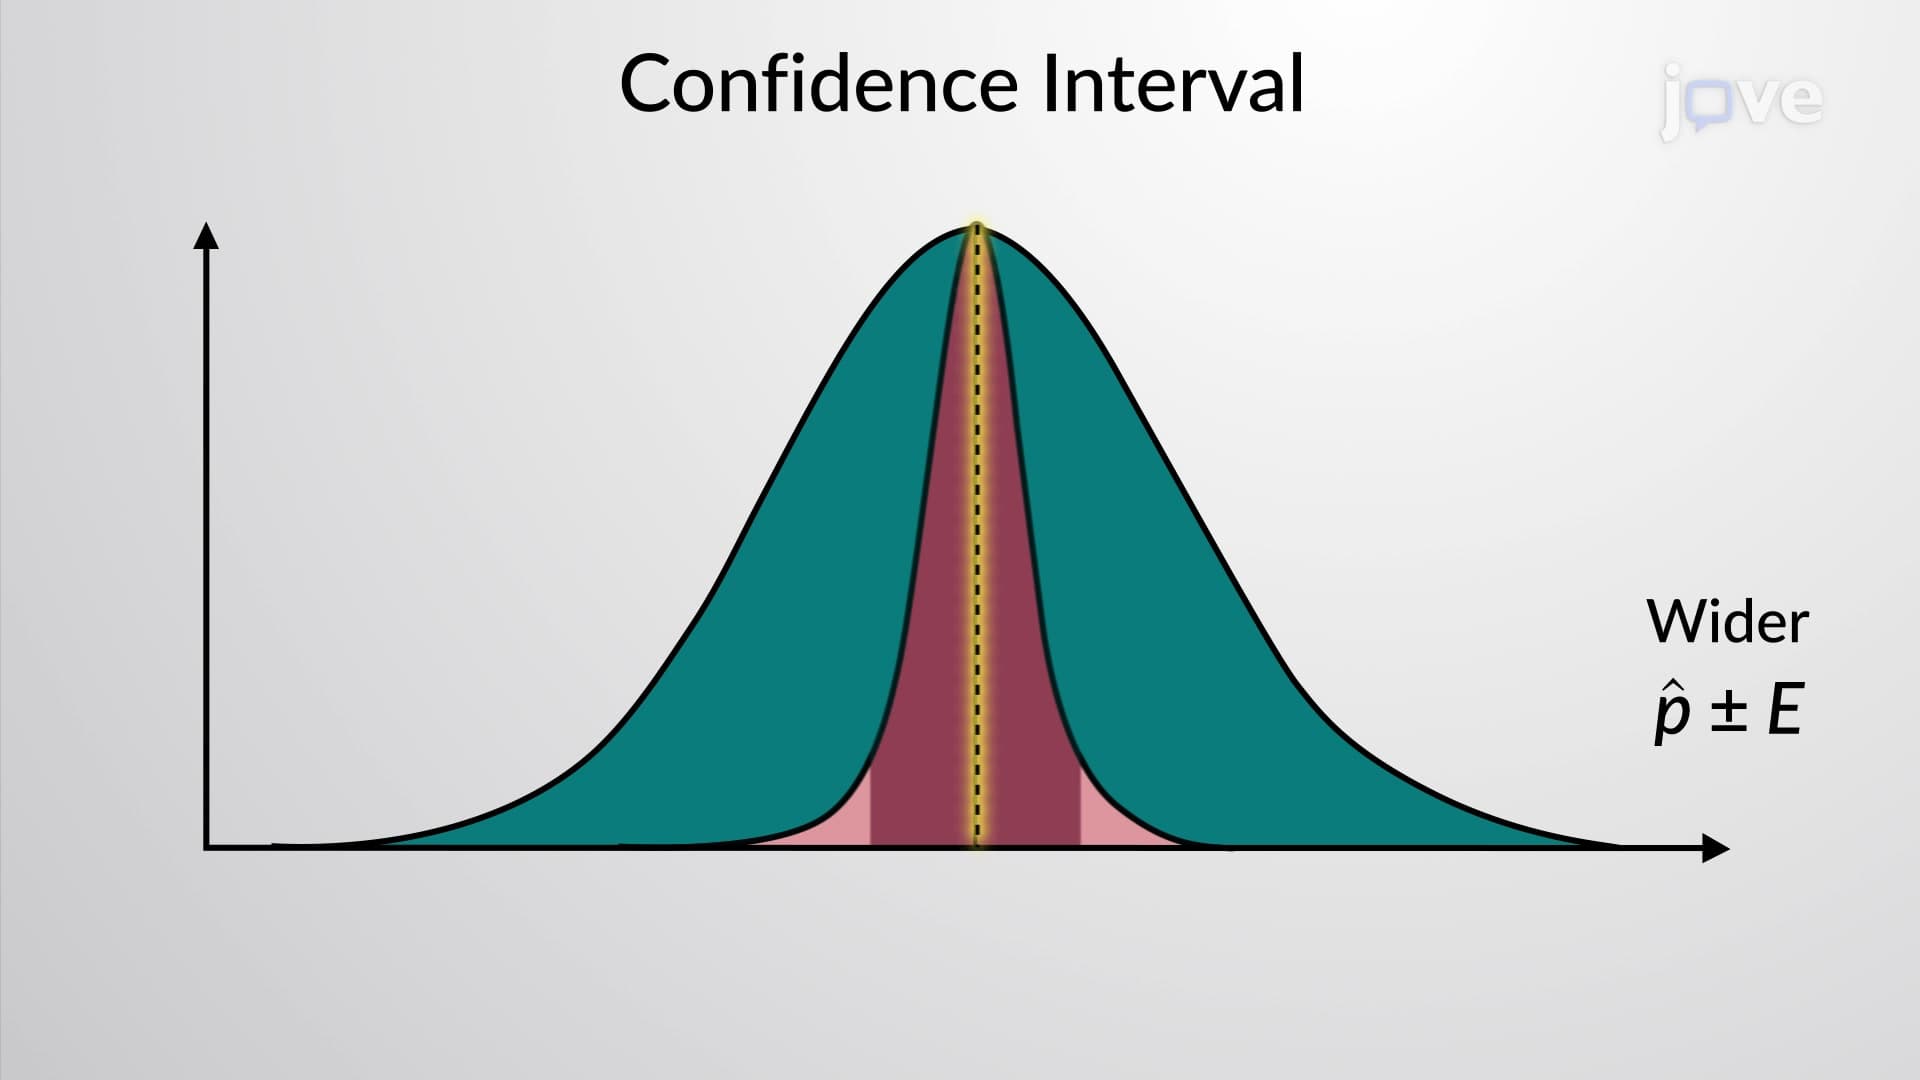
An unbiased point estimate is often insufficient to predict a population estimate, such as population mean or population proportion. In this scenario, a confidence interval is used. A confidence interval is an estimate similar to a sample proportion. However, unlike the point estimate which is a single value, the confidence interval contains a range of values. These values have lower and upper limits, known as confidence limits, and can be designated as L1 and L2, respectively.
A...
A...
6.1K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
25
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
25
 01:25
Confidence Interval for Estimating Population Mean
7.2K
A point estimate of the population mean is obtained from a single sample. Such a point estimate does not represent a population well because it needs to account for variability in the population. Single point estimate can also be biased despite the sample being selected randomly. Thus, a point estimate is often unreliable. A confidence interval is needed to reduce this unreliability.
A confidence interval for the mean is a range of values that provides an estimate of the population mean. As the...
A confidence interval for the mean is a range of values that provides an estimate of the population mean. As the...
7.2K
 01:19
Interpretation of Confidence Intervals
5.6K
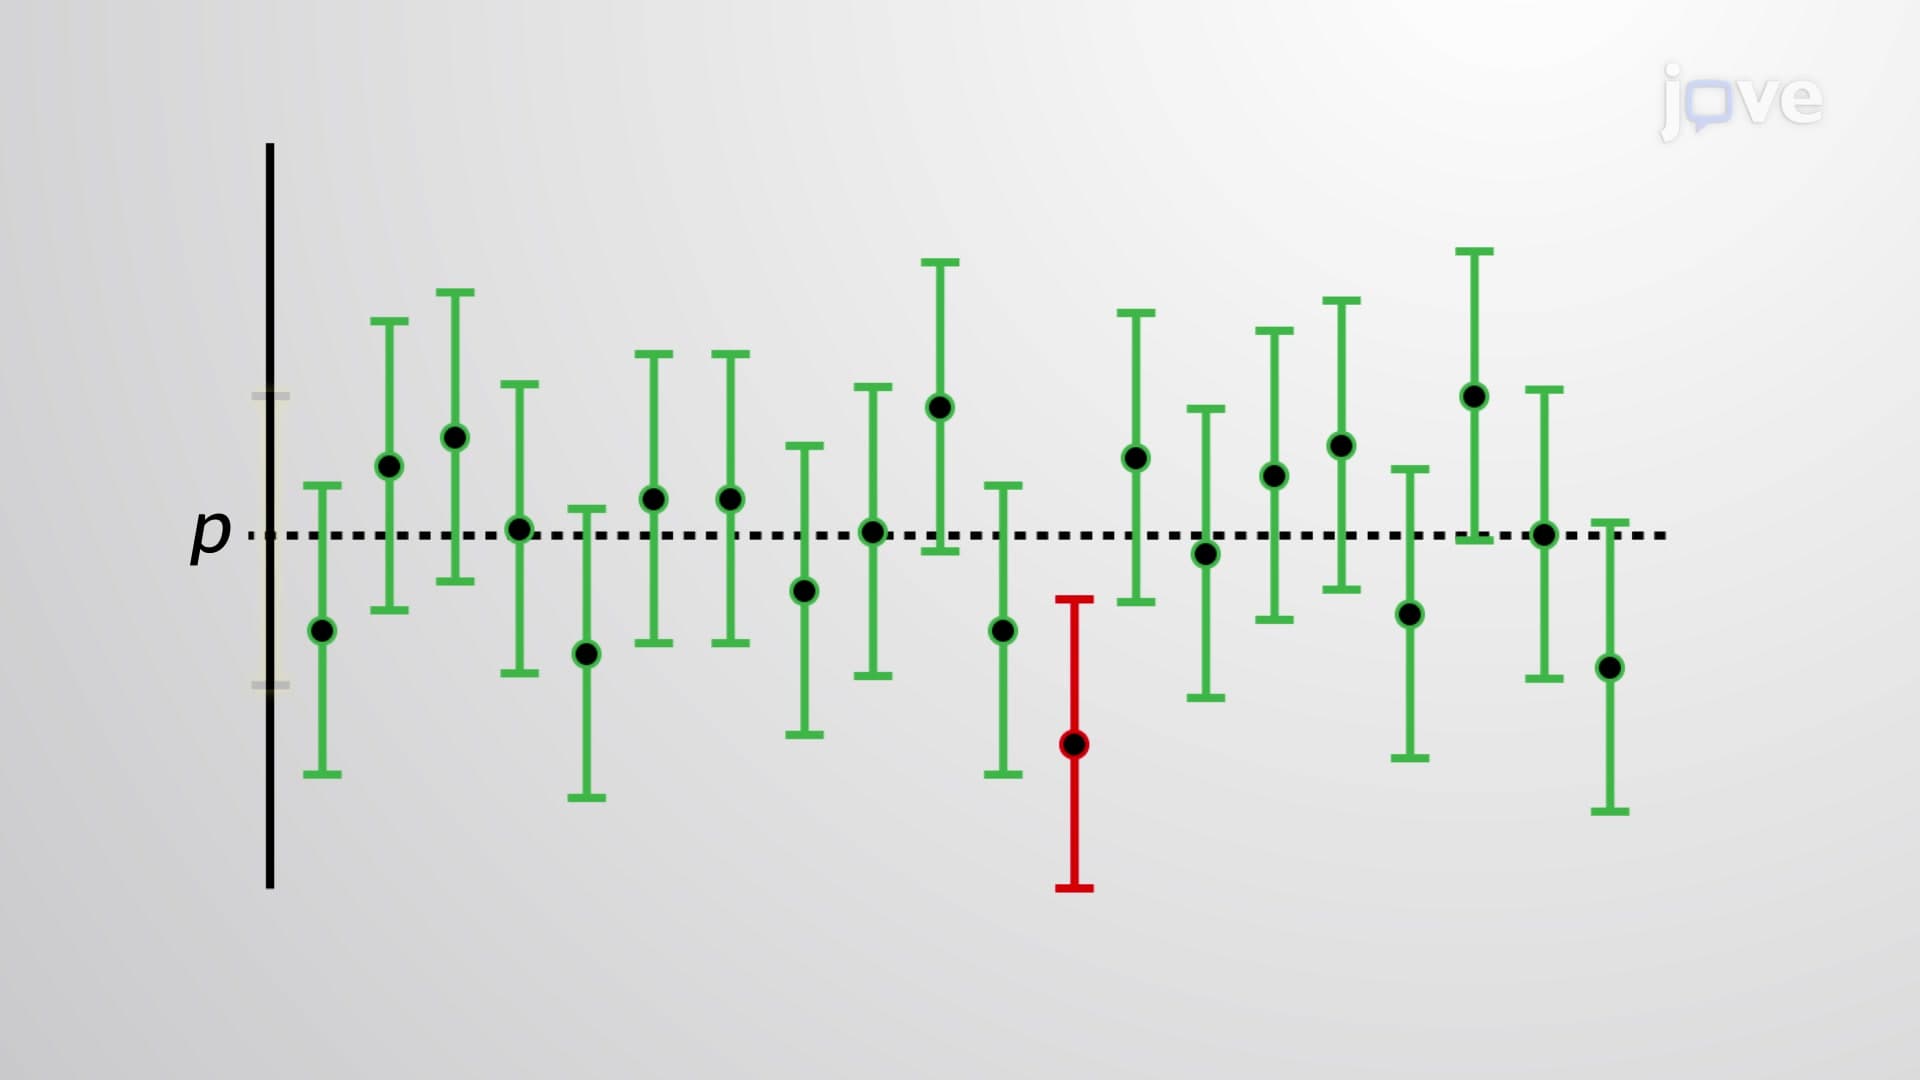
A confidence interval is a better estimate of the population than a point estimate, as it uses a range of values from a sample instead of a single value.
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
5.6K
 01:15
One-Way ANOVA: Equal Sample Sizes
3.2K
One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
3.2K