相关实验视频
Updated: May 27, 2025
09:40

Novel Sequence Discovery by Subtractive Genomics
Published on: January 25, 2019
8.6K
通过随机后续素描来估计序列相似性
Ke Chen1, Vinamratha Pattar2, Mingfu Shao1,3
1Department of Computer Science and Engineering, The Pennsylvania State University, PA 16801.
bioRxiv : the preprint server for biology
|February 20, 2025

概括
SubseqSketch引入了一种新的无对齐方法,用于使用动态随机子序列进行序列相似性估计. 这种方法有效地近似编辑距离,改善生物信息学任务,如遗传学分析.
科学领域:
- 生物信息学是一种生物信息学.
- 计算生物学 计算生物学
- 基因组学就是基因组学.
背景情况:
- 序列相似性估计对于生物信息学任务至关重要,例如功能注释和遗传学分析.
- 无对齐方法通过近似编辑距离,提供高效的大规模序列比较.
- 像k-mers这样的现有方法面临着权衡,而后续方法是计算密集的.
研究的目的:
- 引入SubseqSketch,这是一个用于序列相似性估计的新型无对齐方案.
- 开发一种方法,克服固定长度 k-mers 和计算要求高的后续方法的局限性.
- 为了证明SubseqSketch在各种生物信息学应用中的效率和有效性.
主要方法:
- SubseqSketch将序列映射为整数向量,表示随机子序列的动态长度.
- 参数相似性用于比较这些向量,与编辑相似性有很强的相关性.
- 该方法在对无对齐任务的基准数据集上进行了评估.
主要成果:
- SubseqSketch展示了矢量共弦相似度和原始序列编辑相似度之间的强烈相关性.
- 该方法在最近邻居搜索和家族遗传集群中被证明是高效和有效的.
- 实验结果验证了SubseqSketch在各种无对齐应用中的性能.
结论:
- SubseqSketch为序列相似性估计提供了一种高效有效的无对齐方法.
- 动态次序映射克服了传统的k-mer和固定长度次序方法的局限性.
- 开源实现促进了生物信息学研究的更广泛采用.
相关概念视频
 01:24
Bootstrapping
577
The term "bootstrap" originated in the 19th century as a metaphor for self-improvement or achieving something independently, without external assistance. This concept extends to statistical bootstrapping, a self-contained method for estimating population parameters through resampling, even though it can be computationally intensive. Developed by the American statistician Dr. Bradley Efron in 1979, bootstrapping provides a robust way to perform inference when the original sample size is...
577
 03:21
RNA-seq
9.8K
RNA sequencing, or RNA-Seq, is a high-throughput sequencing technology used to study the transcriptome of a cell. Transcriptomics helps to interpret the functional elements of a genome and identify the molecular constituents of an organism. Additionally, it also helps in understanding the development of an organism and the occurrence of diseases.
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
9.8K
 02:54
Evolutionary Relationships through Genome Comparisons
5.7K
Genome comparison is one of the excellent ways to interpret the evolutionary relationships between organisms. The basic principle of genome comparison is that if two species share a common feature, it is likely encoded by the DNA sequence conserved between both species. The advent of genome sequencing technologies in the late 20th century enabled scientists to understand the concept of conservation of domains between species and helped them to deduce evolutionary relationships across diverse...
5.7K
 01:05
Maxam-Gilbert Sequencing
11.0K
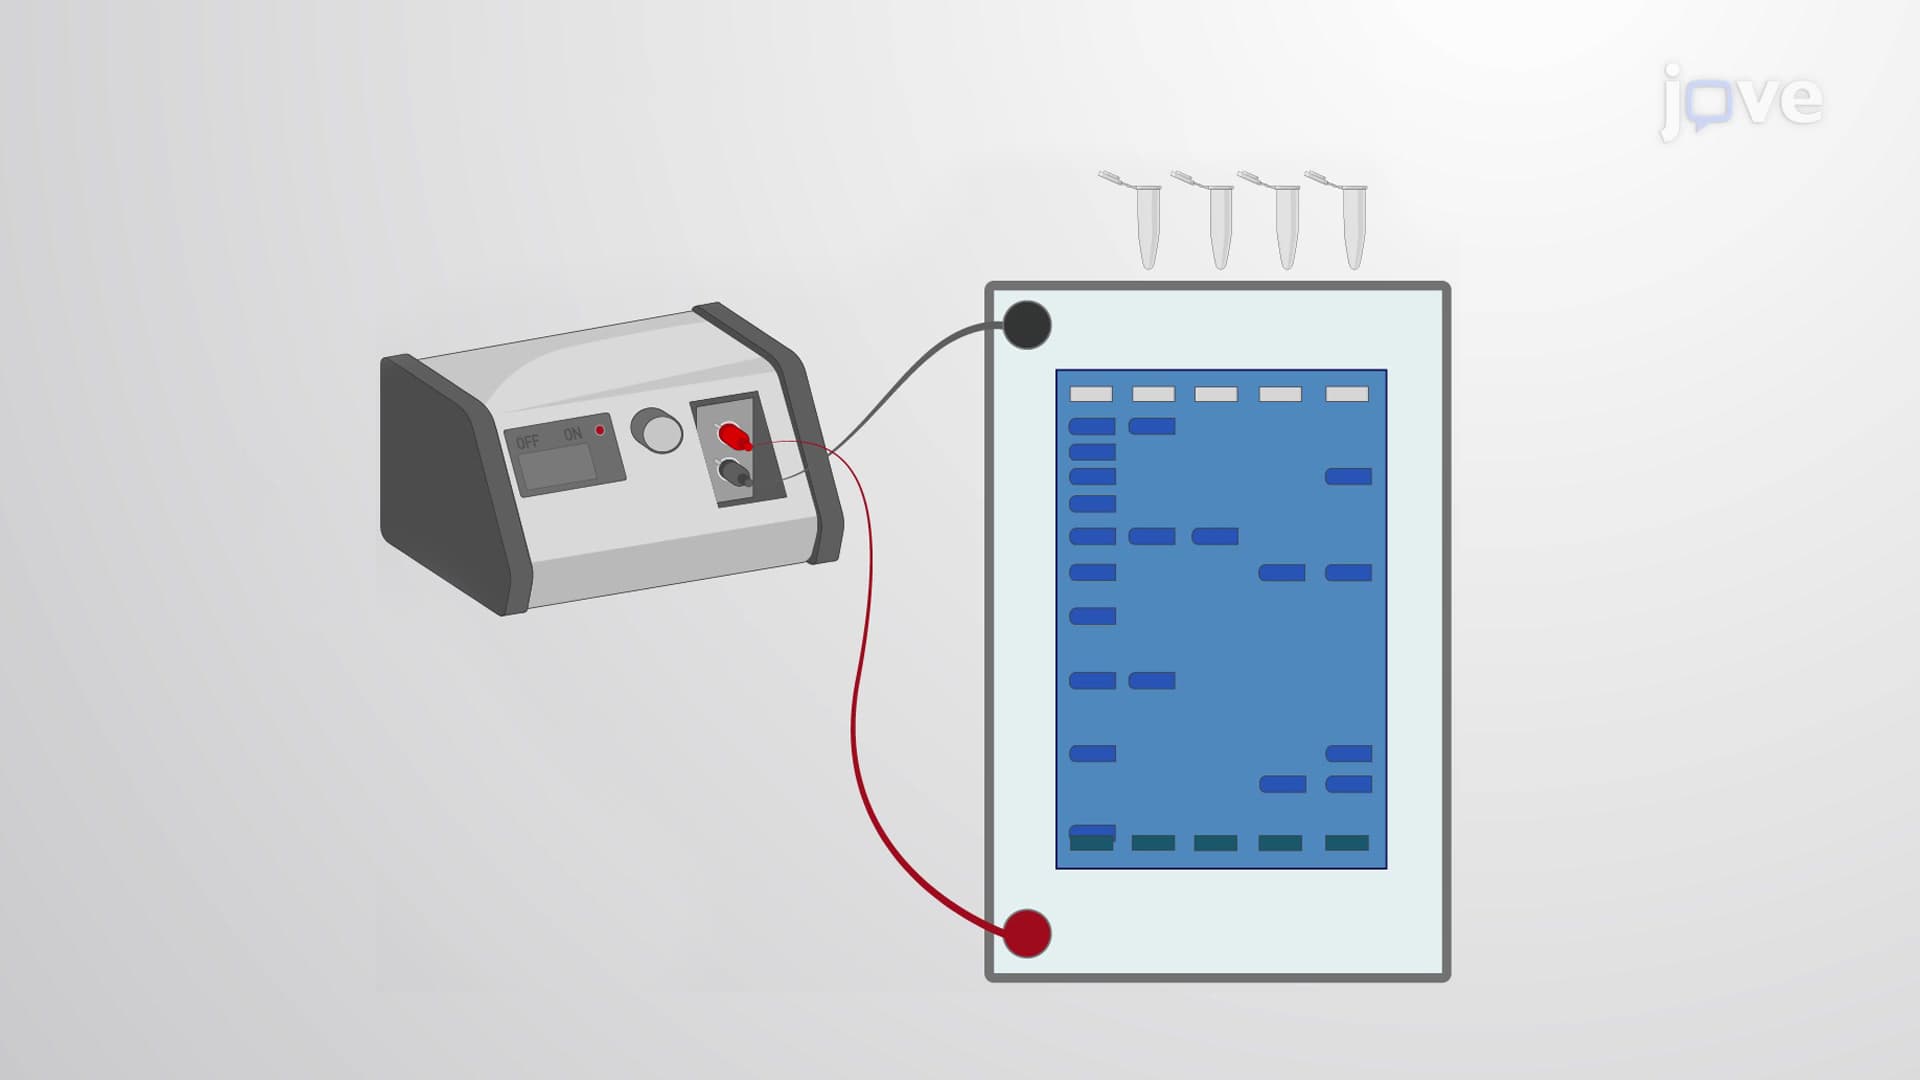
In the same year as the discovery of the Sanger sequencing method, another group of scientists, Allan Maxam and Walter Gilbert, demonstrated their chemical-cleavage method for DNA sequencing. The Maxam-Gilbert method relies on using different chemicals that can cleave the DNA sequence at specific sites, the separation of resulting DNA fragments of variable size using electrophoresis, and deciphering the DNA sequence from the resulting gel bands.
Challenges of the Maxam-Gilbert Method
The...
Challenges of the Maxam-Gilbert Method
The...
11.0K
 01:09
Random Sampling Method
11.0K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. Data are the result of sampling from a population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest. Among the various sampling methods used by...
11.0K
 01:17
Wald-Wolfowitz Runs Test II
172
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
172