

拉丁美洲国家贸易开放的宏观经济决定因素:一个小组数据分析
Rogger Orlando Morán Santamaría1, Yefferson Llonto Caicedo1, Francisco Eduardo Cúneo Fernández1
1La Libertad, Universidad Cesar Vallejo, Trujillo, La Libertad, Peru.
F1000Research
|February 24, 2025

概括
南美国家表现出各种各样的贸易开放决定因素. 虽然GDP和经济复杂性对贸易产生负面影响,但高科技出口和研发支出对贸易产生积极影响,促进经济增长.
科学领域:
- 经济学 经济学 经济学
- 国际贸易 国际贸易 国际贸易
- 经济发展 经济发展
背景情况:
- 贸易开放对经济增长产生积极影响,得到了既有经济理论的支持.
- 在全球范围内观察到出口多元化和经济复杂性的动态,但南美洲具有独特的特点.
- 了解这些特点对于区域经济战略至关重要.
研究的目的:
- 分析拉丁美洲国家贸易开放的宏观经济决定因素.
- 在南美背景下,确定影响贸易开放的关键因素.
- 为旨在加强区域贸易的政策制定提供见解.
主要方法:
- 量化,解释性的研究方法.
- 面板数据方法应用于2000年至2020年的数据.
- 利用了世界银行,哈佛大学和ECLAC的数据库.
主要成果:
- 固定效应面板数据模型显示,GDP,经济复杂性指数和物流绩效指数对贸易开放有负面影响.
- 高科技产品的出口 (创新代理),整体出口,进口,研发支出和区域间贸易对贸易开放有积极的影响.
- 在南美洲 (2000-2020年),有8个国家表现出负面影响,而智利,法属圭亚那和巴西表现出积极影响.
结论:
- 智利,法属圭亚那和巴西的积极贸易开放与更高的经济复杂性和更高的研发投资有关.
- 这些主要经济体将贸易政策集中在产业化增值产品上.
- 调查结果强调了创新和战略贸易政策对南美经济增长的重要性.
关键词:
贸易开放性;影响;面板数据.
相关概念视频
 01:29
Econometric Views (EViews)
101
Econometric Views, often stylized as EViews, is a package that merges statistical analysis with econometric studies. It is designed to provide tools for time series analysis, forecasting, and econometric model simulation. The software originated from MicroTSP software and has evolved significantly since its inception in 1981. The history of EViews is marked by a continuous effort to enhance its computational speed and user interface. It was initially developed for large computing systems but...
101
 01:12
Statistical Methods to Analyze Parametric Data: ANOVA
266
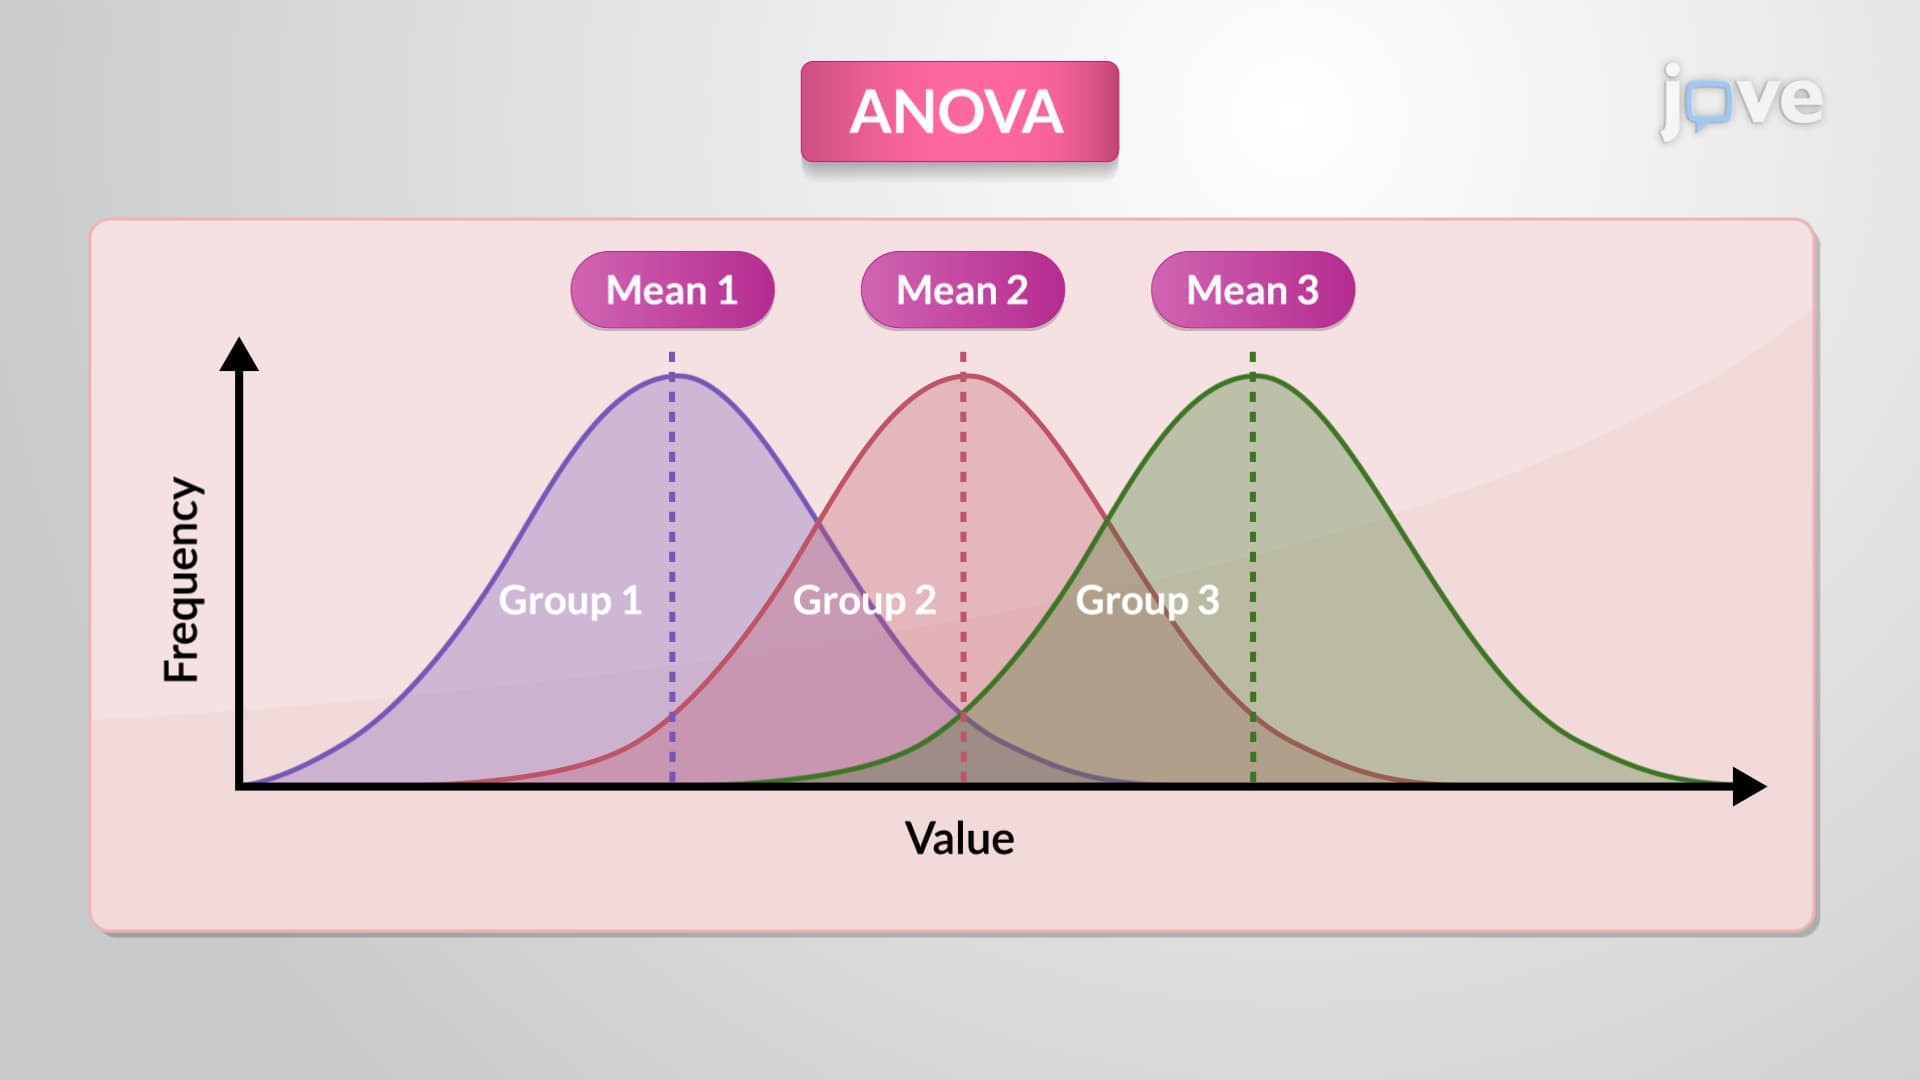
Analysis of Variance, or ANOVA, is a powerful statistical technique used to analyze parametric data, primarily in research and experimental studies. It's designed to compare the means of two or more groups, assisting researchers in identifying any significant differences between these group means. There are two main types of ANOVA based on the complexity of the analysis: one-way and two-way.
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
266
 01:11
Variability: Analysis
125
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
125
 01:50
Cross-Sectional Research
11.1K
In cross-sectional research, a researcher compares multiple segments of the population at the same time. If they were interested in people's dietary habits, the researcher might directly compare different groups of people by age. Instead of following a group of people for 20 years to see how their dietary habits changed from decade to decade, the researcher would study a group of 20-year-old individuals and compare them to a group of 30-year-old individuals and a group of 40-year-old...
11.1K
 01:25
Statistical Methods for Analyzing Epidemiological Data
284
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
284
 01:21
Friedman Two-way Analysis of Variance by Ranks
134
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
134