

通过特征提取来学习最佳歧视性SVM

概括
最佳分辨支持矢量机 (ODSVM) 同时学习最好的子空间和支持矢量机 (SVM) 分类器. 这种新的方法提高了模式识别和分类性能,并保证了全球趋同.
科学领域:
- 模式识别 模式识别
- 机器学习 机器学习
- 数据科学数据科学数据科学
背景情况:
- 亚空间学习和支持向量机 (SVM) 对于特征提取和分类至关重要.
- 为SVM优化子空间在计算,融合和优化方面带来了挑战.
- 现有的方法难以同时实现最佳的子空间和分类器性能.
研究的目的:
- 开发一种新的方法,即最佳分辨支持向量机 (ODSVM),集成子空间学习和SVM分类.
- 为了应对优化,计算和算法在模式识别中的融合的挑战.
- 通过同时学习最具歧视性的子空间和最佳的SVM来实现更高的分类性能.
主要方法:
- 开发了最佳歧视支持向量机 (ODSVM) 框架.
- 集成的歧视性子空间学习与支持向量分类.
- 为二进制和多类ODSVM设计了一个高效的优化框架.
- 提出了一个快速序列最小化优化 (SMO) 算法,并对多类ODSVM进行修剪.
主要成果:
- ODSVM成功地将子空间学习和SVM分类集成到一个统一的框架中.
- 同时优化子空间和SVM可以提高分类性能.
- 在13个数据集上的数值实验表明,ODSVM显著优于现有方法.
- 拟议的SMO算法加速了多类ODSVM中的计算.
结论:
- ODSVM为模式识别和分类提供了一种新且有效的方法.
- 该方法提供了全球趋同的强有力的理论保证,确保稳定性和优越性.
- 在多个数据集中,ODSVM表现出了比现有技术的统计学上显著的改进.
相关概念视频
 00:56
Extraction: Advanced Methods
398
Metal ions can be separated from one another by complexation with organic ligands–the chelating agent– to form uncharged chelates. Here, the chelating agent must contain hydrophobic groups and behave as a weak acid, losing a proton to bind with the metal. Since most organic ligands used in this process are insoluble or undergo oxidation in the aqueous phase, the chelating agent is initially added to the organic phase and extracted into the aqueous phase. The metal-ligand complex is...
398
 01:14
Extraction: Partition and Distribution Coefficients
1.7K
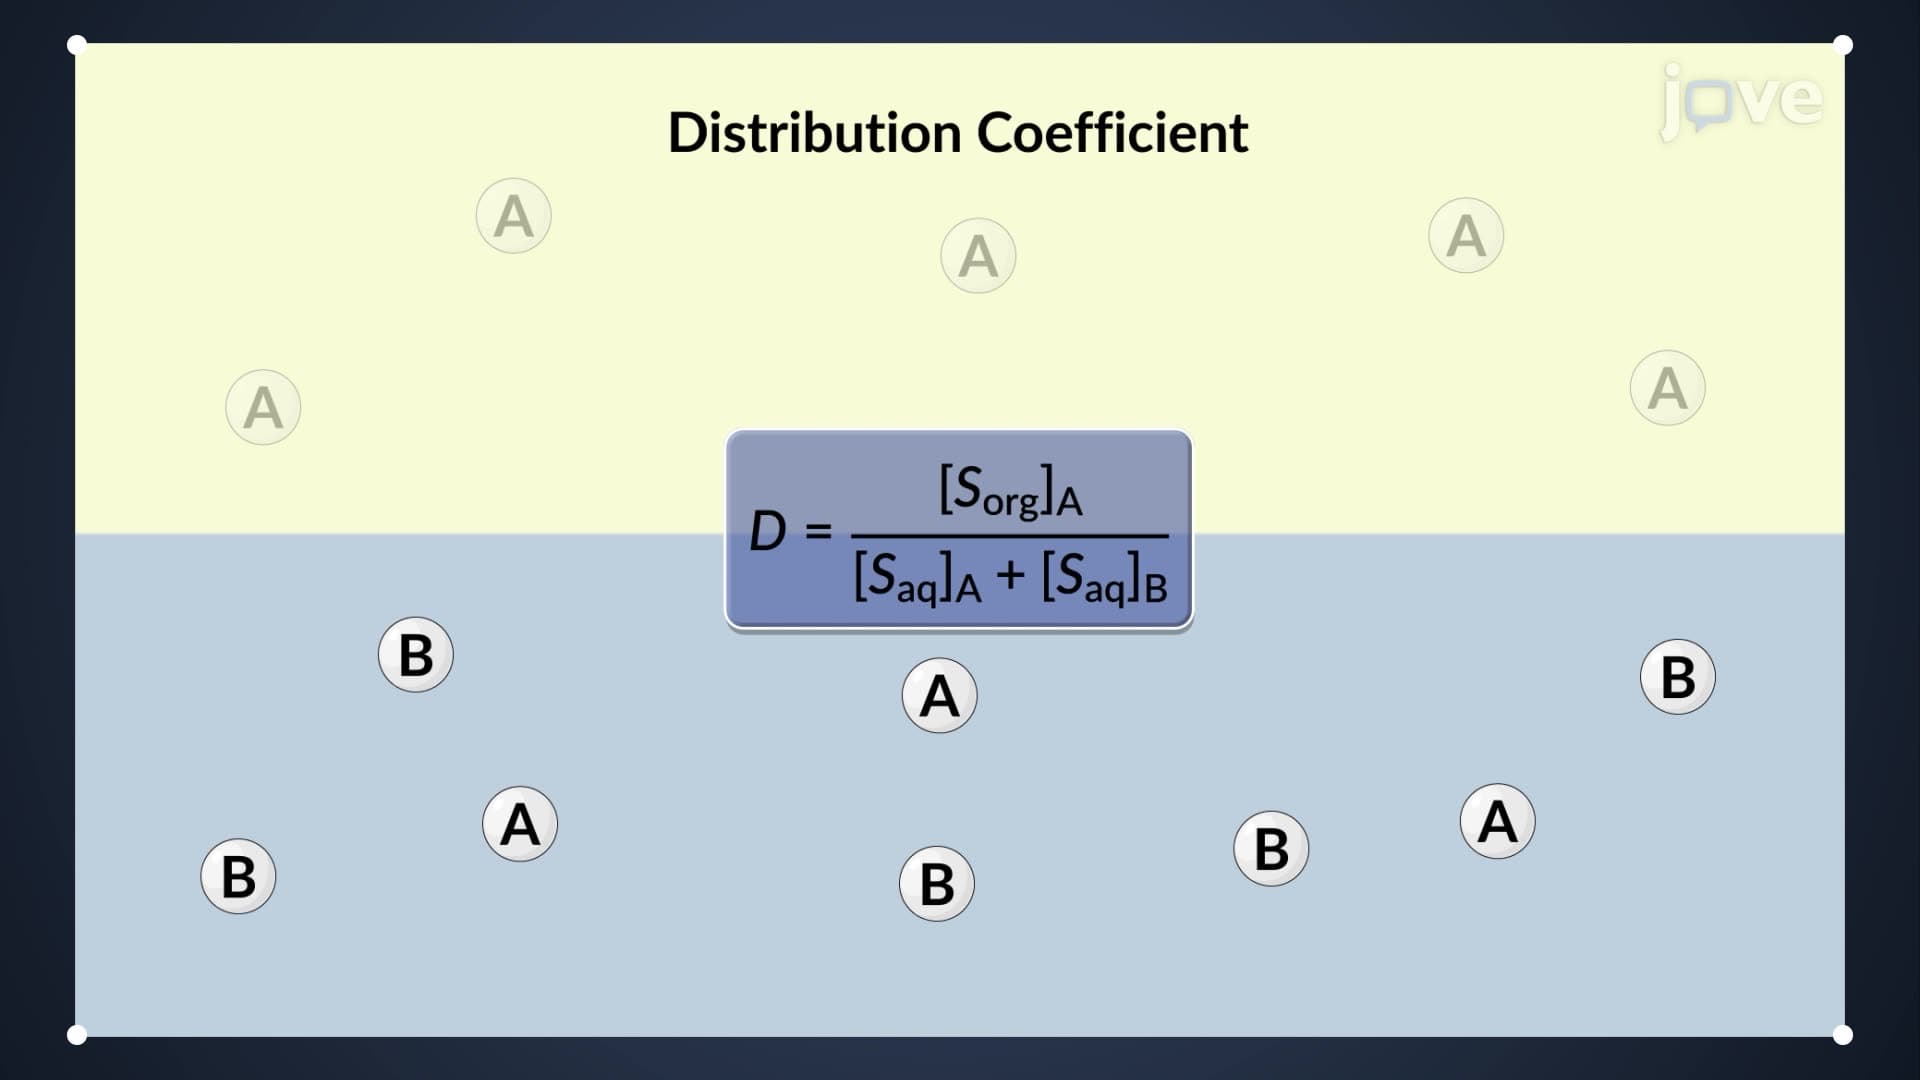
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
1.7K
 01:30
Classification of Signals
374
In signal processing, signals are classified based on various characteristics: continuous-time versus discrete-time, periodic versus aperiodic, analog versus digital, and causal versus noncausal. Each category highlights distinct properties crucial for understanding and manipulating signals.
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
374
 01:22
Force Classification
1.1K
Forces play a crucial role in the study of physics and engineering. They are essential in describing the motion, behavior, and equilibrium of objects in the physical world. Forces can be classified based on their origin, type, and direction of action.
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
1.1K
 01:13
Sensitivity, Specificity, and Predicted Value
158
In healthcare diagnostics, laboratory tests play a crucial role in identifying and diagnosing a wide range of medical conditions. However, interpreting test results is not always straightforward. An abnormal test result does not always confirm the presence of a disease, just as a normal result does not guarantee its absence. To assess the reliability of these diagnostic tools, healthcare practitioners rely on two key statistical indicators: sensitivity and specificity.
Sensitivity is the...
Sensitivity is the...
158
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K