基于数据分类的双重加权强大的主要组件分析


概括
本研究介绍了双重权重强大的主要组件分析 (DRPCA),这是一种用于减少维度的新方法,有效地处理异常值. 通过对正常,阳性和硬样本进行不同的区分和权重,DRPCA提高了准确性.
科学领域:
- 机器学习 机器学习
- 数据科学数据科学数据科学
- 统计 统计 统计 统计
背景情况:
- 主要组件分析 (PCA) 对异常值很敏感,因为它依赖于二次L2标准.
- 现有的强大的PCA方法面临着诸如优化困难和缺乏旋转不变等挑战.
- 目前的方法在正常样本和异常样本之间进行了不充分的区分,并且未能利用正常样本类型的独特贡献.
研究的目的:
- 提出一种新的强大的维度减小方法,双重权重强大的主要组件分析 (DRPCA).
- 通过有效处理异常值和区分正常样本贡献来提高稳定性和准确性.
- 为DRPCA开发一个有效的代算法,并分析其合性质.
主要方法:
- DRPCA使用标记向量来区分和下加权异常值.
- 正常样本进一步细分为正面样本和硬样本,分配自我约束的权重来优先考虑正面样本.
- 为了更准确的数据中心,采用了最佳平均值,加上了一种代算法来进行优化.
主要成果:
- 与现有方法相比,DRPCA在缩小维度方面表现优越.
- 该方法在异常检测任务中显示出显著的优势.
- 在大型现实世界和RGB数据集上的实验结果验证了DRPCA的有效性.
结论:
- 通过有效地管理异常值和样本贡献,DRPCA提供了一种强大而准确的缩小维度的方法.
- 拟议的方法提供了一个更精确的投影矩阵,通过对样本类型分配差异重量.
- 对于缩小维度和异常检测应用来说,DRPCA是一个重大进步.

相关概念视频
 01:14
Extraction: Partition and Distribution Coefficients
1.7K
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
1.7K
 01:08
Vector Algebra: Method of Components
13.6K
It is cumbersome to find the magnitudes of vectors using the parallelogram rule or using the graphical method to perform mathematical operations like addition, subtraction, and multiplication. There are two ways to circumvent this algebraic complexity. One way is to draw the vectors to scale, as in navigation, and read approximate vector lengths and angles (directions) from the graphs. The other way is to use the method of components.
In many applications, the magnitudes and directions of...
In many applications, the magnitudes and directions of...
13.6K
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K
 01:14
Principal Moments of Area
972
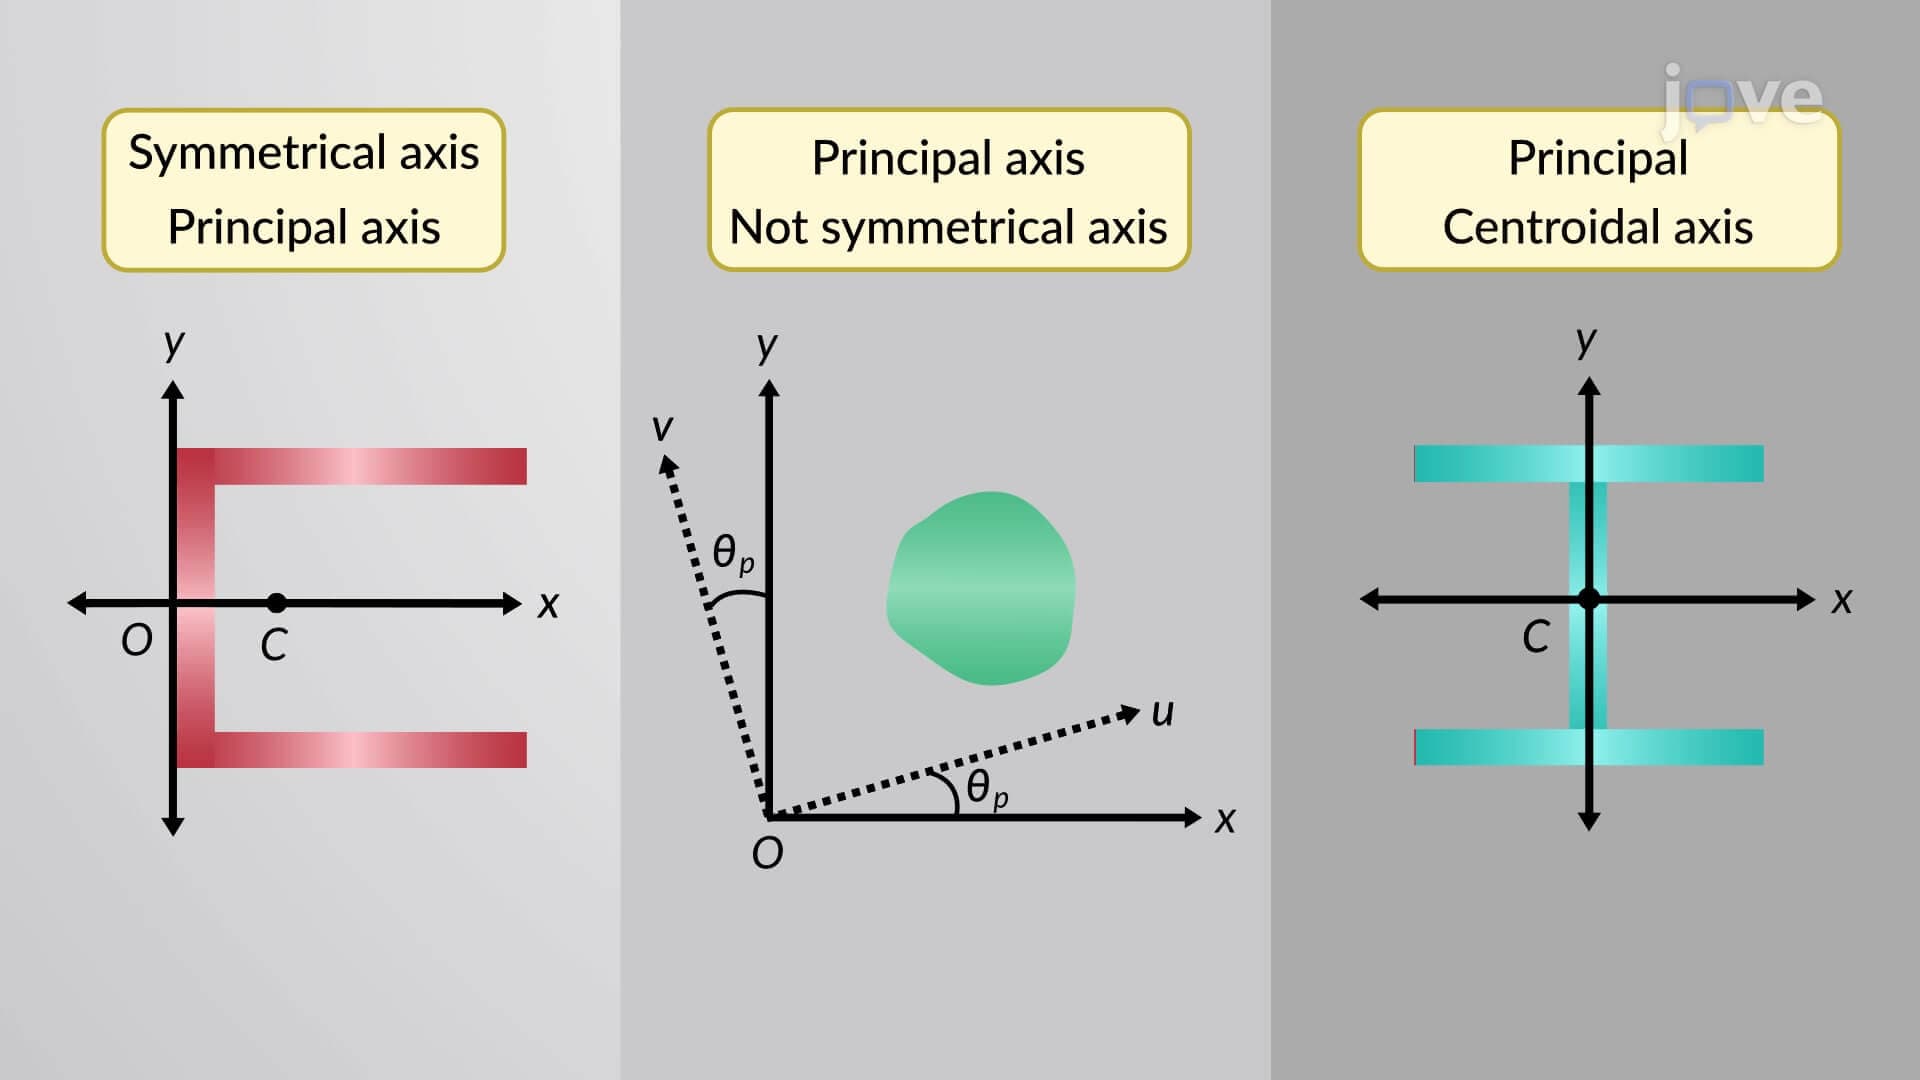
In mechanics, the product of inertia and moments of inertia of area help to calculate the stability and performance of various structures and components. The coordinate transformation relations are used to calculate the moments and products of inertia for an area about the inclined axes. Further, the moments and products of inertia with respect to the principal axes can be determined using the moments and products of inertia about the inclined axes.
The principal moment of inertia axes are the...
The principal moment of inertia axes are the...
972
 01:21
Friedman Two-way Analysis of Variance by Ranks
130
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
130
 00:57
Weighted Mean
4.9K
While taking the arithmetic, geometric, or harmonic mean of a sample data set, equal importance is assigned to all the data points. However, all the values may not always be equally important in some data sets. An intrinsic bias might make it more important to give more weightage to specific values over others.
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
4.9K