
PDPilot:通过排名,过和聚类来探索部分依赖地图
IEEE transactions on visualization and computer graphics
|March 3, 2025

概括
本研究引入了对部分依赖图 (PDP) 和个人有条件期望 (ICE) 图的排名和过的新方法. 这些技术有助于机器学习从业者有效地探索复杂数据集中的模型行为.
科学领域:
- 机器学习 机器学习
- 数据可视化 数据可视化
- 科学计算科学计算
背景情况:
- 部分依赖图 (PDP) 和个人有条件预期 (ICE) 图对于对表格数据的机器学习 (ML) 模型的解释至关重要.
- 分析这些图片变得具有挑战性,具有大量的特征,阻碍了高效的模型探索.
研究的目的:
- 开发和评估新技术来对PDP和ICE图表进行排名和过.
- 提高ML从业人员在探索模型行为和识别显著特征影响方面的效率.
- 将这些新技术整合到一个用户友好的视觉分析工具中.
主要方法:
- 开发用于排名和过PDP和ICE图表的新型算法.
- 适应和整合现有的线路集群策略用于ICE地块.
- 这些技术在PDPilot中的实施,这是Jupyter笔记本电脑的视觉分析工具.
- 经验研究涉及7名ML从业人员,以评估开发的技术的可用性.
主要成果:
- 该研究提出了新的,有效的技术来优先考虑和选择相关的PDP和ICE地块.
- 集成到PDPilot有助于有效地探索和分析ML模型的行为.
- 用户研究证明了开发的排名,过和集群方法的实际实用性.
结论:
- 开发的技术显著提高了使用PDP和ICE图表分析ML模型的效率.
- 随着其集成功能,PDPilot为ML从业者提供了一个有价值的工具.
- 这些进步有助于更易于解释和理解的机器学习模型.
更多相关视频
 10:44
Inherent Dynamics Visualizer, an Interactive Application for Evaluating and Visualizing Outputs from a Gene Regulatory Network Inference Pipeline
Published on: December 7, 2021
2.1K
 10:10
Three Differential Expression Analysis Methods for RNA Sequencing: limma, EdgeR, DESeq2
Published on: September 18, 2021
36.7K
相关概念视频
 01:21
Friedman Two-way Analysis of Variance by Ranks
130
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
130
 01:15
Scatter Plot
6.7K
The most common and easiest way to display the relationship between two variables, x and y, is a scatter plot. A scatter plot shows the direction of a relationship between the variables. A clear direction happens when there is either:
6.7K
 01:02
Ranks
219
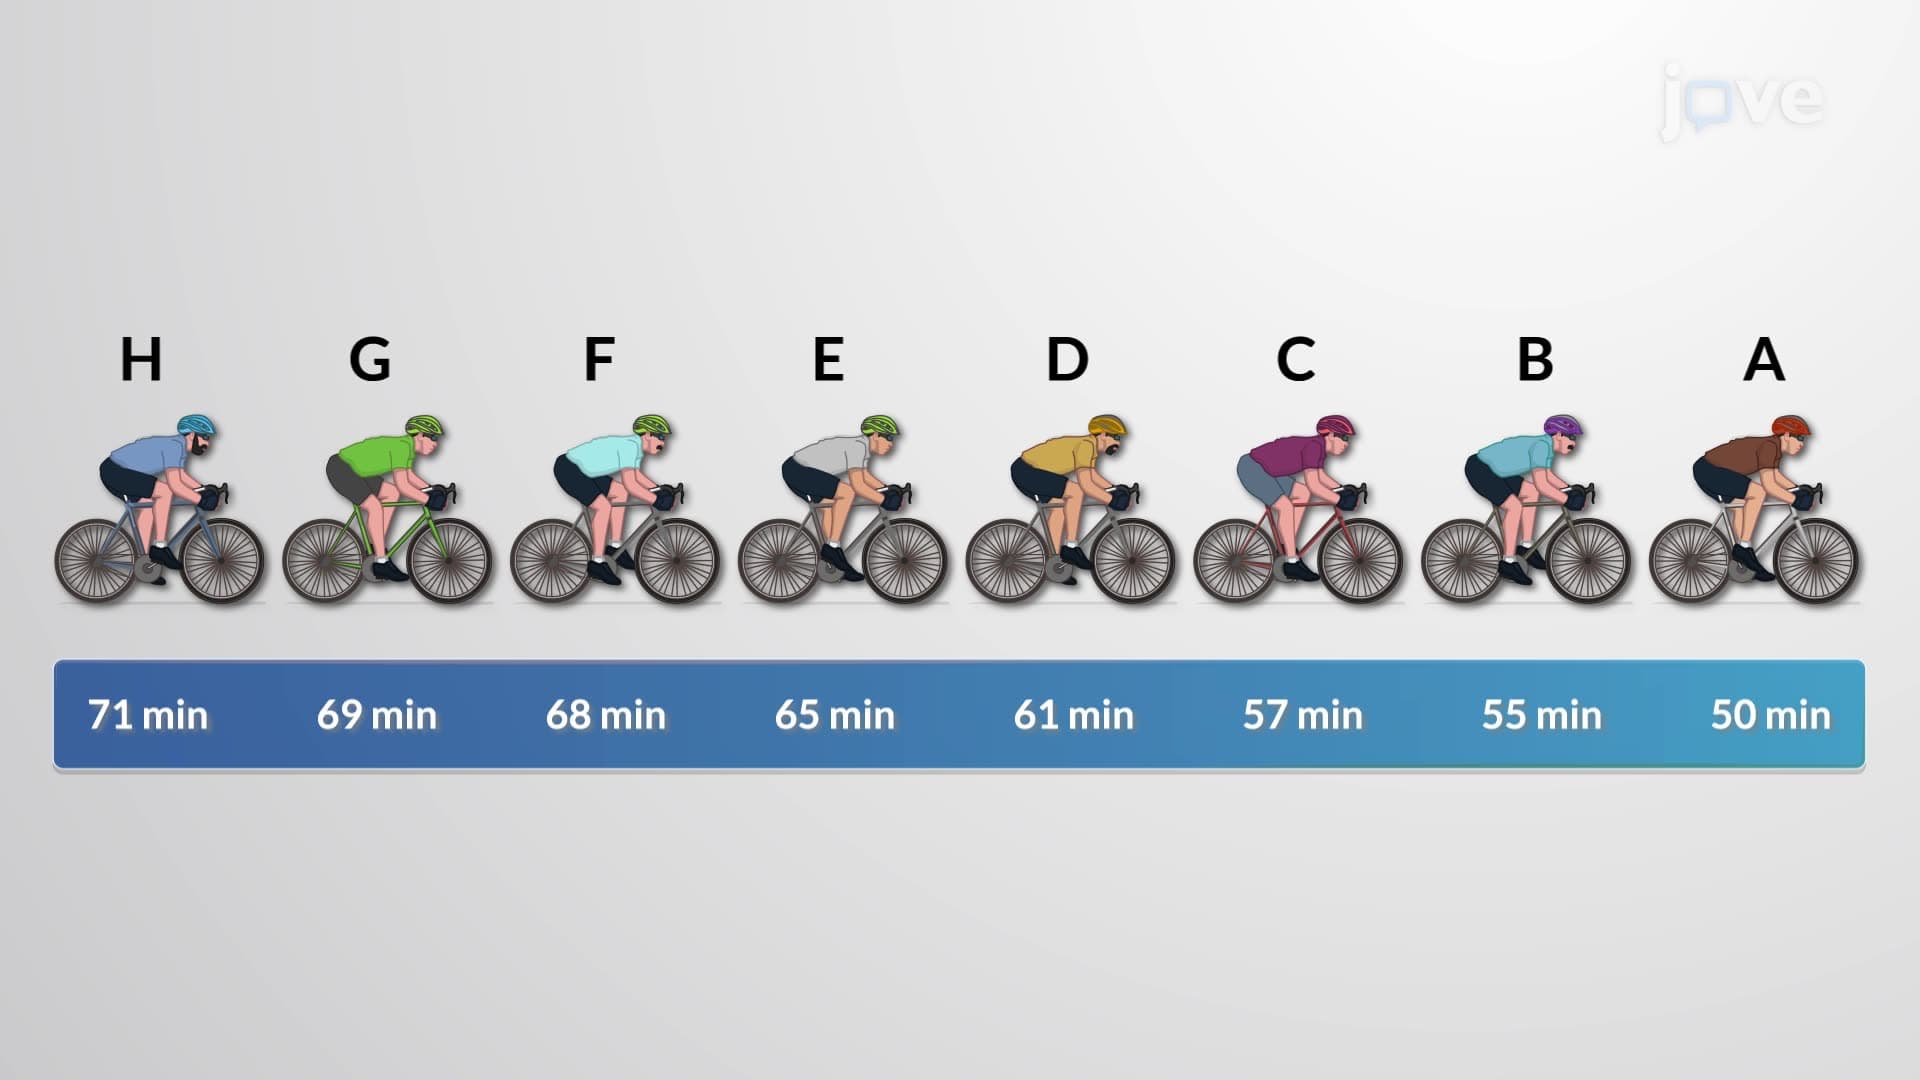
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
219
 01:19
Survival Tree
50
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
50
 01:07
Residual Plots
4.5K
A residual plot is a statistical representation of data used to analyze correlation and regression results. It helps verify the requirements for drawing specific conclusions about correlation and regression. To obtain the residual plot, first, the residual for each data value is calculated, which is simply the vertical distance between the observed and the predicted value obtained from the regression equation.
When the residual values are plotted against the variable x, it is called a residual...
When the residual values are plotted against the variable x, it is called a residual...
4.5K
 01:12
Boxplot
7.9K
Box plots (also called box-and-whisker plots or box-whisker plots) give an excellent graphical image of the concentration of the data. They also show how far the extreme values are from most data. A box plot is constructed from five values: the minimum value, the first quartile, the median, the third quartile, and the maximum value. We use these values to compare how close other data values are to them. To construct a box plot, use a horizontal or vertical number line and a rectangular box. The...
7.9K