DNA-CBIR:DNA翻译启发了基于Codon模式的深度图像特征提取,用于基于内容的图像检索
IEEE transactions on nanobioscience
|March 3, 2025

概括
DNA 数据存储能够长期保存高密度的信息. 本研究介绍了一种基于DNA的基于内容的图像检索 (CBIR) 方法,用于高效地从DNA特征向量搜索和恢复图像.
科学领域:
- 生物技术是生物技术.
- 数据存储数据存储数据存储
- 计算机科学 计算机科学
背景情况:
- 对于长期的数据存档,DNA提供了一个稳定,高密度的介质.
- 目前的DNA数据存储缺乏有效的图像检索机制.
研究的目的:
- 为基于DNA的数据开发一种新的基于内容的图像检索 (CBIR) 技术.
- 为了能够有效地搜索和检索存储在DNA中的类似图像.
主要方法:
- 一个新的编码方案将图像数据转换为DNA平面,使用最重要的比特和核酸约束.
- 通过编码子序列来解释DNA平面,以基于实例的检索.
- 深度学习架构 (ResNet-50,VGG-16/19,Inception V3) 已经适应了基于分类的检索.
主要成果:
- 拟议的CBIR技术成功地从DNA特征向量中获取类似图像.
- 适应深度学习模型有助于基于分类的检索任务.
- 该系统在各种数据集 (珊瑚,医疗,多标签) 中显示了显著的性能改进.
结论:
- 开发的基于DNA的CBIR方法提高了从DNA数据存储中获取图像的效率.
- 这种方法在管理和访问存储在DNA中的多媒体数据方面取得了重大进展.
- 该技术对DNA数据存档和检索系统的未来应用具有前景.
相关概念视频
 02:28
Leaky Scanning
5.1K
During most eukaryotic translation processes, the small 40S ribosome subunit scans an mRNA from its 5' end until it encounters the first start AUG codon. The large 60S ribosomal subunit then joins the smaller one to initiate protein synthesis. The location of the translation initiation is largely determined by the nucleotides near the start codon as there may be multiple translation initiation sites present on the mRNA. Marilyn Kozak discovered that the sequence RCCAUGG (where R...
5.1K
 02:24
Ribosome Profiling
3.4K
Ribosome profiling or ribo-sequencing is a deep sequencing technique that produces a snapshot of active translation in a cell. It selectively sequences the mRNAs protected by ribosomes to get an insight into a cell’s translation landscape at any given point in time.
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique...
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique...
3.4K
 03:21
RNA-seq
9.8K
RNA sequencing, or RNA-Seq, is a high-throughput sequencing technology used to study the transcriptome of a cell. Transcriptomics helps to interpret the functional elements of a genome and identify the molecular constituents of an organism. Additionally, it also helps in understanding the development of an organism and the occurrence of diseases.
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
9.8K
 02:33
Initiation of Translation
30.3K
Initiating translation is complex because it involves multiple molecules. Initiator tRNA, ribosomal subunits, and eukaryotic initiation factors (eIFs) are all required to assemble on the initiation codon of mRNA. This process consists of several steps that are mediated by different eIFs.
First, the initiator tRNA must be selected from the pool of elongator tRNAs by eukaryotic initiation factor 2 (eIF2). The initiator tRNA (Met-tRNAi) has conserved sequence elements including modified bases at...
First, the initiator tRNA must be selected from the pool of elongator tRNAs by eukaryotic initiation factor 2 (eIF2). The initiator tRNA (Met-tRNAi) has conserved sequence elements including modified bases at...
30.3K
 02:11
Proteins: From Genes to Degradation
11.9K
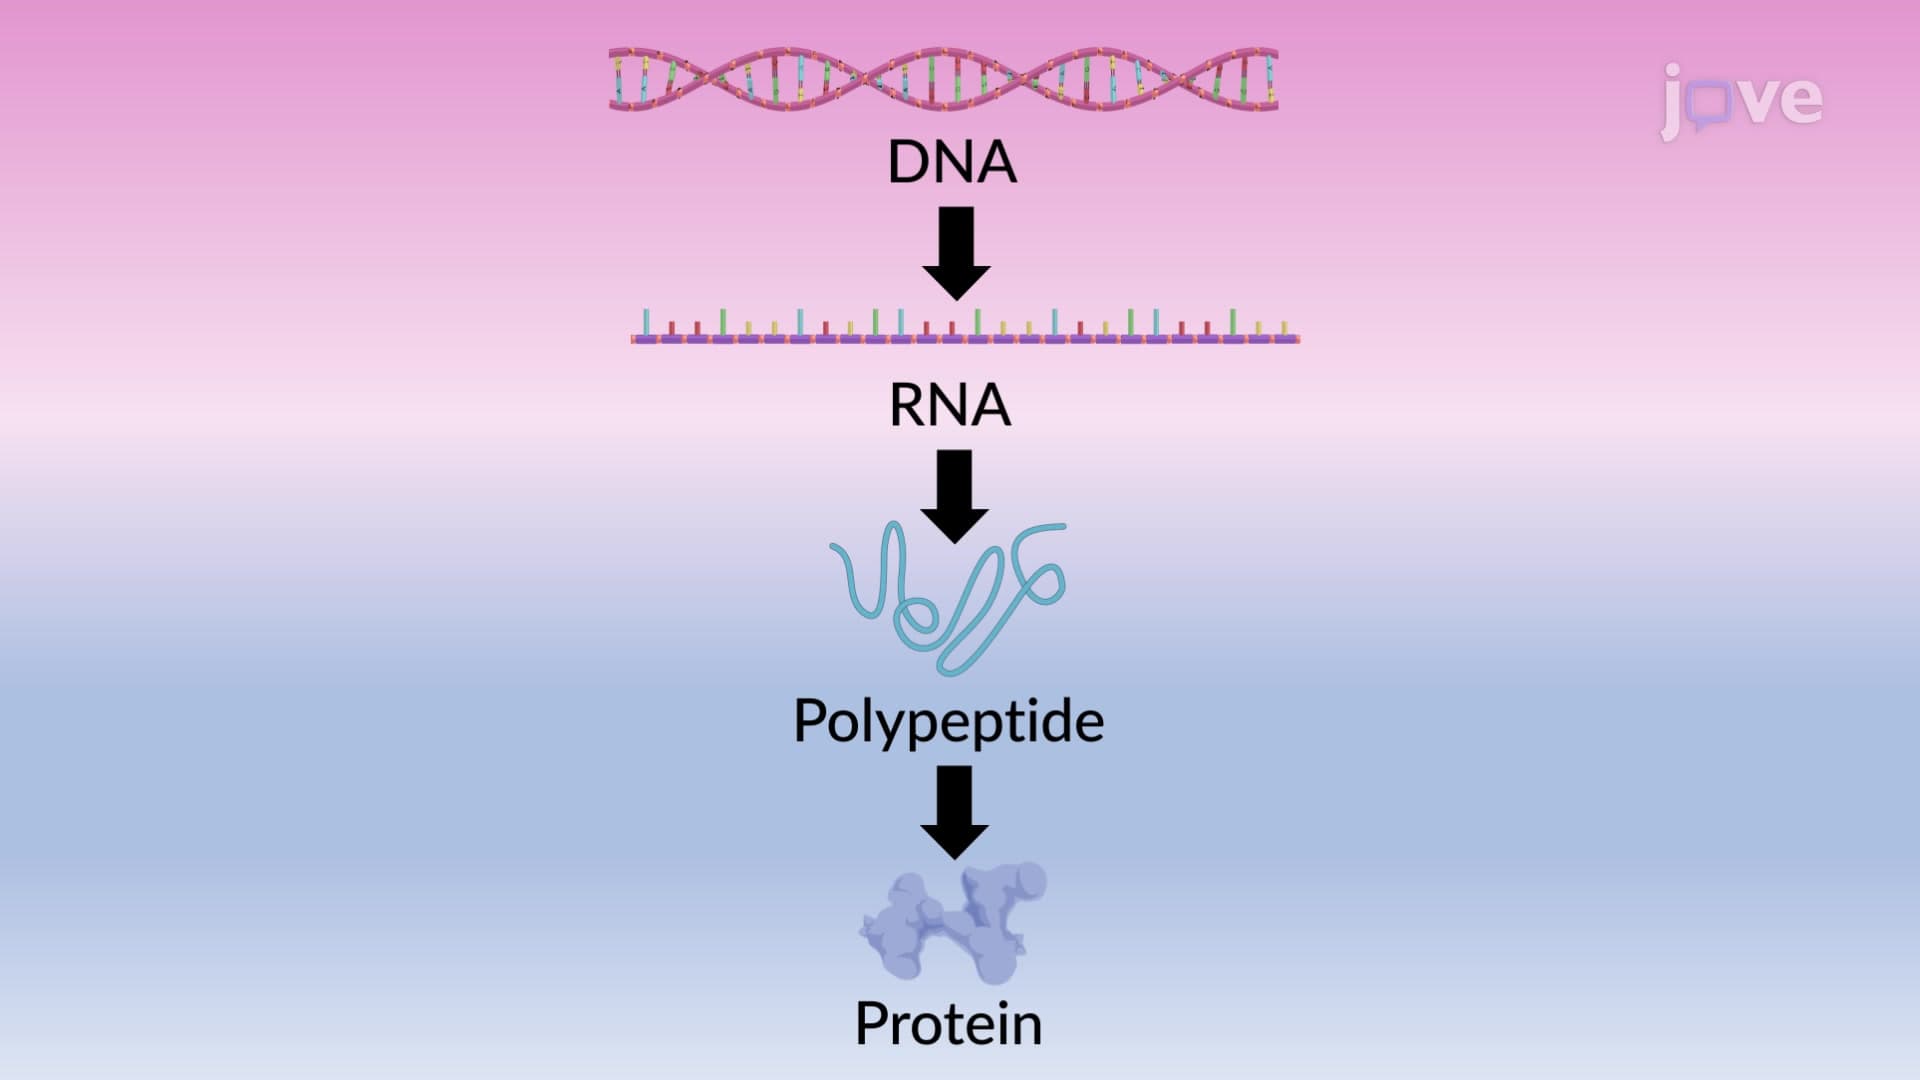
Within a biological system, the DNA encodes the RNA, and the nucleotide sequence in the RNA further defines the amino acid sequence in the protein. This is referred to as “The Central Dogma of Molecular Biology” - a term coined by Francis Crick. Central dogma is a firm principle in biology that defines the flow of genetic information within any life form. The two fundamental steps in central dogma are - transcription and translation.
Transcription is the synthesis of RNA...
Transcription is the synthesis of RNA...
11.9K
 02:07
Improving Translational Accuracy
8.5K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
8.5K