异质相关性意识规范化用于顺序信心校准
相关实验视频
Updated: May 24, 2025

05:37
An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.0K

概括
深度序列识别模型存在过度自信的问题. 一种新的异质相关性意识序列规范化 (HCSR) 方法通过在训练过程中结合相关序列来有效校准这些模型.
科学领域:
- 人工智能的人工智能
- 机器学习 机器学习
- 深度学习 (Deep Learning) 是一种深度学习.
背景情况:
- 深度序列识别模型表现出过度的信心,导致不可靠的预测.
- 现有的校准方法主要解决分类任务,使序列识别模型未得到解决.
研究的目的:
- 调查过度信任序列识别模型的原因.
- 开发一种用于校准序列识别模型的新方法.
主要方法:
- 确定一次性编码是模型过度自信的一个关键因素.
- 提出了一种异构的相关性意识序列规范化 (HCSR) 方法.
- 引入了相关序列挖掘 (CSM) 模型和自适应校准模块.
主要成果:
- 该HCSR方法有效地减少了对序列识别模型过度信任.
- 拟议的方法通过解决感知和语义背景过度信心来实现细粒度校准.
- 实验结果显示,与现有方法相比,性能显著改善.
结论:
- 该HCSR方法为校准过度自信的序列识别模型提供了一个强大的解决方案.
- 这项工作推进了基于序列的任务的模型校准领域.
相关概念视频
 01:10
Calibration Curves: Correlation Coefficient
1.5K
In a linear calibration curve, there is a value called the calibration coefficient, denoted by 'r,' which measures the strength and the direction of association between two variables. The correlation coefficient value ranges from −1 to +1. A value of +1 indicates a perfect positive linear correlation, −1 denotes a perfect negative correlation, and 0 implies no correlation between the two variables. A positive correlation value establishes that as one variable increases, the...
1.5K
 01:20
Calibration Curves: Linear Least Squares
1.2K
A calibration curve is a plot of the instrument's response against a series of known concentrations of a substance. This curve is used to set the instrument response levels, using the substance and its concentrations as standards. Alternatively, or additionally, an equation is fitted to the calibration curve plot and subsequently used to calculate the unknown concentrations of other samples reliably.
For data that follow a straight line, the standard method for fitting is the linear...
For data that follow a straight line, the standard method for fitting is the linear...
1.2K
 01:24
Confidence Coefficient
7.5K
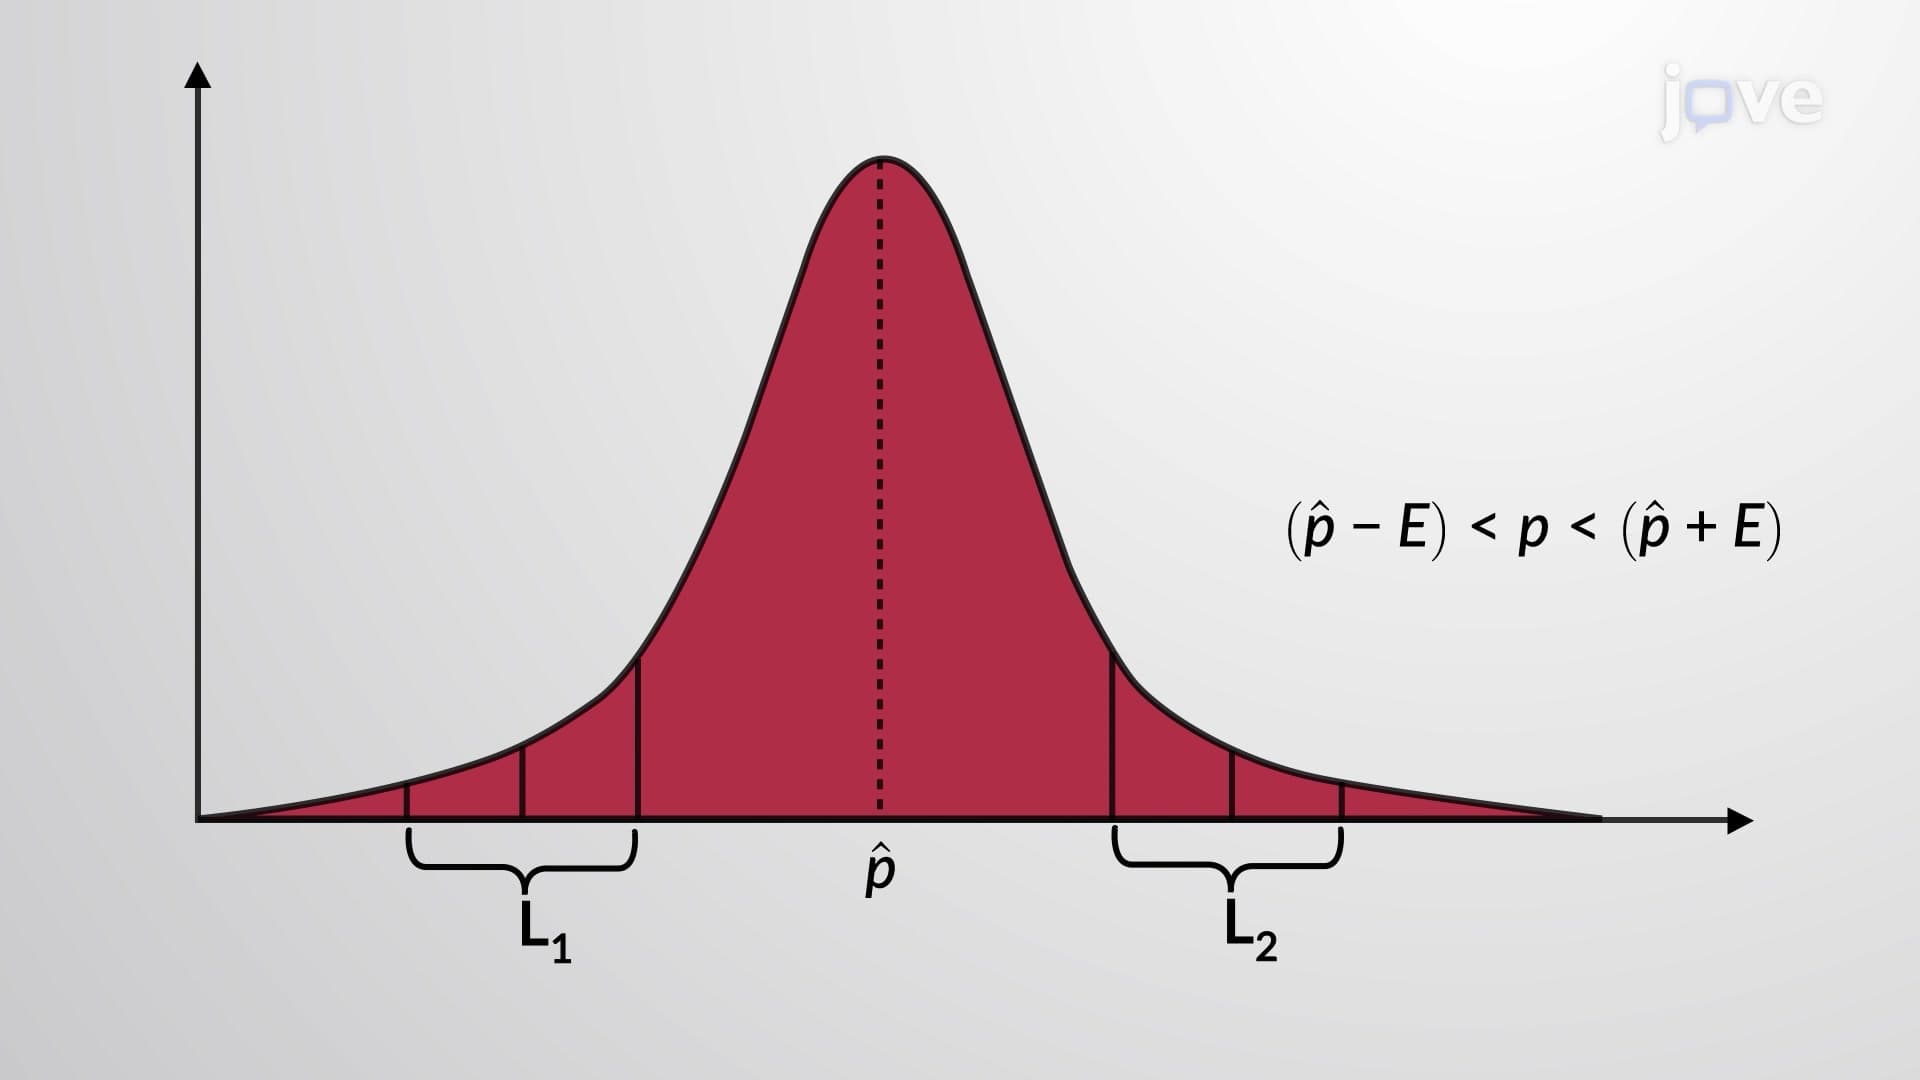
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.5K
 01:21
Confidence Intervals
6.1K
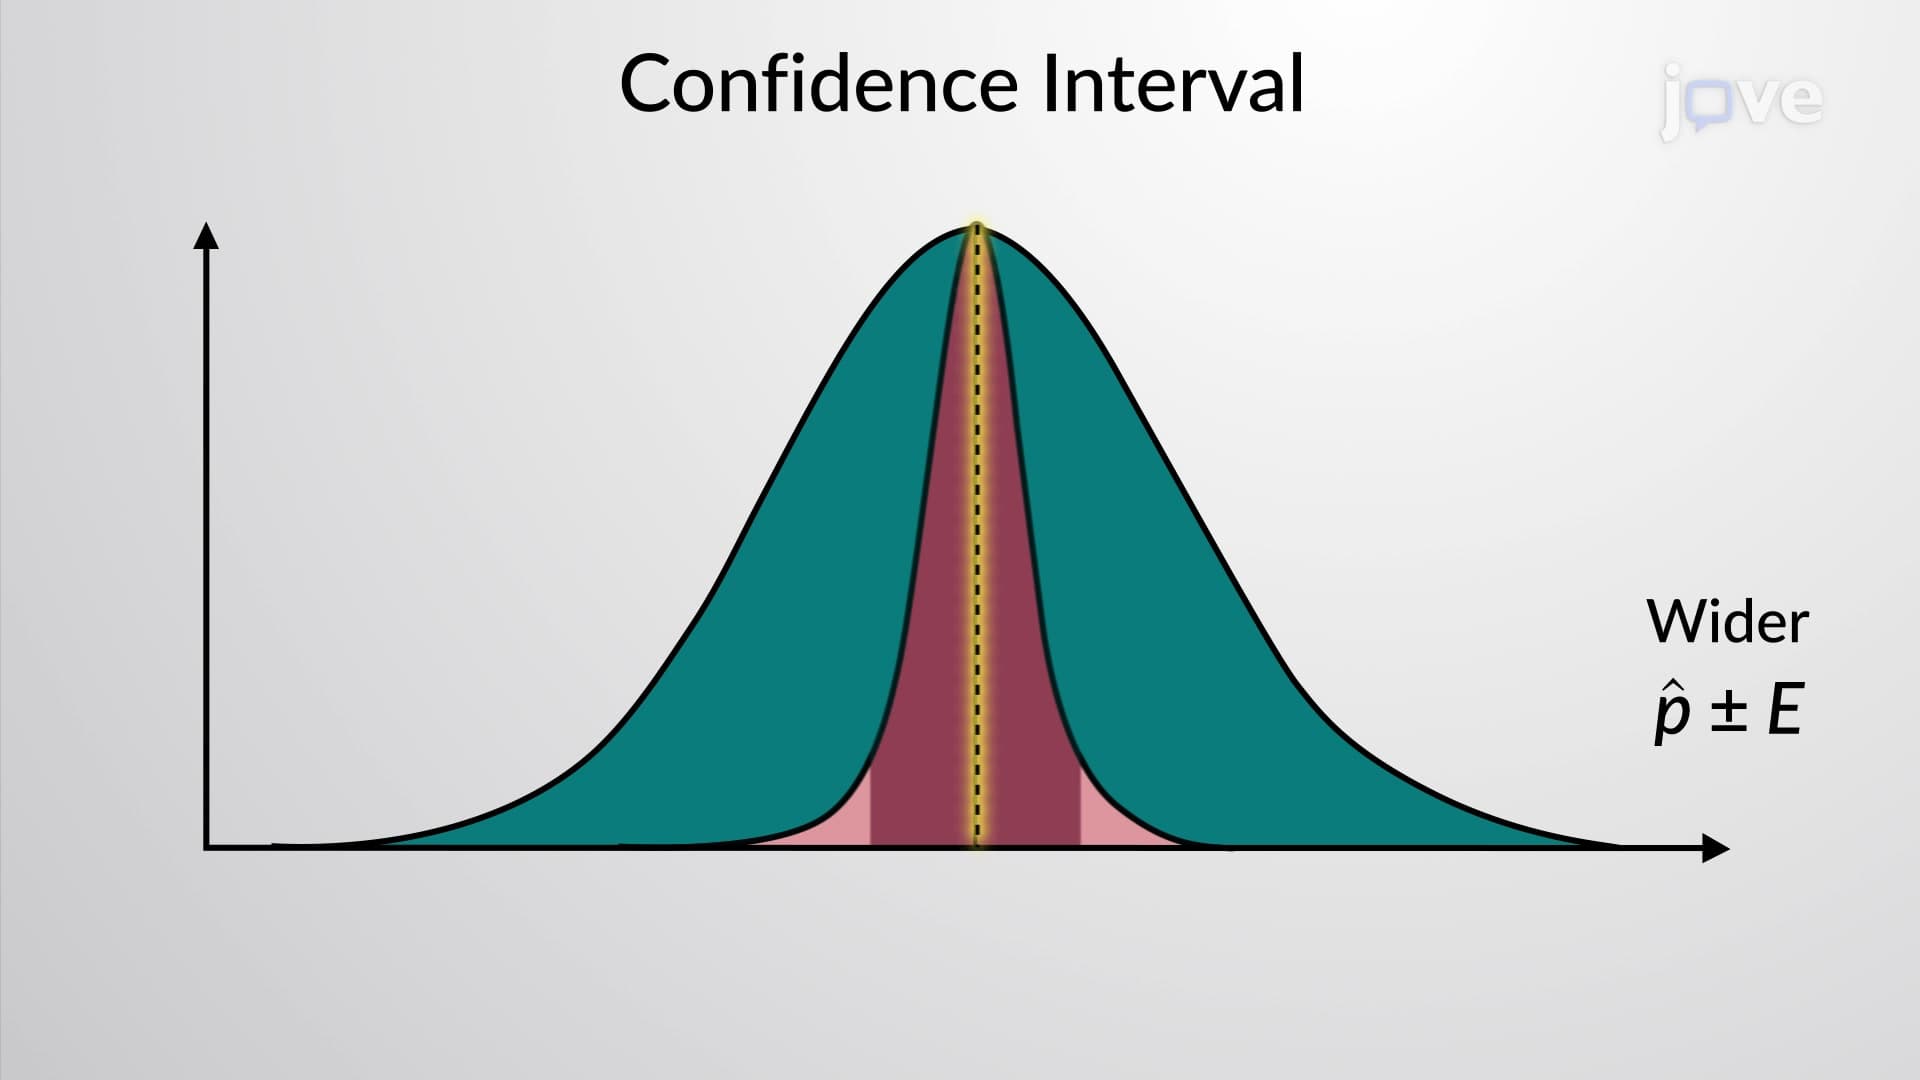
An unbiased point estimate is often insufficient to predict a population estimate, such as population mean or population proportion. In this scenario, a confidence interval is used. A confidence interval is an estimate similar to a sample proportion. However, unlike the point estimate which is a single value, the confidence interval contains a range of values. These values have lower and upper limits, known as confidence limits, and can be designated as L1 and L2, respectively.
A...
A...
6.1K
 00:54
Uncertainty: Confidence Intervals
3.1K
The confidence interval is the range of values around the mean that contains the true mean. It is expressed as a probability percentage. The interpretation of a 95% confidence interval, for instance, is that the statistician is 95% confident that the true mean falls within the interval. The upper and lower limits of this range are known as confidence limits. The confidence limits for the true mean are estimated from the sample's mean, the standard deviation, and the statistical factor...
3.1K
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K