在欧足联冠军联赛中,球队在进球和接球时的表现:分析五分钟间隔的分析
Paweł Chmura1, Toni Modric2, Adrian Drożdżowski3
1Department of Individual and Team Sports, Wroclaw University of Health and Sport Sciences, St. I.J. Paderewskiego 35, Wrocław, Poland.
BMC sports science, medicine & rehabilitation
|March 3, 2025

概括
足球教练可以通过分析目标事件期间的运行表现 (RP) 来改善决策. 减少RP与进球相关,影响比赛结果.
科学领域:
- 运动科学 运动科学 运动科学
- 足球分析 足球分析
- 绩效分析 绩效分析
背景情况:
- 足球教练的知情决策依赖于全面的绩效数据.
- 了解玩家行动和比赛事件之间的关系对于战术发展至关重要.
研究的目的:
- 在欧足联冠军联赛 (UCL) 中,在进球和输球的情况下,分析五分钟间隔的跑步表现 (RP).
- 调查得分和进球对总距离 (TD) 和高强度跑步 (HIR) 的影响.
主要方法:
- 使用InStat Fitness半自动视频系统对2020/2021赛季欧冠联赛比赛的分析.
- 统计分析包括单向ANOVA和效果大小的部分eta平方 (η2).
- 在特定与目标相关的间隔和不变的得分间隔中测量TD和HIR.
主要成果:
- 在不同的五分钟间隔中,当球队进球时,观察到TD和HIR的显著差异.
- 在多个间隔中,当球队承认进球时,TD和HIR的显著差异被注意到.
- 在球队承认进球的时间间隔中,始终观察到RP的大幅减少.
结论:
- 团队的跑步表现显著影响得分线,并间接影响比赛结果.
- 教练必须考虑节奏策略及其对团队RP和游戏动态的直接影响.
- 绩效分析为优化战术决策和训练方案提供了可操作的见解.
更多相关视频
相关概念视频
 01:12
Run Charts
43
Run charts serve as an essential instrument for visualizing the performance of various processes over time, enabling the identification of trends and patterns crucial for quality improvement. These charts map out a series of data points chronologically, offering insights into the stability and efficiency of a process. A run chart's creation involves plotting data points on a graph, with the time intervals on the horizontal axis and the specific measurements on the vertical axis. For...
43
 01:10
Standard Deviation
15.7K
The most commonly used measure of variation is the standard deviation. It is a numerical value measuring how far data values are from their mean. The standard deviation value is small when the data are concentrated close to the mean, exhibiting slight variation or spread. The standard deviation value is never negative, it is either positive or zero. The standard deviation is larger when the data values are more spread out from the mean, which means the data values are exhibiting more variation.
15.7K
 01:25
Interpreting Run Charts
52
Run charts, essentially line graphs plotted over time, serve as fundamental yet effective tools for process analysis. They chronicle data sequentially, facilitating the identification of trends, shifts, or cyclical movements. This graphical representation is instrumental in determining whether a process is stable or exhibits signs of potential instability indicative of special cause variation. In the healthcare domain, run charts depict infection rates over time, enabling hospitals to monitor...
52
 01:12
Boxplot
7.9K
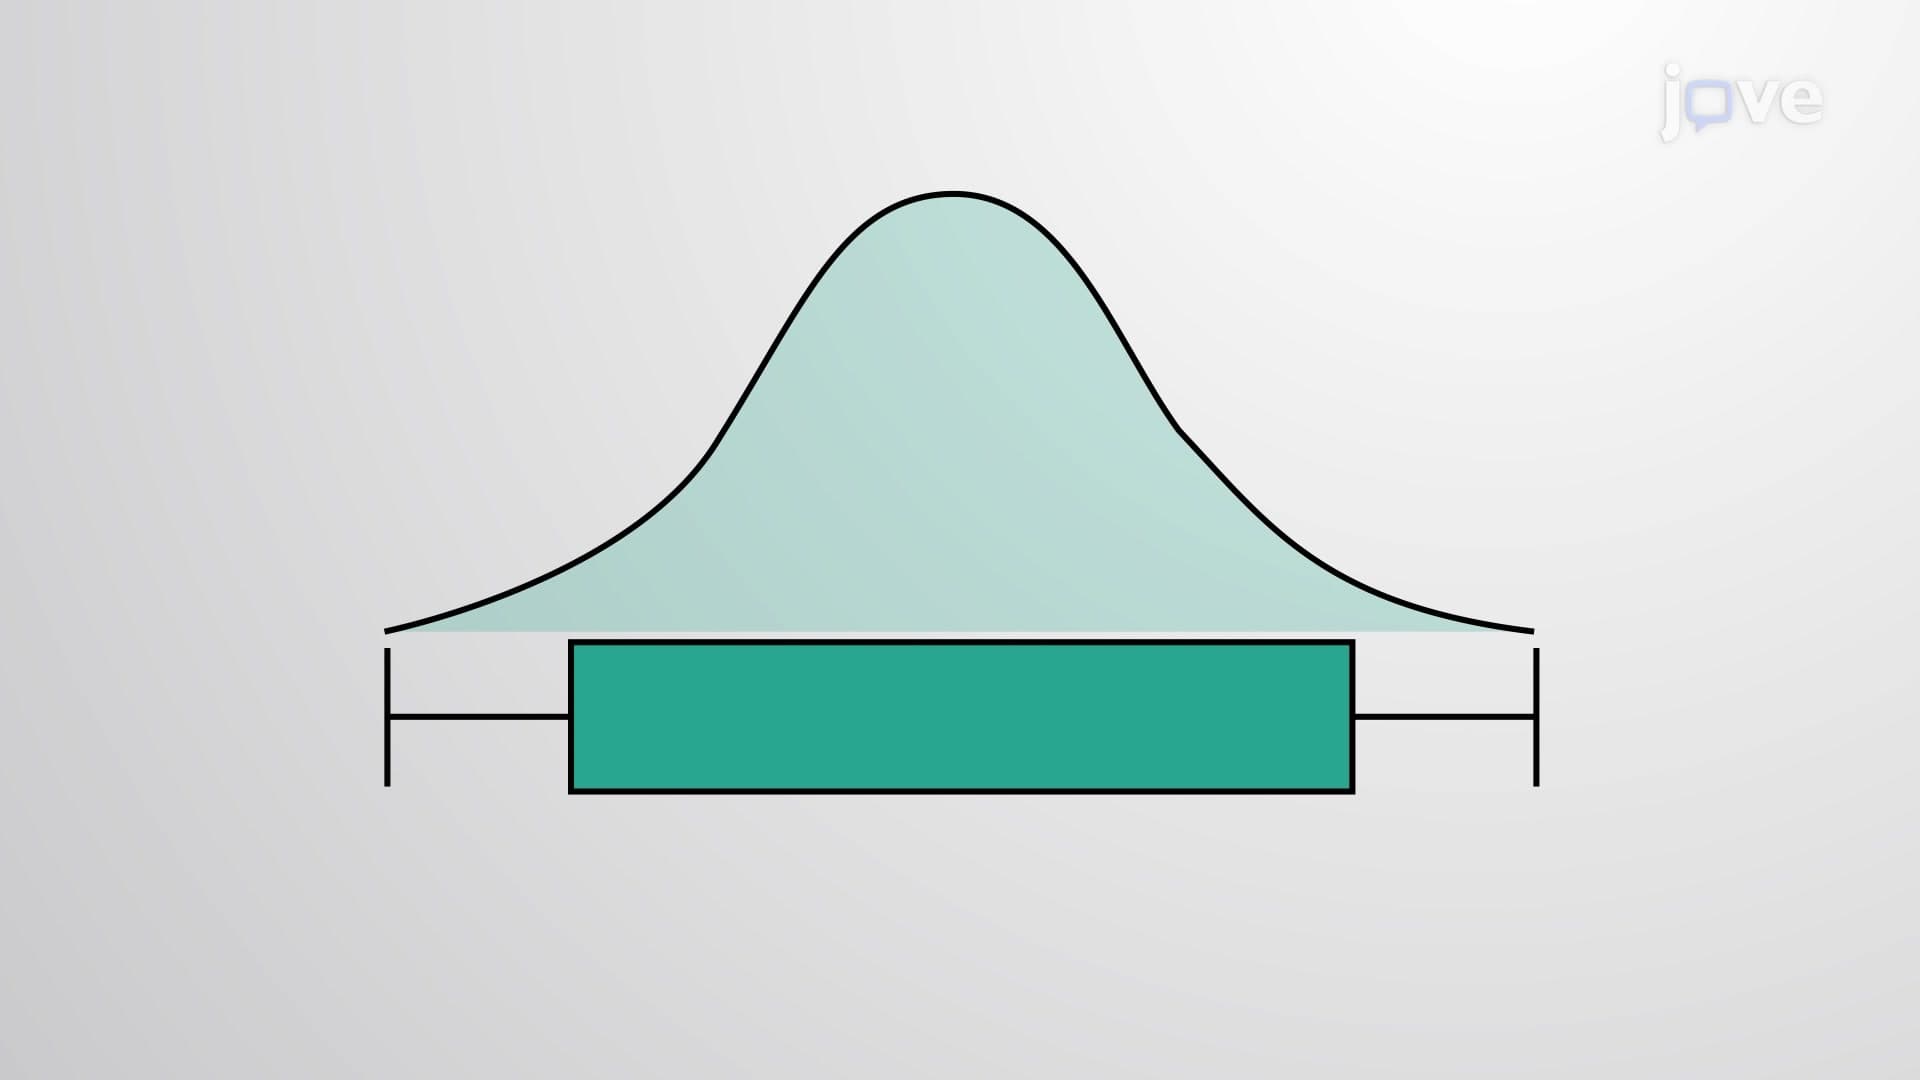
Box plots (also called box-and-whisker plots or box-whisker plots) give an excellent graphical image of the concentration of the data. They also show how far the extreme values are from most data. A box plot is constructed from five values: the minimum value, the first quartile, the median, the third quartile, and the maximum value. We use these values to compare how close other data values are to them. To construct a box plot, use a horizontal or vertical number line and a rectangular box. The...
7.9K
 01:17
Wald-Wolfowitz Runs Test II
171
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
171
 01:13
Mean Absolute Deviation
2.6K
The mean absolute deviation is also a measure of the variability of data in a sample. It is the absolute value of the average difference between the data values and the mean.
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
2.6K