学习颜色分布的平均值,但不是方差,提示目标位置的概率
Philippe Blondé1, Sabrina Hansmann-Roth2, David Pascucci3,4
1Icelandic Vision Laboratory, School of Health Sciences, University of Iceland, Reykjavik, Iceland. phblonde@hi.is.
Scientific reports
|March 4, 2025

概括
人类可以使用视觉线索学习统计位置规律,如颜色平均值,提高搜索速度. 然而,仅仅基于颜色变异的学习并未观察到,这表明这种统计学学习的局限性.
科学领域:
- 认知心理学 认知心理学
- 视觉感知 视觉感知 视觉感知
- 人与计算机的交互
背景情况:
- 人类擅长识别环境中的统计规律.
- 空间规律可以预测目标位置,通过灵活的空间优先级地图影响注意力.
- 刺激特征的作用,如颜色分布,在暗示这些空间规律性中的作用尚未完全理解.
研究的目的:
- 调查刺激特征,特别是颜色分布 (平均值和差异) 是否可以预测目标位置.
- 确定位置概率的统计学习是否受到不同的视觉背景的影响.
- 在视觉搜索任务中探索统计学习的局限性.
主要方法:
- 参与者执行了一个视觉搜索任务,在分心器中寻找一个奇怪的彩色目标.
- 干扰器是从颜色分布中绘制的,颜色分布的平均值或方差各不相同.
- 目标位置的概率与特定的颜色分布有关 (例如,左侧80%).
主要成果:
- 参与者学会了将颜色平均值与目标位置概率联系起来,在可预测的"丰富"位置显示更快的搜索时间.
- 当位置概率仅仅由颜色差异来决定时,没有观察到显著的学习或速度优势.
- 这表明统计学学习是灵活的,但受视觉线索类型的限制.
结论:
- 空间规律的统计学习可以适应不同的视觉环境,影响空间优先级地图.
- 学习取决于提示的性质,颜色平均值是有效的,但颜色差异不是.
- 这些发现强调了人类在视觉感知中的统计学习的灵活性和局限性.
相关概念视频
 01:32
Probability Distributions
6.7K
The probability of a random variable x is the likelihood of its occurrence. A probability distribution represents the probabilities of a random variable using a formula, graph, or table. There are two types of probability distribution– discrete probability distribution and continuous probability distribution.
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
6.7K
 01:12
Sampling Distribution
12.2K
Given simple random samples of size n from a given population with a measured characteristic such as mean, proportion, or standard deviation for each sample, the probability distribution of all the measured characteristics is called a sampling distribution. How much the statistic varies from one sample to another is known as the sampling variability of a statistic. You typically measure the sampling variability of a statistic by its standard error. The standard error of the mean is an example...
12.2K
 01:15
Depth Perception and Spatial Vision
508
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
508
 01:24
Color Vision
433
Color perception begins in the retina, the light-sensitive layer at the back of the eye. Two main theories explain how colors are seen: the trichromatic theory and the opponent-process theory. The trichromatic theory, proposed by Thomas Young in 1802 and extended by Hermann von Helmholtz in 1852, suggests that color vision is based on three types of cone receptors in the retina. These cones are sensitive to different but overlapping ranges of wavelengths corresponding to red, blue, and green.
433
 01:17
Probability Histograms
11.0K
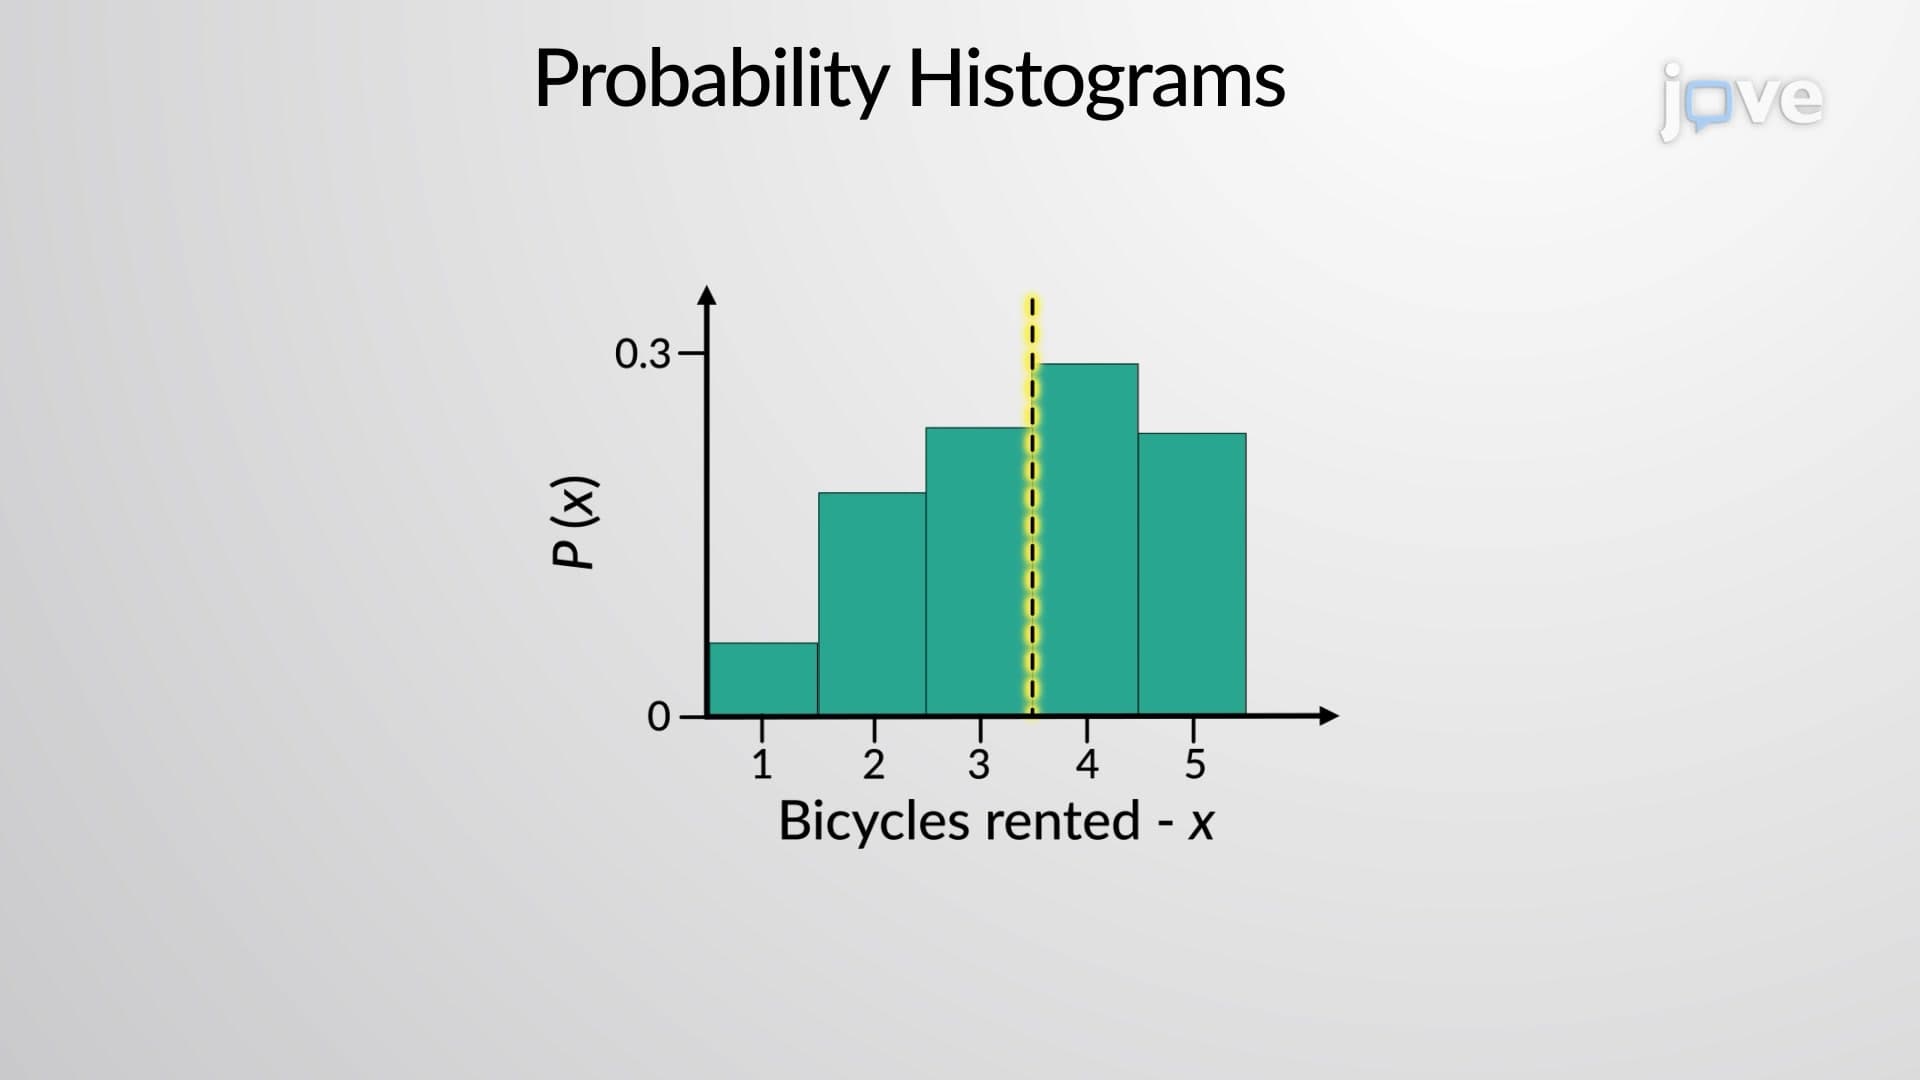
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
11.0K
 01:14
Central Limit Theorem
14.3K
The central limit theorem, abbreviated as clt, is one of the most powerful and useful ideas in all of statistics. The central limit theorem for sample means says that if you repeatedly draw samples of a given size and calculate their means, and create a histogram of those means, then the resulting histogram will tend to have an approximate normal bell shape. In other words, as sample sizes increase, the distribution of means follows the normal distribution more closely.
The sample size, n, that...
The sample size, n, that...
14.3K