

在两个波纹石墨烯板中预测高Tc的超导性,其中有间接的CeH9分子
M A Rastkhadiv1, M Pazoki2,3
1Estahban Higher Education Center-Shiraz University, Estahban, Iran.

概括
研究人员在用化 (CeH9) 分子杂的石墨烯层中发现了一种新的低压超导相转换. 这一突破实现了198.61K的临界温度,明显高于现有的高温超导体.
科学领域:
- 凝聚物质物理学 凝聚物质物理学
- 材料科学 材料科学 材料科学
- 量子力学就是量子力学.
背景情况:
- 最近的高温超导体,如H3S和LaH10,需要极端的压力 (>100 GPa),限制了实际应用.
- 对于在环境或近环境条件下运行的超导体有很大的需求.
- 基于石墨烯的异构结构为新的量子现象提供可调节的电子特性.
研究的目的:
- 研究一种新型材料系统中低压超导的潜力.
- 为了探索化 (CeH9) 分子在波纹石墨烯层中的间接作用.
- 确定特定的分子排列,最大限度地提高关键的超导过渡温度 (Tc).
主要方法:
- 利用最低级受约束变量方法计算电子和热力学属性.
- 系统地分析了CeH9分子在两个正弦形波纹石墨烯层之间9900个不同的分布.
- 计算了价值电子的能量间隙,以表征超导相位过渡.
主要成果:
- 预测了第二阶段过渡,在 198.61 K 的临界温度 (Tc) 上表现出超导性.
- 在环境压力条件下,在没有对石墨烯板施加外部压力的情况下,实现了这种高Tc.
- 观察到一种非传统的超导相转换,具有高临界电流密度 (~10^7 A cm-2).
结论:
- 在低压下使用石墨烯中的介质化物来实现高温超导的新途径.
- CeH9分子的特定周期排列,与石墨烯波纹相匹配,对于观察到的现象至关重要.
- 这一发现为开发实用,高性能超导材料提供了有希望的途径.

相关概念视频
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:07
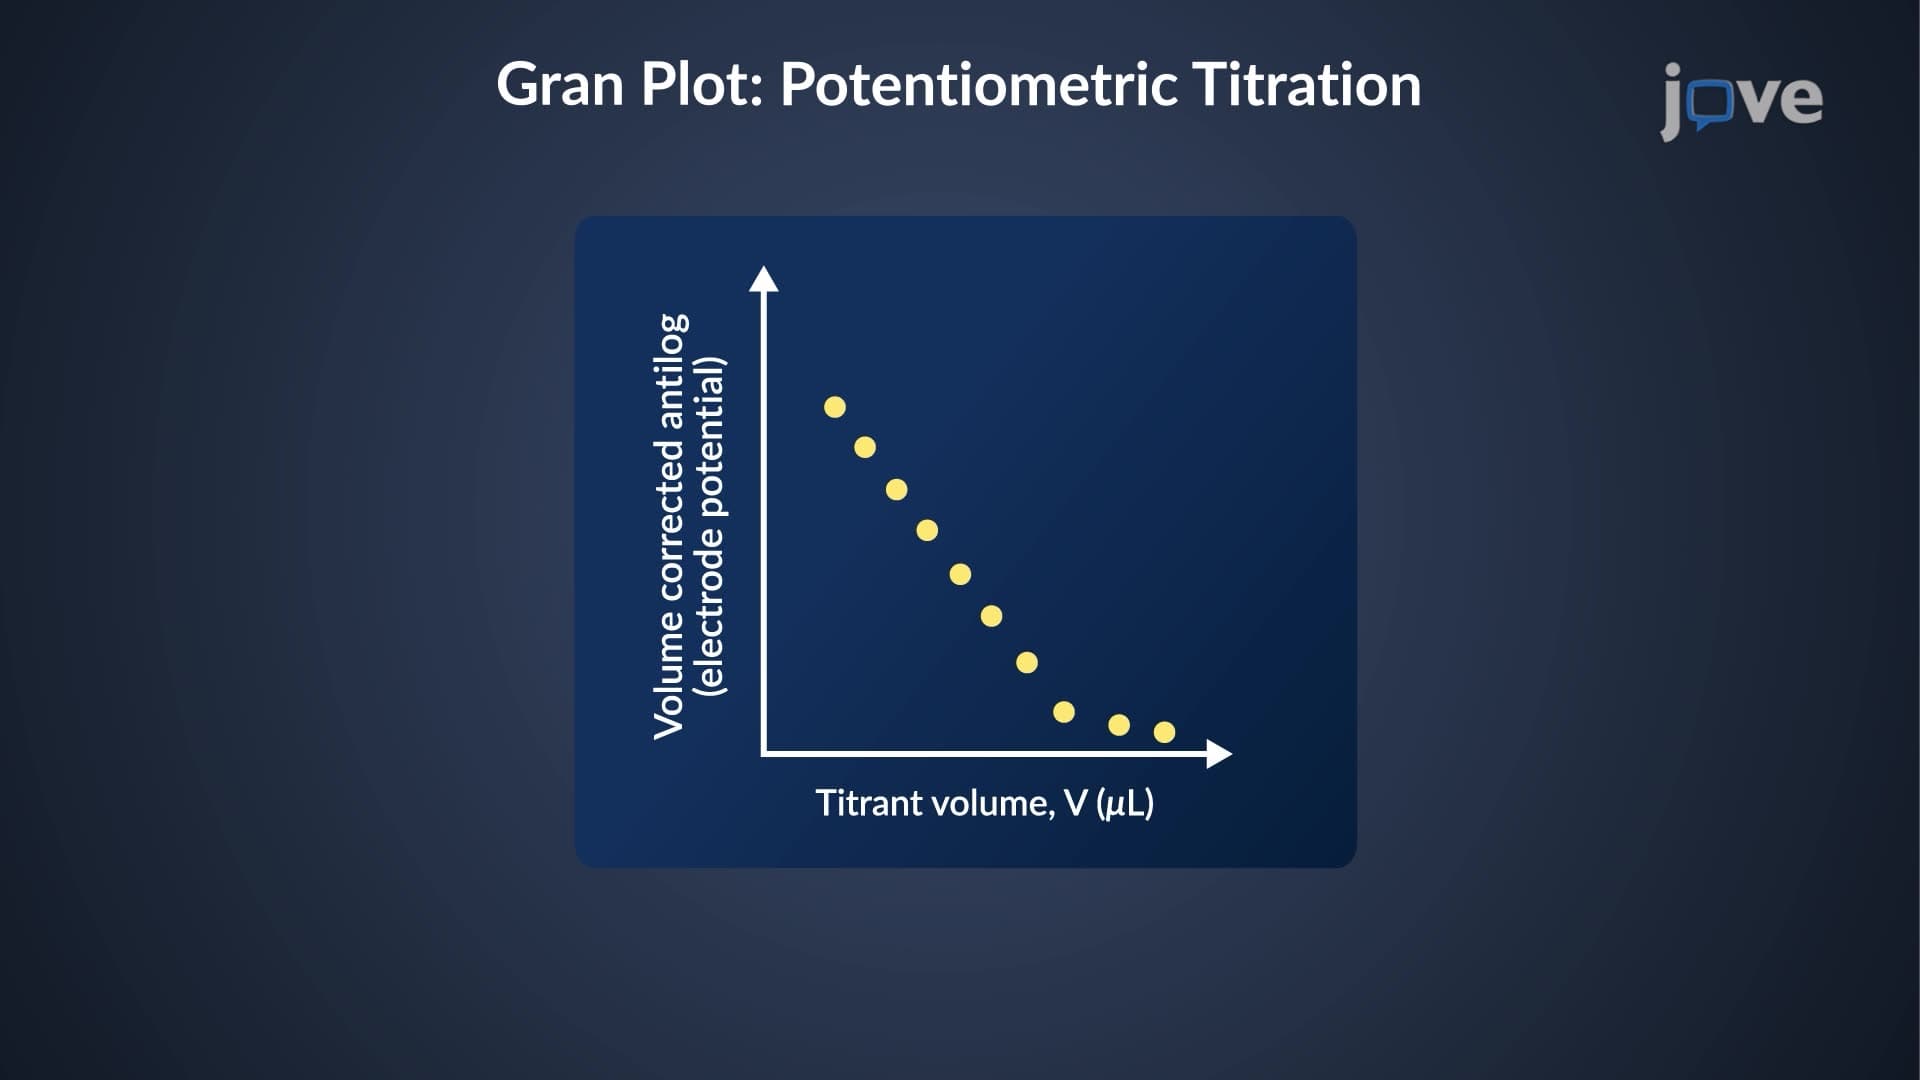
End Point Prediction: Gran Plot
218
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
218
 01:25
Errors occurring during blood pressure monitoring
579
Blood pressure monitoring is a crucial clinical procedure in diagnosing and managing various cardiovascular conditions. Despite its significance, the accuracy of blood pressure measurements can be compromised by multiple factors, potentially leading to either falsely high or low readings. These inaccuracies are critical as they can significantly impact patient care. So, it is vital to understand these challenges deeply and adopt strategic approaches to minimize errors.
Several factors...
Several factors...
579
 01:13
Sensitivity, Specificity, and Predicted Value
157
In healthcare diagnostics, laboratory tests play a crucial role in identifying and diagnosing a wide range of medical conditions. However, interpreting test results is not always straightforward. An abnormal test result does not always confirm the presence of a disease, just as a normal result does not guarantee its absence. To assess the reliability of these diagnostic tools, healthcare practitioners rely on two key statistical indicators: sensitivity and specificity.
Sensitivity is the...
Sensitivity is the...
157
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:08
Determination of Expected Frequency
2.1K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.1K