
一个用于校准短语音信号 (单音单词) 的定量协议,该协议基于发声语音的50毫秒段,具有最大根-平均-平方幅度
Journal of the American Academy of Audiology
|March 14, 2025

概括
一个新的语音信号振幅校准协议标准化了测试单词和载体短语水平. 这种方法使用50ms的分段.
科学领域:
- 听力学 听力学是指听力学.
- 语音科学 语言科学
- 信号处理 信号处理
背景情况:
- 传统的听觉测试使用带有无控制幅度的载体短语.
- 当前的标准将测试单词级别与载体短语联系起来,引入可变性.
- 语音信号中的幅度调制使校准复杂化.
研究的目的:
- 开发一个客观的振幅校准协议,用于短时间的语音信号.
- 为了提高语音信号振幅设置的准确性和可复制性.
- 为了解决当前音量计校准标准中的局限性.
主要方法:
- 评估的平方根均值 (rms) 幅度为12.5至100ms的音频段.
- 确定幅度分析的最佳分段持续时间 (50毫秒).
- 标准化载体短语和测试词的幅度到目标rms级别.
主要成果:
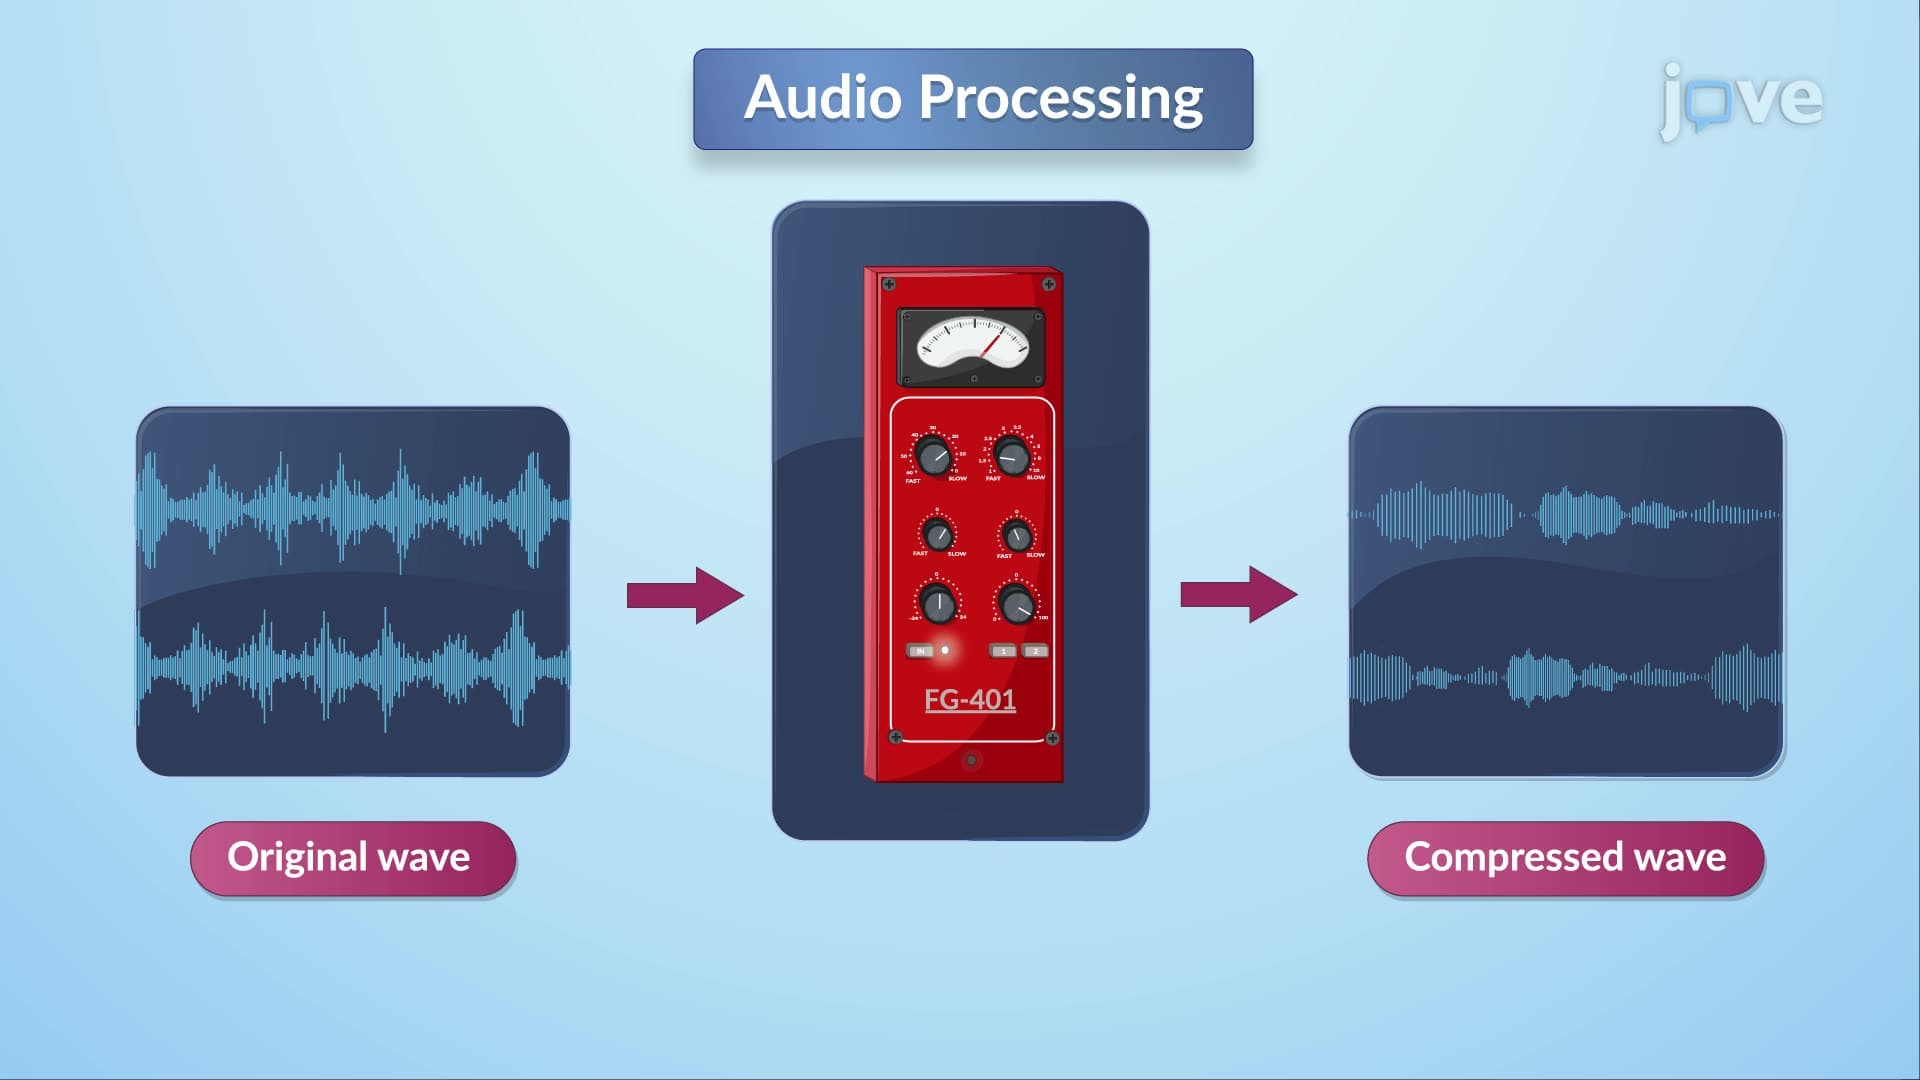
- 完成的协议使用50毫秒发音的语音段的rms振幅.
- 直接链接校准音调和测试词段幅度.
- 对载体短语的均幅度,以及对跨扬声器的测试单词的实质性扩展.
结论:
- 开发的协议有效地校准了语音信号幅度.
- 提供一个客观和可复制的方法来实现振幅均等.
- 在不同扬声器中提高听力测试材料的一致性.
相关概念视频
 01:06
Echo
The human ear cannot distinguish between two sources of sound if they happen to reach within a specific time interval, typically 0.1 seconds apart. More than this, and they are perceived as separate sources.
Imagine the sound is reflected back to the ears. Assuming that the source is very close to the human, the difference between hearing the two sounds—the emitted sound and the reflected sound—may be more than the minimum time for perceiving distinct sounds. If this is the case, then the...
Imagine the sound is reflected back to the ears. Assuming that the source is very close to the human, the difference between hearing the two sounds—the emitted sound and the reflected sound—may be more than the minimum time for perceiving distinct sounds. If this is the case, then the...
 01:16
Basic Discrete Time Signals
The unit step sequence is defined as 1 for zero and positive values of the integer n. This sequence can be graphically displayed using a set of eight sample points, showing a step function starting from n=0 and remaining constant thereafter.
The unit impulse or sample sequence is mathematically expressed as zero for all n values except at n=0, where it is one. The unit impulse sequence, denoted by δ(n), is the first difference of the unit step sequence, while the unit step sequence u(n) is the...
The unit impulse or sample sequence is mathematically expressed as zero for all n values except at n=0, where it is one. The unit impulse sequence, denoted by δ(n), is the first difference of the unit step sequence, while the unit step sequence u(n) is the...
 01:18
Parseval's Theorem
Parseval's theorem is a fundamental concept in signal processing and harmonic analysis. It asserts that for a periodic function, the average power of the signal over one period equals the sum of the squared magnitudes of all its complex Fourier coefficients. This theorem, named after Marc-Antoine Parseval, provides a powerful tool for analyzing the energy distribution in signals.
Interestingly, Parseval's theorem also holds for the trigonometric form of the Fourier series, which expresses a...
Interestingly, Parseval's theorem also holds for the trigonometric form of the Fourier series, which expresses a...
 01:11
Sampling Continuous Time Signal
In signal processing, a continuous-time signal can be sampled using an impulse-train sampling technique, followed by the zero-order hold method. Impulse-train sampling involves the use of a periodic impulse train, which consists of a series of delta functions spaced at regular intervals determined by the sampling period. When a continuous-time signal is multiplied by this impulse train, it generates impulses with amplitudes corresponding to the signal's values at the sampling points.
In the...
In the...
 01:20
Downsampling
When considering a sampled sequence with zero values between sampling instants, one can replace it by taking every N-th value of the sequence. At these integer multiples of N, the original and sampled sequences coincide. This process, known as decimation, involves extracting every N-th sample from a sequence, thereby creating a more efficient sequence.
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:29
Non-Verbal Cues
Non-verbal communication extends beyond gestures and facial expressions to include vocal elements known as paralanguage. Paralanguage consists of non-verbal vocal cues such as pitch, loudness, speech rate, pauses, and non-verbal vocalizations like laughter, sighs, and moans. These elements not only accompany speech but also provide critical emotional and contextual information.The Role of Paralanguage in CommunicationParalanguage adds depth to spoken language by conveying emotions and...