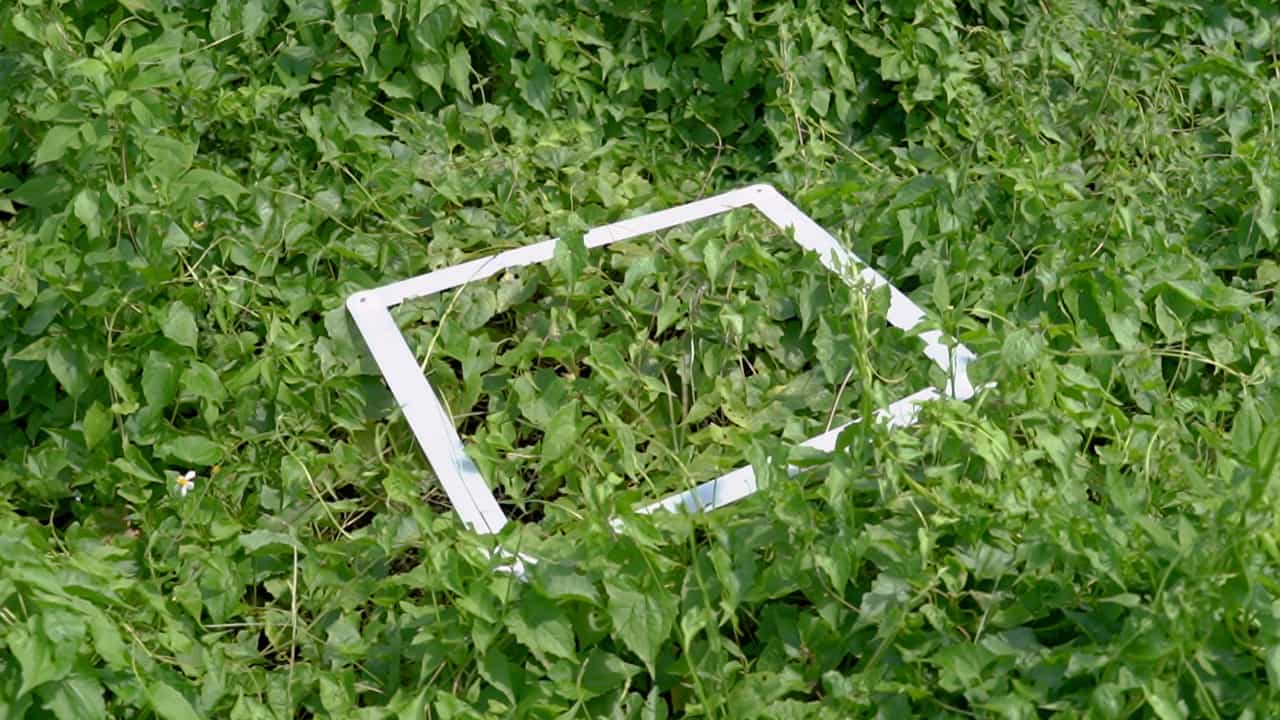
评估后勤回归和地理加权后勤回归模型,以预测贝宁的肉甜采用意图
Idrissou Ahoudou1, Nicodeme V Fassinou Hotegni2, Charlotte O A Adjé2
1Genetics, Biotechnology and Seed Science Unit (GBioS), Laboratory of Crop Production, Physiology and Plant Breeding (PAGEV), Faculty of Agronomic Sciences (FSA), University of Abomey-Calavi (UAC), Tri Postal Cotonou, 01 BP 526, Abomey-Calavi, Republic of Benin. idrisahoudou@gmail.com.
Scientific reports
|March 15, 2025

概括
采用肉甜 (OFSP) 的预测模型对于粮食安全至关重要. 一个地理加权后勤回归 (GWLR) 模型准确地预测了贝宁的农民采用意图,超过了标准后勤回归.
科学领域:
- 农业经济学 农业经济学
- 粮食安全 粮食安全
- 生物强化是一种生物强化.
背景情况:
- 像肉甜 (OFSP) 这样的生物强化作物的低采用率构成了粮食安全的重大挑战.
- 准确预测农民采用意图对于成功的作物育种和引入计划至关重要.
研究的目的:
- 确定在贝宁农民中对OFSP采用意向的关键预测因素.
- 用先进的建模技术分析这些预测因素的区域变化.
主要方法:
- 使用后勤回归 (LR) 和地理加权后勤回归 (GWLR) 模型.
- 综合多种预测因素,包括社会,地理和心理因素.
- 在贝宁的不同甜生产区模拟采用意图.
主要成果:
- 与LR模型 (87%) 相比,GWLR模型实现了更高的验证精度 (94.2%).
- GWLR有效地确定了具有高OFSP采用倾向的地区,主要是在贝宁北部.
- 关键的驱动因素表现出显著的空间异质性,在不同地区对采用意图产生不同的影响.
结论:
- 与标准LR相比,地理加权后勤回归 (GWLR) 对OFSP采用意向提供了更好的预测能力.
- 了解影响因素的空间变化对于有针对性的干预来促进生物强化作物的采用至关重要.
- 在农业发展项目中,GWLR为提高采用预测的可靠性提供了有价值的工具.
相关概念视频
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K
 01:11
Regression Analysis
5.5K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.5K
 01:19
Survival Tree
49
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
49