
临床干预研究中的顺序结果数据的元分析方法:用可重现的研究进行范围审查
Ali Mulhem1,2
1Westfälische Wilhelms-Universität Münster, Münster, Germany.
PloS one
|April 1, 2025

概括
对顺序结果数据的元分析是复杂的. 这次审查发现了最佳方法的知识差距,突出了对临床研究的顺序,二进制和连续模型的进一步研究的需要.
科学领域:
- 生物统计学 生物统计学
- 临床研究方法论 临床研究方法论
- 证据综合 证据综合
背景情况:
- 与二进制或连续数据相比,对顺序结果数据的元分析存在独特的挑战.
- 对于顺序结果的元分析方法的现有文献需要全面的总结和评估.
研究的目的:
- 系统地审查和总结当前生物医学文献的元分析方法的顺序结果.
- 试图复制以前关于顺序元分析方法的研究结果.
主要方法:
- 在MEDLINE,EMBASE和PsycINFO数据库中进行系统的文献搜索,并通过引用搜索来补充.
- 使用Covidence软件对333条记录进行选,包括两阶段选.
- 在临床干预研究中包括报告或比较顺序结果的元分析方法的研究;在数据允许的情况下,尝试进行可重复的研究.
主要成果:
- 四项方法研究符合纳入标准,重点是5-20类别的顺序尺度.
- 识别的方法包括顺序模型 (比例赔率,概括赔率),二元模型 (二分化) 和连续模型.
- 没有一项研究提供了全面的比较;可复制性尝试产生了差异,表明现有研究或解释中的潜在问题.
结论:
- 关于在临床环境中获得顺序结果的最佳元分析方法,仍然存在重大知识差距.
- 进一步的方法研究是必不可少的,以开发一个强大的证据基础来选择合适的元分析方法对顺序数据.
更多相关视频
 06:55
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
14.3K
 00:04
A Clinical Trial Assessing the Safety, Efficacy, and Delivery of Olive-Oil-Based Three-Chamber Bags for Parenteral Nutrition
Published on: September 20, 2019
10.6K
相关概念视频
 00:55
Ordinal Level of Measurement
22.6K
The way a set of data is measured is called its level of measurement. Correct statistical procedures depend on a researcher being familiar with levels of measurement. For analysis, data are classified into four levels of measurement—nominal, ordinal, interval, and ratio.
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
22.6K
 01:23
Types of Biopharmaceutical Studies: Controlled and Non-Controlled Approaches
106
Biopharmaceutical studies constitute a vital field aiming to enhance drug delivery methods and refine therapeutic approaches, drawing upon diverse interdisciplinary knowledge. In research methodologies, the choice between controlled and non-controlled studies significantly influences the study's reliability and accuracy.
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
106
 01:09
Odds Ratio
86
The odds ratio (OR) is a statistical measure used extensively in epidemiology and research to quantify the strength of association between exposure and outcome across different groups. Unlike relative risk, which compares the probabilities of an event occurring, the odds ratio compares the odds of an event occurring in the exposed group to the odds of it occurring in the unexposed group. The odds, in this context, are calculated as the probability of the event happening divided by the...
86
 01:20
Comparing the Survival Analysis of Two or More Groups
96
Survival analysis is a cornerstone of medical research, used to evaluate the time until an event of interest occurs, such as death, disease recurrence, or recovery. Unlike standard statistical methods, survival analysis is particularly adept at handling censored data—instances where the event has not occurred for some participants by the end of the study or remains unobserved. To address these unique challenges, specialized techniques like the Kaplan-Meier estimator, log-rank test, and...
96
 01:21
Friedman Two-way Analysis of Variance by Ranks
112
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
112
 01:02
Ranks
209
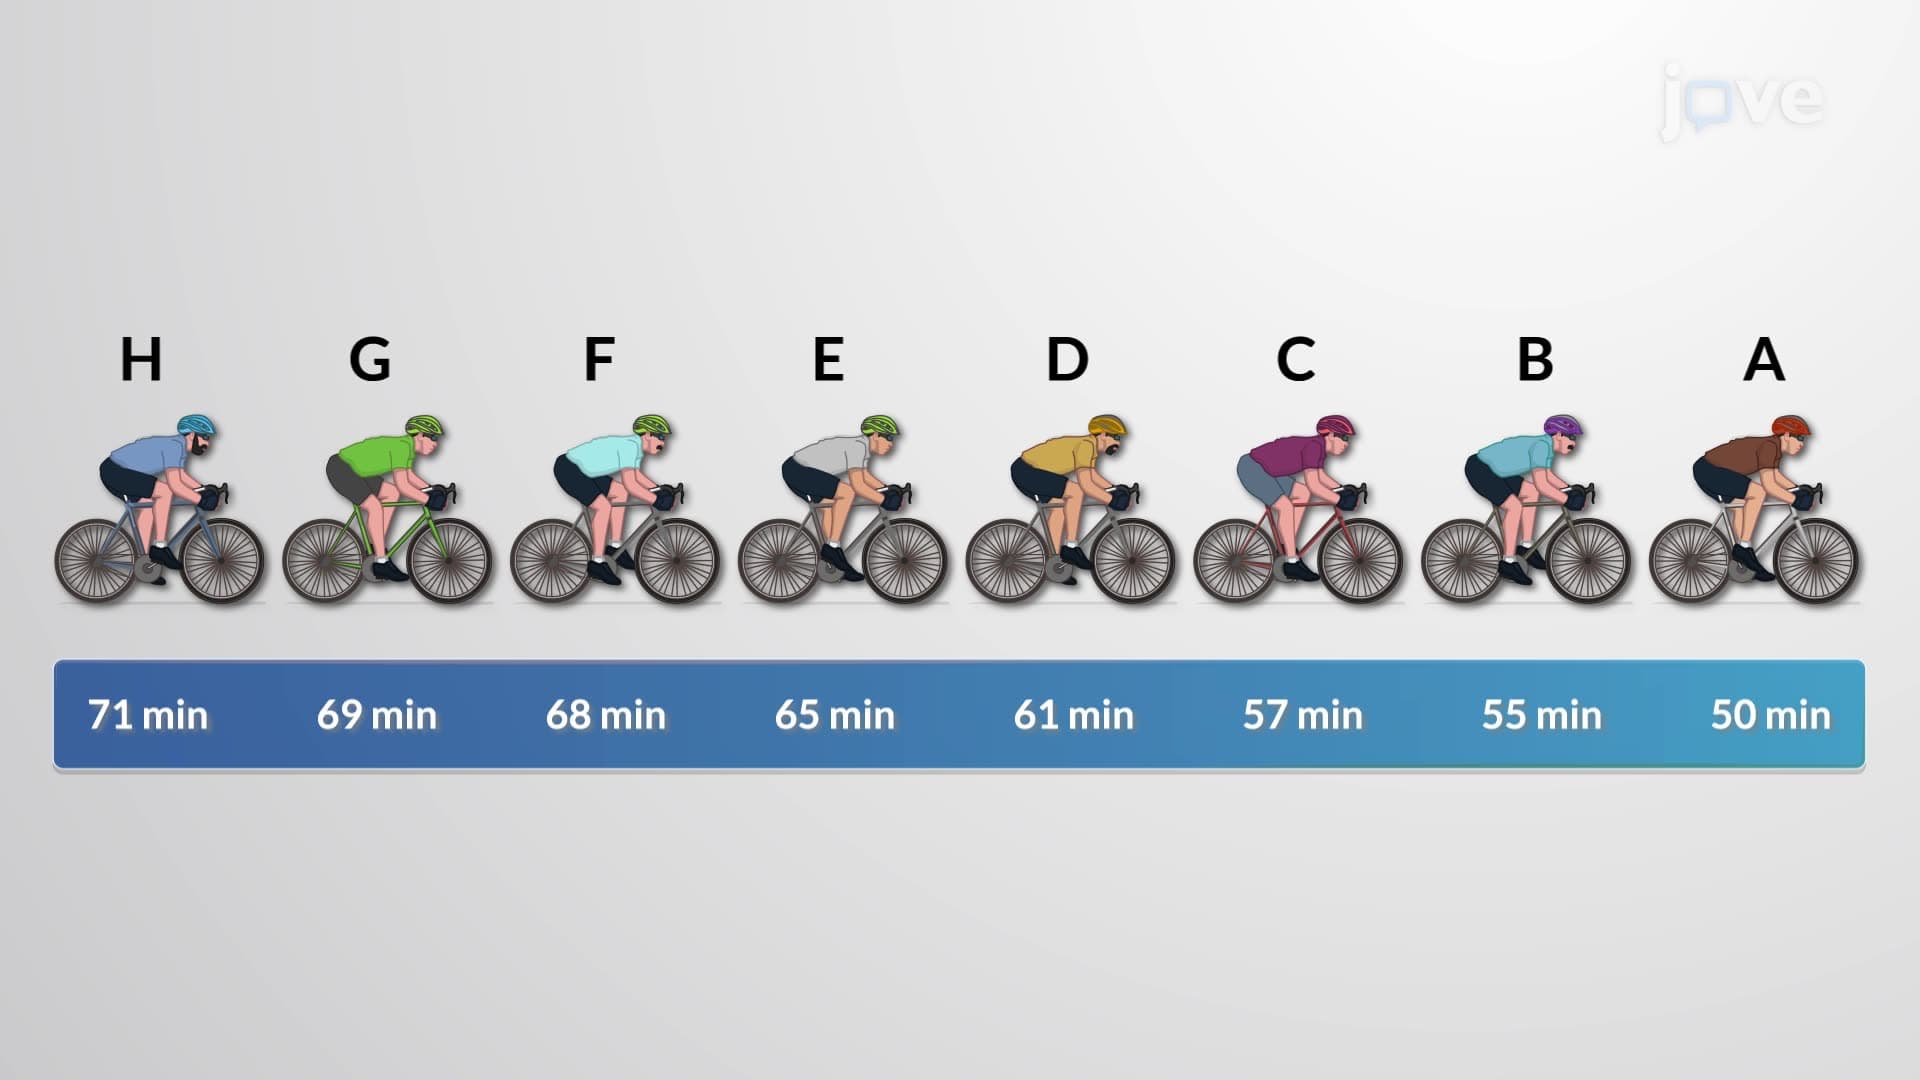
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
209