

在高维微阵列数据中选择特征的修改强大的比例重叠得分
Muhammad Hamraz1, Tahir Abbas2, Fawad Ali1
1Department of Statistics, Abdul Wali Khan University, Mardan, 23200, Pakistan.
Computers in biology and medicine
|April 15, 2025

概括
修改后的强大比例重叠评分 (MRPOS) 从高维基基因表达数据中有效地选择歧视性基因. 这种新的特征选择方法解决了维度的诅咒,提高了生物研究中的分类准确性.
科学领域:
- 生物信息学是一种生物信息学.
- 计算生物学 计算生物学
- 基因组学就是基因组学.
背景情况:
- 高维微阵列数据集由于维度 (n << p) 的诅咒而存在挑战.
- 传统的特征选择方法与这些数据集中大量的基因和有限的样本作斗争.
- 有效的基因选择对于准确的生物数据分析和分类至关重要.
研究的目的:
- 引入修改后的强大比例重叠得分 (MRPOS),一种新的特征选择方法.
- 在高维基基因表达数据中增强对二元分类问题的基因选择.
- 通过最大限度地减少阶级间的相似性和最大限度地提高阶级差异化来强有力的识别歧视性基因.
主要方法:
- 为了基因评估,MRPOS使用了强大的分散统计数据 (Sn和Qn).
- 基因表达重叠被评估以确定最能区分类别的基因.
- 使用了四个基因表达数据集,分为70%的培训和30%的测试子集.
- 使用随机森林,k-NN和SVM分类器对现有的四种特征选择技术进行了性能评估.
主要成果:
- MRPOS在识别歧视性基因方面表现出有效性.
- 该方法成功地减少了维度的诅咒的影响.
- 分析和可视化了分类错误率,显示了MRPOS的优势.
- 对比分析证实了拟议方法与既有技术相比具有独特性和有效性.
结论:
- 修改的强健比例重叠得分 (MRPOS) 是一个高效的特征选择方法,用于高维基基因表达数据.
- 在生物信息学中,MRPOS提供了一种强大的方法来克服维度的诅咒.
- 拟议的方法显示了提高生物研究分类准确性的巨大潜力.

相关概念视频
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.3K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.3K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 02:26
Comparing Copy Number Variations and SNPs
16.8K
Sequencing of the human genome has opened up several best-kept secrets of the genome. Scientists have identified thousands of genome variations that exist within a population. These variations can be a single nucleotide or a larger chromosomal variation.
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
16.8K
 02:34
DNA Microarrays
17.1K
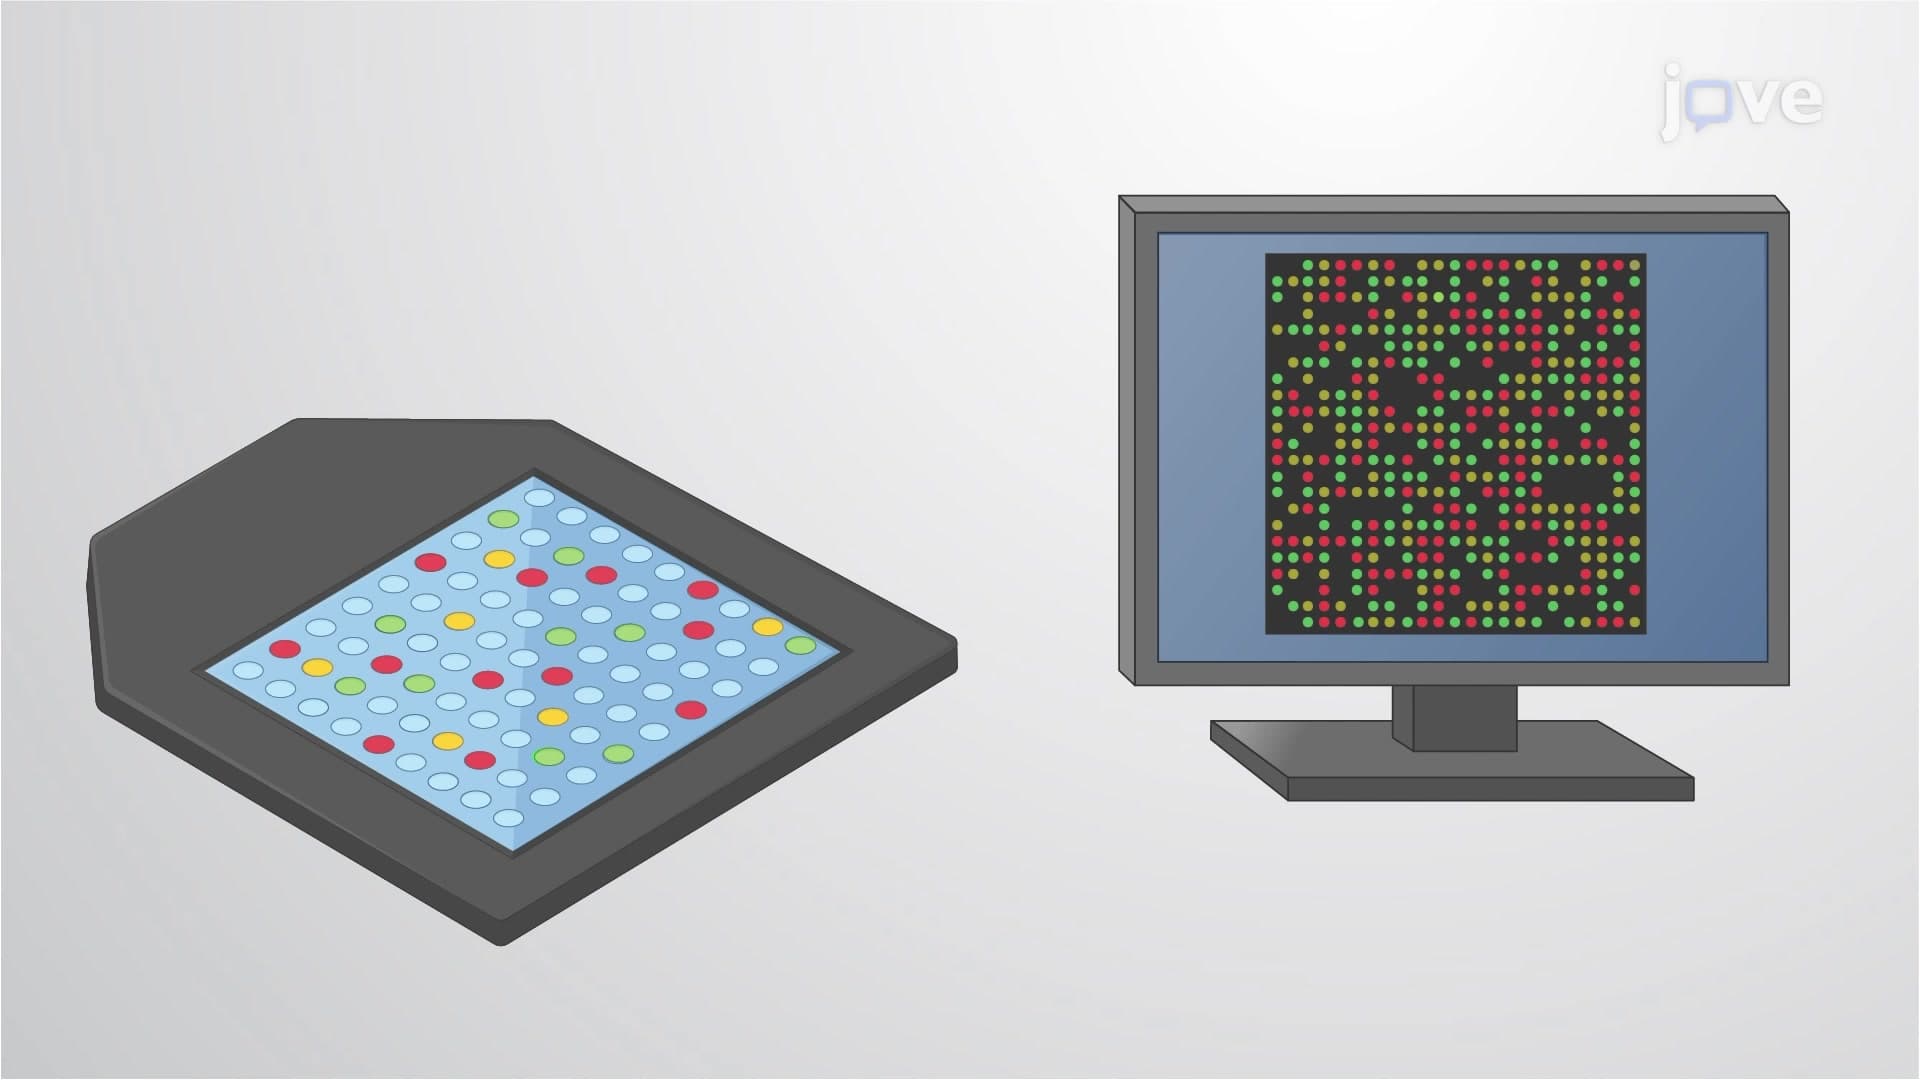
Microarrays are high-throughput and relatively inexpensive assays that can be automated to analyze large quantities of data at a time. They are used in genome-wide studies to compare gene or protein expression under two varied conditions, such as healthy and diseased states. Microarrays consist of glass or silica slides on which probe molecules are covalently attached through surface functionalization. Most commonly, the slides are prepared through the chemisorption of silanes to silica...
17.1K
 01:09
Wilcoxon Signed-Ranks Test for Matched Pairs
63
The Wilcoxon signed-rank test for matched pairs evaluates the null hypothesis by combining the ranks of differences with their signs. It essentially tests whether the median of the differences in a population of matched pairs is zero. Since the test incorporates more information than the sign test, it generally yields more trustable conclusions. This test also does not require the data to follow a normal distribution, but two conditions must be met for it to be applicable: (1) the data must...
63
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population
73
The Wilcoxon signed-rank test for the median of a single population is a nonparametric test used to evaluate whether the median of a population differs from a specified value. Unlike parametric tests, it does not require data to follow a normal distribution, making it suitable for non-normal or small samples. The test begins by calculating the difference (d) between each observation and the hypothesized median. The absolute values of these differences are ranked in ascending order, with ties...
73