使用可解释的机器学习方法,揭示住院COVID-19患者中患者-医院风险因素的相关交叉波模式
Fernanda Cristina Barbosa Lana1, Carolina Coimbra Marinho2, Bruno Barbosa Miranda de Paiva3
1Universidade Federal de Minas Gerais, Av. Presidente Antônio Carlos, Belo Horizonte, 6627, Brazil. fernandacblana@gmail.com.
BMC infectious diseases
|April 15, 2025

概括
时间数据转移影响了COVID-19结果预测. 周围动脉氧和与吸入氧比率 (SatO2 / FiO2) 的比例,以及淋巴细胞计数是整个大流行期间不良结果的关键预测指标.
科学领域:
- 医疗信息学 医疗信息学
- 流行病学 流行病学
- 机器学习 机器学习
背景情况:
- 之前关于COVID-19不良结果的研究缺乏对时间数据转移的分析.
- 这项研究探讨了不断演变的流行病浪潮对预测因素-结果关联的影响.
研究的目的:
- 评估患者和医院因素预测医院死亡率,侵入性机械通风 (IMV) 和重症监护室 (ICU) 转移.
- 分析这些预测如何在不同的流行浪潮中发生变化.
主要方法:
- 在16958名COVID-19患者的多中心回顾性队列研究中 (2020年3月 - 2022年8月).
- 流行病分为三个波进行分析.
- 光梯度增强机 (LightGBM) 使用沙普利增材解释 (SHAP) 值用于识别风险因素.
主要成果:
- 观察到时间漂移,降低了跨波的预测模型性能.
- 周围动脉氧和与吸入氧的比率 (SatO2 / FiO2) 的部分是所有结果的强有力的预测因素.
- 淋巴缺血的预测强度随着时间的推移而增加;在第二波中,血小板缺血是至关重要的.
结论:
- 数据漂移显著影响了预测模型的能力.
- 血小板和淋巴细胞计数SatO2 / FiO2是不利的COVID-19结果的关键预测指标.
- 将时间漂移知识集成到模型中对于保持预测准确性至关重要.
相关概念视频
 01:18
Steps in Outbreak Investigation
95
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
95
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K
 01:21
Causality in Epidemiology
169
Causality or causation is a fundamental concept in epidemiology, vital for understanding the relationships between various factors and health outcomes. Despite its importance, there's no single, universally accepted definition of causality within the discipline. Drawing from a systematic review, causality in epidemiology encompasses several definitions, including production, necessary and sufficient, sufficient-component, counterfactual, and probabilistic models. Each has its strengths and...
169
 01:27
Confounding in Epidemiological Studies
111
Confounding in statistical epidemiology represents a pivotal challenge, referring to the distortion in the perceived relationship between an exposure and an outcome due to the presence of a third variable, known as a confounder. This variable is associated with both the exposure and the outcome but is not a direct link in their causal chain. Its presence can lead to erroneous interpretations of the exposure's effect, either exaggerating or underestimating the true association. This...
111
 01:29
Bias in Epidemiological Studies
98
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
98
 01:11
Variability: Analysis
116
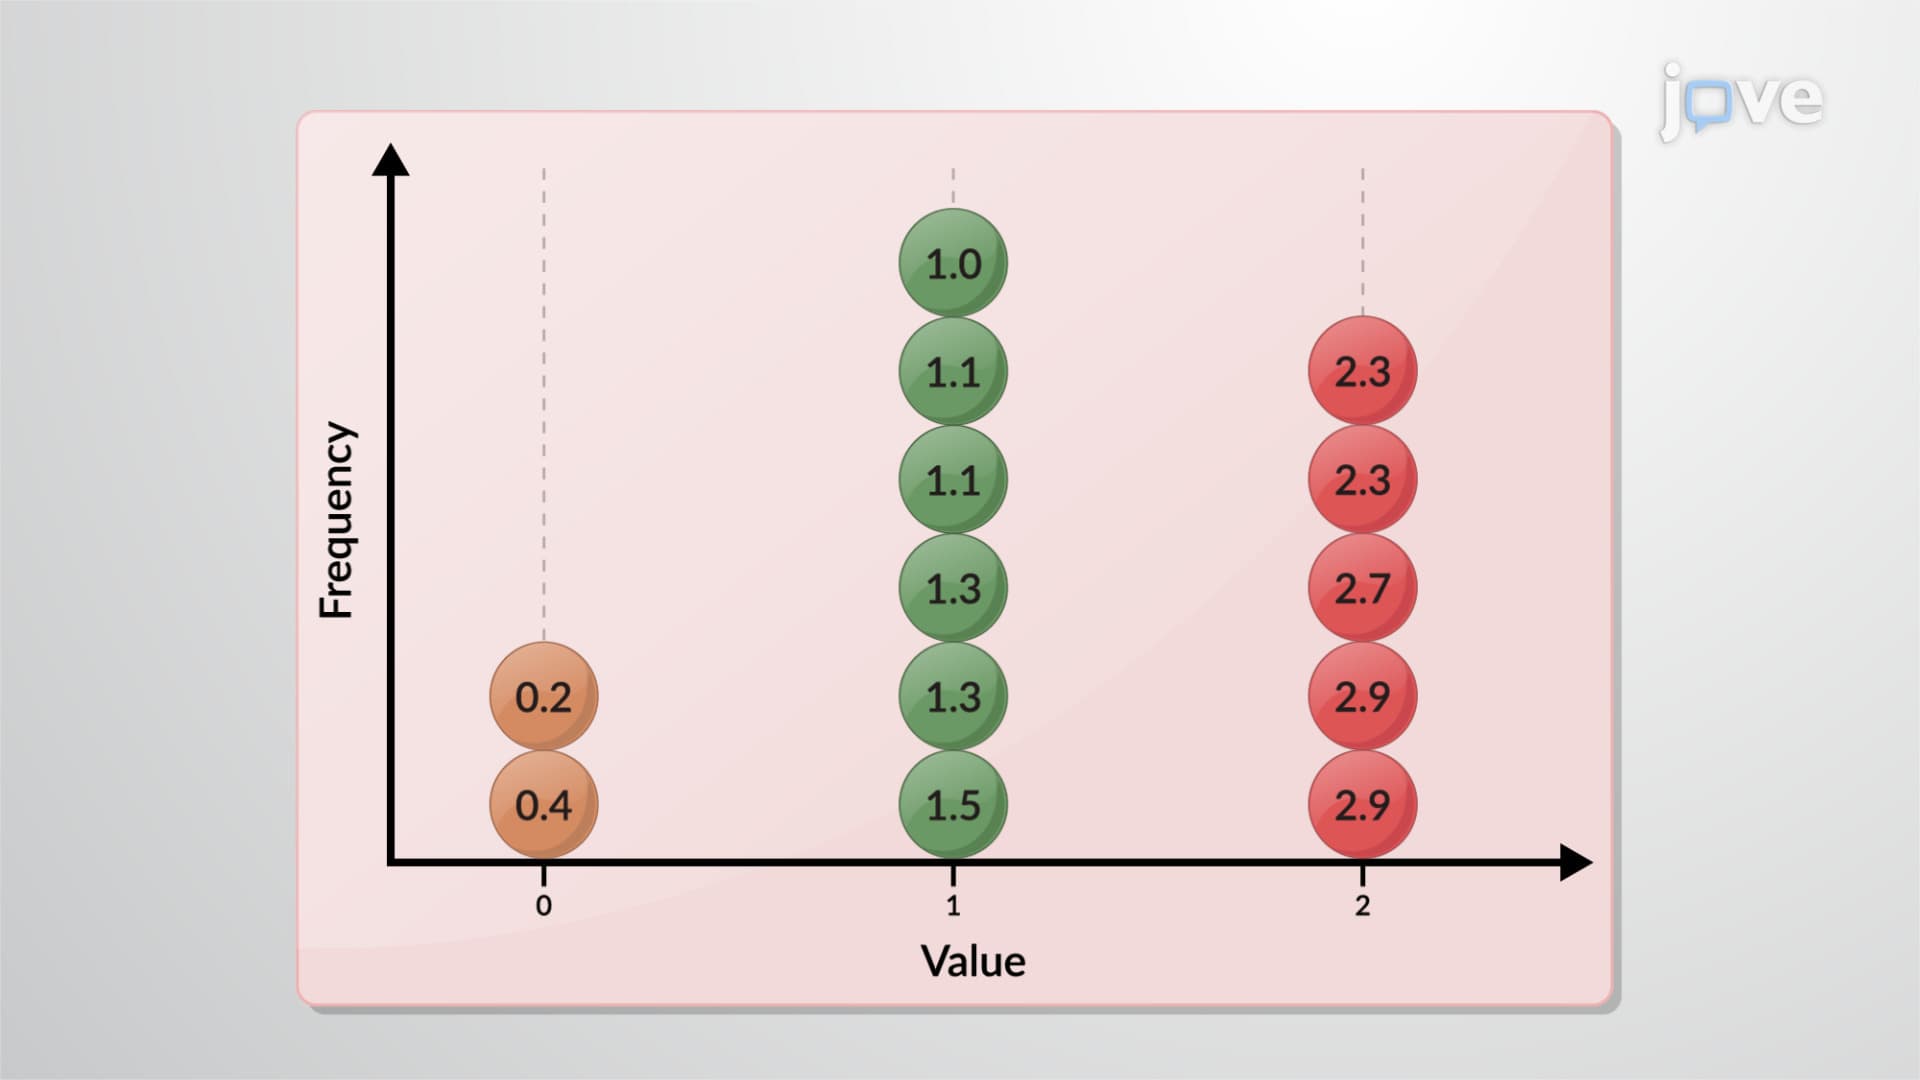
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
116