预CM:用于语义细分的基于填充的旋转等值卷积模式
相关实验视频
Updated: May 14, 2025

04:48
Swin-PSAxialNet: An Efficient Multi-Organ Segmentation Technique
Published on: July 5, 2024
322

概括
本研究引入了一种新的旋转等值卷积框架 (PreCM),以提高随意成像角度的计算机视觉任务中的语义细分精度. 这种新方法增强了特征提取,从而在各种数据集中显著改善了跨欧盟交叉点 (IOU).
科学领域:
- 计算机视觉 计算机视觉
- 图像处理 图像处理
- 深度学习 (Deep Learning) 是一种深度学习.
背景情况:
- 语义细分在计算机视觉中至关重要,但当前的深度学习模型在随意的成像角度上扎.
- 在卷积神经网络 (CNN) 中缺乏旋转等差,阻碍了从具有不同方向的对象中有效地提取特征.
研究的目的:
- 开发一个通用卷积组框架,将旋转等差纳入语义细分的框架.
- 引入一种新的基于填充的旋转等值卷积模式 (PreCM),作为现有卷积的多功能替代组件.
主要方法:
- 构建了一个通用卷积组框架,以增强对方向信息的利用.
- 设计了一个基于填充的旋转等值卷积模式 (PreCM),与多尺度图像和各种卷积类型兼容.
- 提出了一个新的评估指标,旋转差 (RD),以评估图像旋转的影响.
主要成果:
- 基于PreCM的语义细分网络显示,与随机角度旋转下的原始版本相比,在欧盟 (IOU) 上的平均交叉点 (IOU) 改进了4.53%至10.63%.
- 平均旋转差 (RD) 值在实验中下降,表明对方位变化的强化稳定性.
- 在水体卫星图像,DRIVE和Floodnet数据集上进行了实验,将PreCM集成到六个现有的语义细分网络中.
结论:
- 拟议的PreCM框架有效地配备了具有旋转等差的语义细分网络,大大提高了任意成像角度的数据集的性能.
- 作为标准卷曲的灵活有效替代品,PreCM可以增强特征提取和模型强度.
- 这项研究为处理语义细分中的定向变化提供了一种新的解决方案,在遥感和医学成像中具有潜在的应用.

相关概念视频
 01:20
Convolution Properties I
120
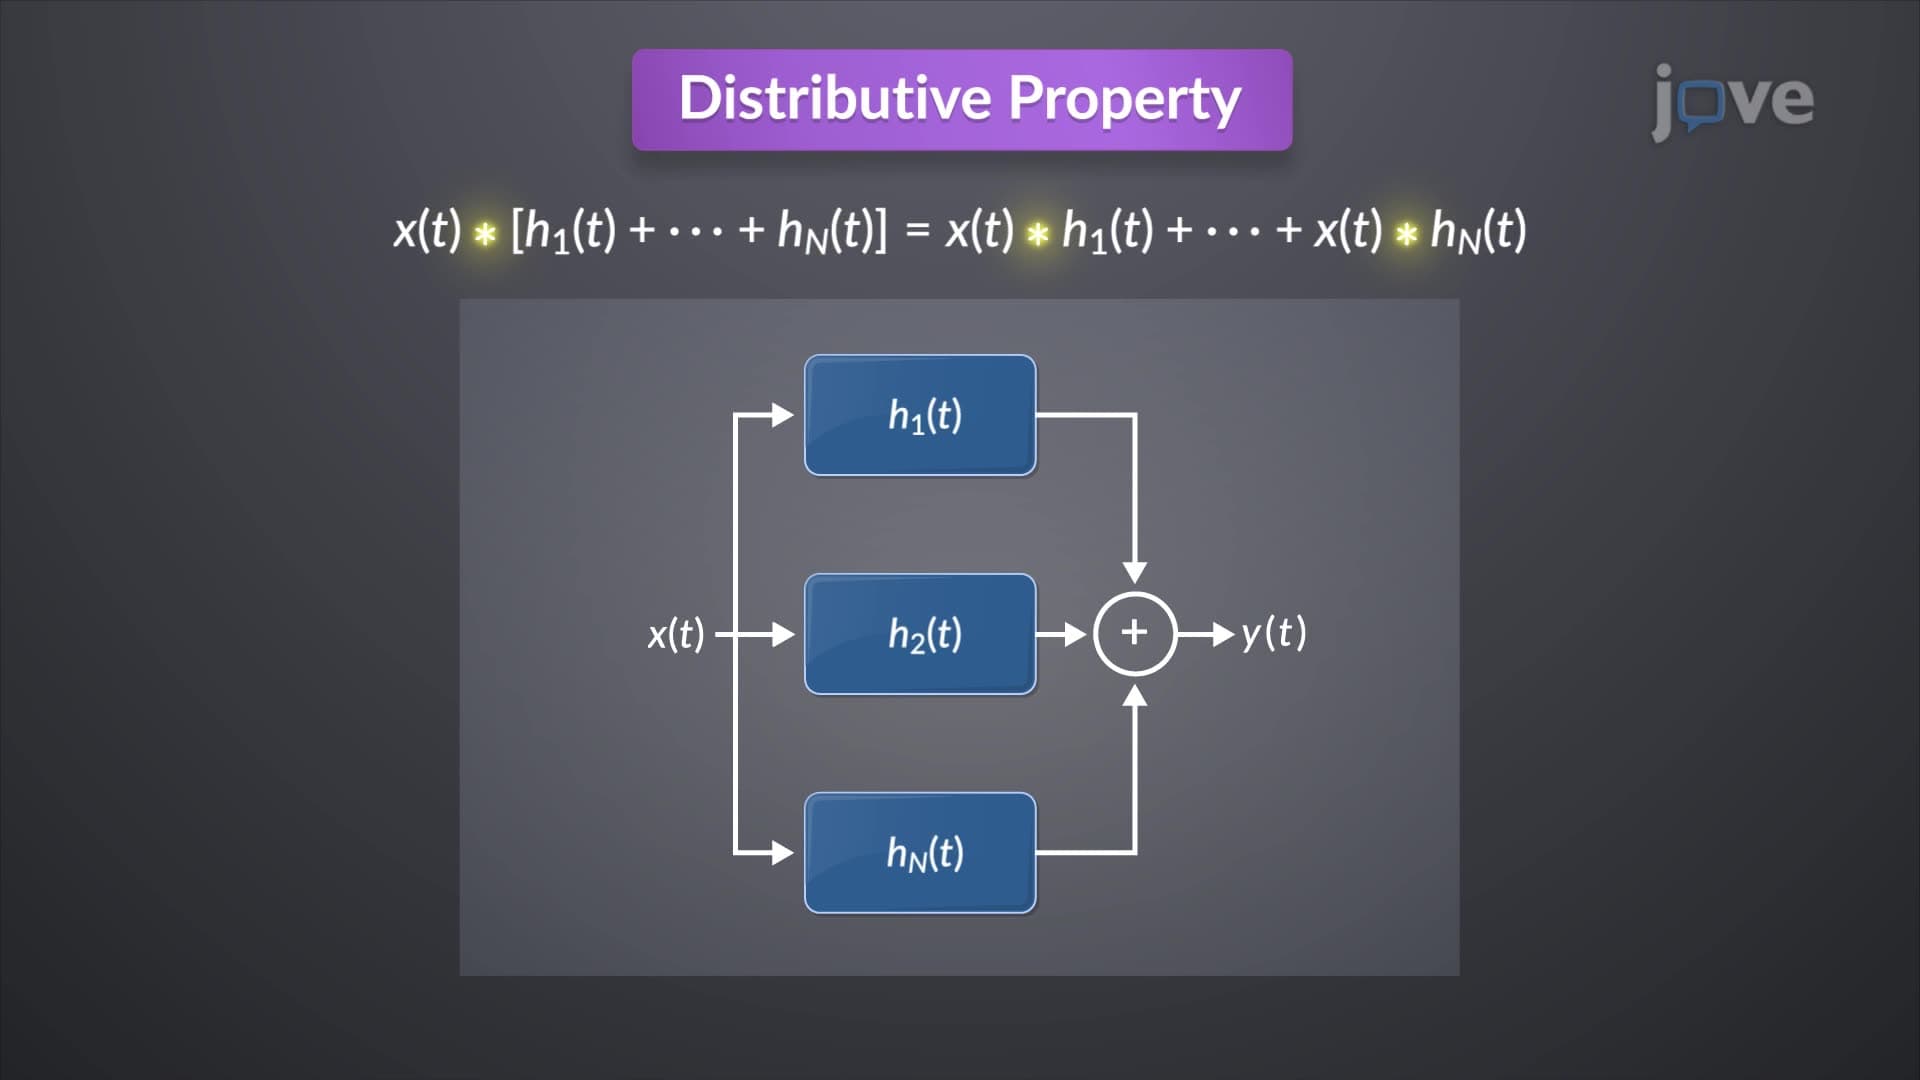
Convolution computations can be simplified by utilizing their inherent properties.
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
120
 01:17
Convolution Properties II
147
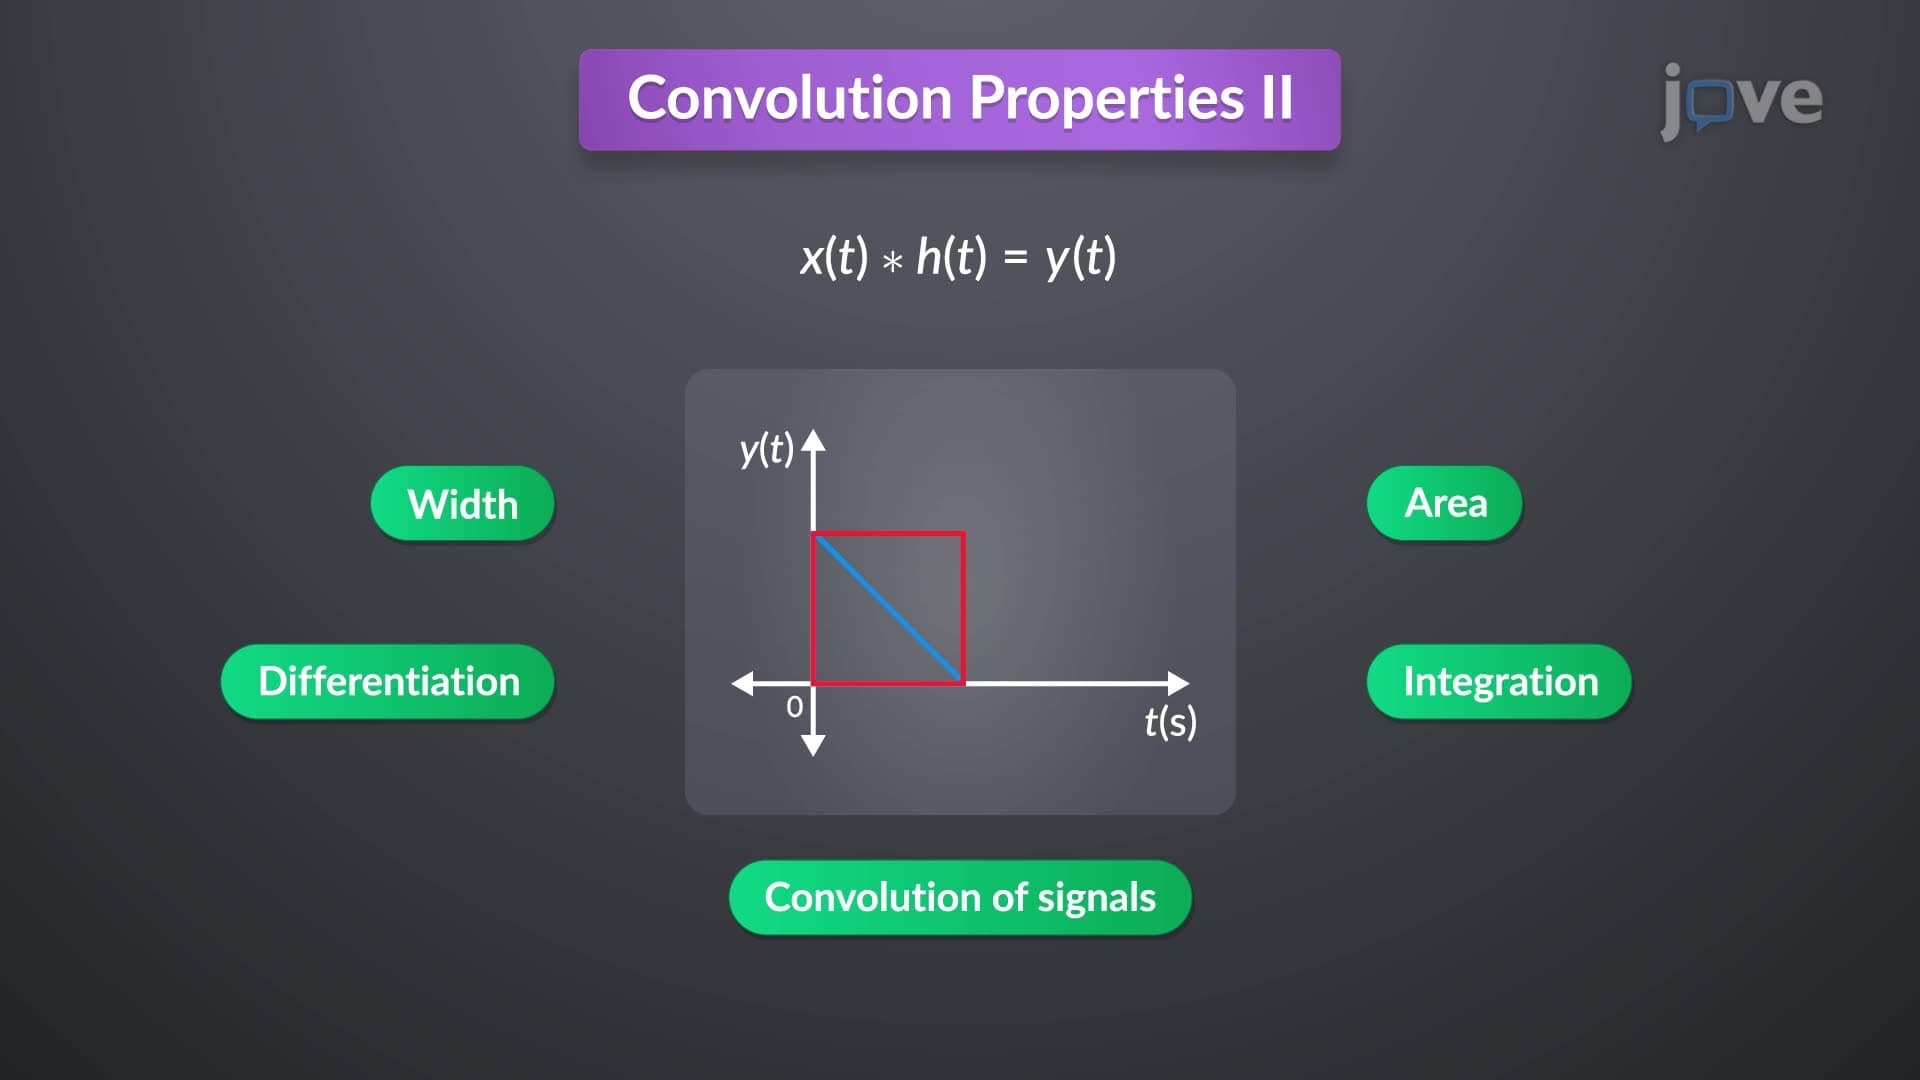
The important convolution properties include width, area, differentiation, and integration properties.
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
147
 01:24
Convolution: Math, Graphics, and Discrete Signals
210
In any LTI (Linear Time-Invariant) system, the convolution of two signals is denoted using a convolution operator, assuming all initial conditions are zero. The convolution integral can be divided into two parts: the zero-input or natural response and the zero-state or forced response, with t0 indicating the initial time.
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
210
 01:20
Deconvolution
116
Deconvolution, also known as inverse filtering, is the process of extracting the impulse response from known input and output signals. This technique is vital in scenarios where the system's characteristics are unknown, and they must be inferred from the observable signals.
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
116
 01:15
Depth Perception and Spatial Vision
479
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
479
 01:20
Vector Operations
1.1K
Vectors are physical quantities that have both magnitude and direction. The vector operations include addition, subtraction, and scalar multiplication.
A vector multiplied by a scalar value is called scalar multiplication. The result obtained is a new vector with a different magnitude. If the scalar is positive, the direction of the vector remains the same, but if it is negative, the direction of the vector is reversed. For example, the product of the mass and velocity yields the momentum.
A vector multiplied by a scalar value is called scalar multiplication. The result obtained is a new vector with a different magnitude. If the scalar is positive, the direction of the vector remains the same, but if it is negative, the direction of the vector is reversed. For example, the product of the mass and velocity yields the momentum.
1.1K