

用专有和公开可用的数据集进行目标预测的数据探索
Aljoša Smajić1, Thomas Steger-Hartmann2, Gerhard F Ecker1
1Department of Pharmaceutical Sciences, University of Vienna, Vienna 1090, Austria.
Chemical research in toxicology
|April 20, 2025

概括
将各种生物活性数据用于机器学习 (ML) 模型的组合是常见的,但数据源差异显著影响预测准确性. 在一个数据源上训练的模型由于化学空间变化而在另一个数据源上表现不佳.
科学领域:
- 计算化学是一种计算化学.
- 药物发现 药物发现
- 在药理学中的机器学习.
背景情况:
- 用于生物活性预测的机器学习 (ML) 模型经常整合来自各种测试来源的数据.
- 数据领域和来源的差异可能导致生物活性值的高差异和独特的化学空间覆盖.
- 培训数据的来源显著影响了ML预测模型的有效性和适用性领域.
研究的目的:
- 研究专有制药数据 (拜耳公司) 与公开数据 (ChEMBL) 的化学空间和活性/无活性化合物分布.
- 评估这些数据源对ML分类模型性能的影响.
- 探索创建强大的混合培训数据集的策略.
主要方法:
- 应用了两个描述器集和各种ML算法来分析Bayer AG和ChEMBL数据集.
- 使用马修斯相关系数 (MCC) 值评估预测性能.
- 评估的化学空间重叠使用最接近邻居的平均Tanimoto相似性.
- 研究了混合训练数据策略,包括测试格式和Tanimoto相似性.
主要成果:
- 在Bayer AG和ChEMBL数据集之间观察到化学空间的实质差异.
- 在一个数据集上训练的模型在另一个数据集上测试时显示出低于最佳的性能 (MCC值在 -0.34 和 0.37 之间).
- 低平均坦尼莫托相似度 (≤0.3) 表示许多目标在化学空间的重叠有限.
- 评估化学空间重叠的方法无法可靠地预测跨数据集的模型性能.
结论:
- 数据源异质性在生物活性预测中显著影响ML模型的概括性.
- 专有和公共数据集往往代表着不同的化学空间,限制了跨数据集模型的适用性.
- 开发有效的策略来整合不同的数据源,可能使用测试信息,对于提高模型稳定性至关重要.
更多相关视频
 07:41
Performing Data Mining And Integrative Analysis Of Biomarker in Breast Cancer Using Multiple Publicly Accessible Databases
Published on: May 17, 2019
8.8K
 10:21
Author Spotlight: Streamlining Protein Target Prediction and Validation via Molecular Docking and CETSA
Published on: February 23, 2024
2.3K
相关概念视频
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:07
End Point Prediction: Gran Plot
229
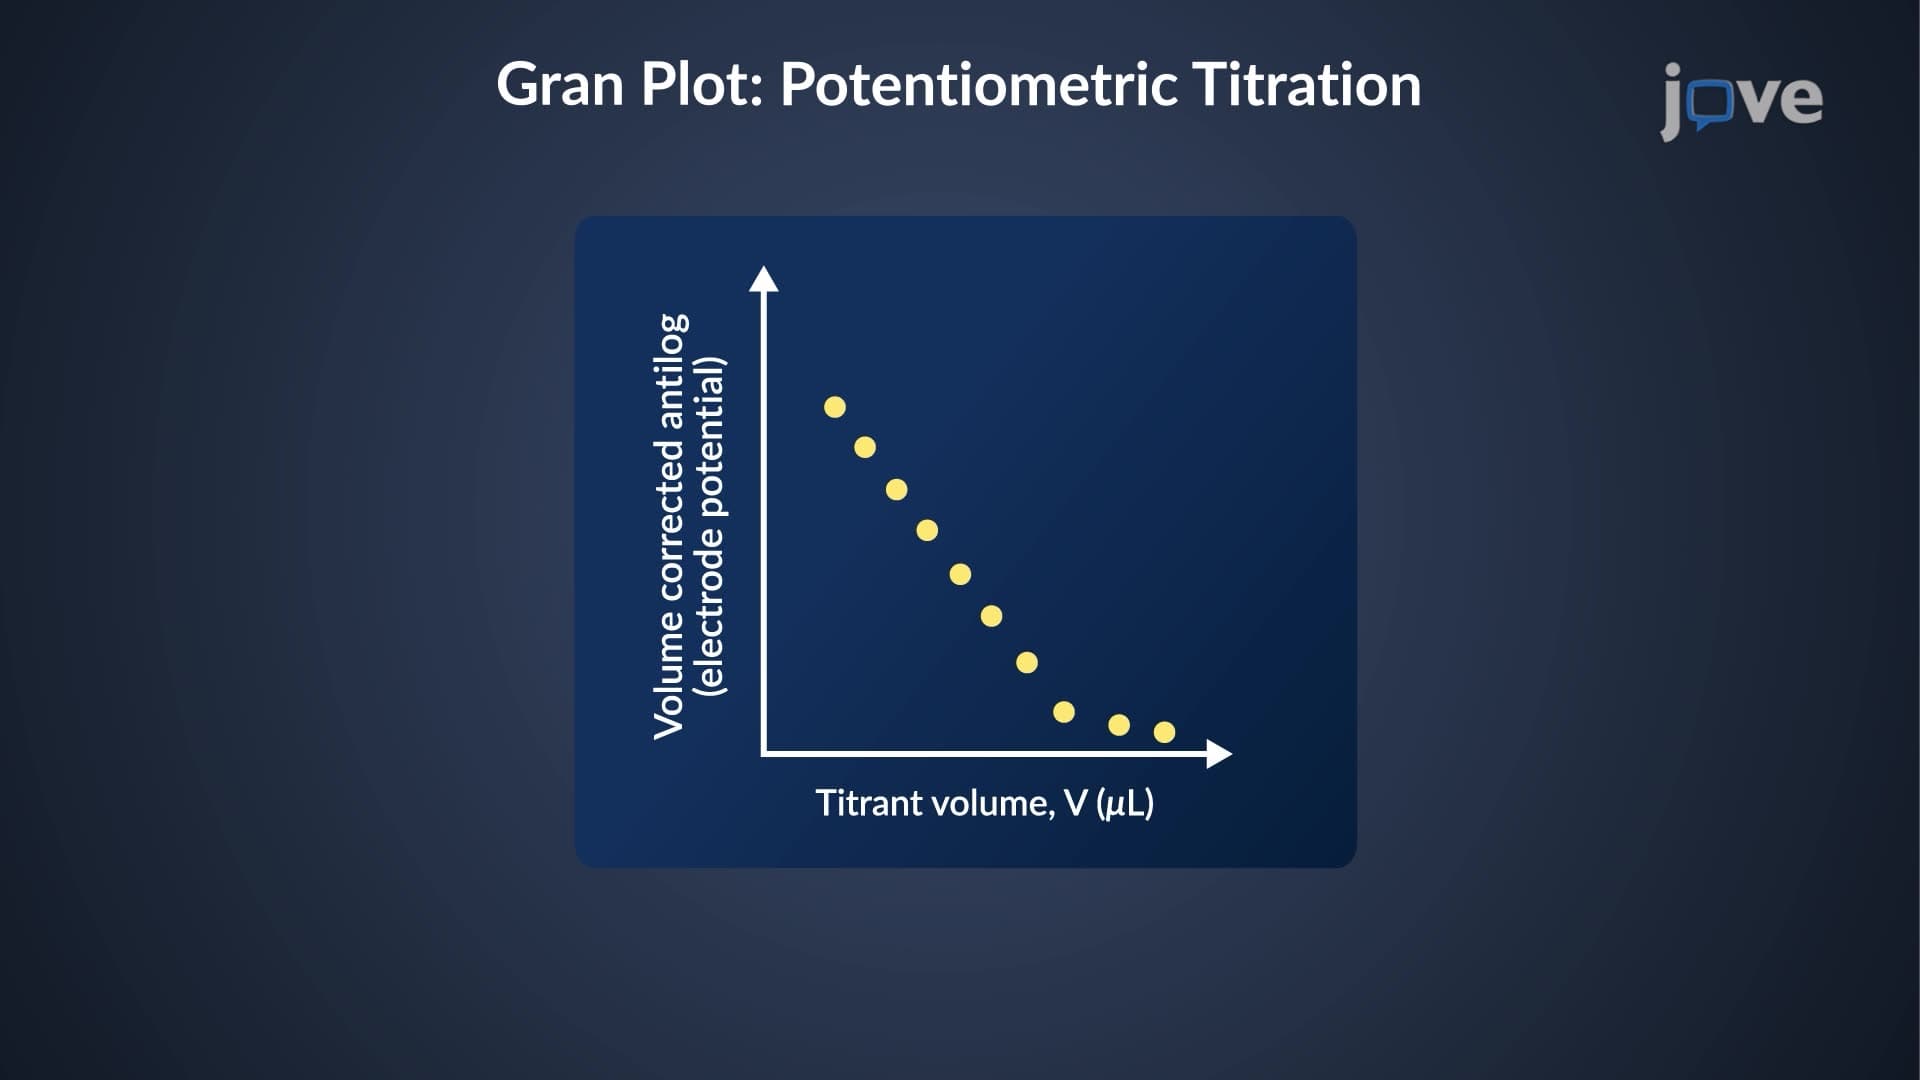
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
229
 01:12
Statistical Software for Data Analysis and Clinical Trials
477
Statistical software is pivotal in data analysis and clinical trials by providing tools to analyze data, draw conclusions, and make predictions. These software packages range from simple data management applications to complex analytical platforms, supporting various statistical tests, models, and simulation techniques. Their significance lies in their ability to handle vast amounts of data with precision and efficiency, enabling researchers to validate hypotheses, identify trends, and make...
477