
基于随机决策规则的生成对抗网络的新范式
Sehwan Kim1, Qifan Song1, Faming Liang1
1Department of Statistics, Purdue University, West Lafayette, IN 47907.
Statistica Sinica
|April 25, 2025

概括
本研究引入了一种新的生成对抗网络 (GAN) 公式,以解决模式崩,增强数据多样性. 拟议的方法使用随机决策规则和经验贝叶斯方法来实现稳定的训练和接近纳什平衡.
科学领域:
- 机器学习 机器学习
- 人工智能的人工智能
- 统计 统计 统计 统计
背景情况:
- 生成对抗网络 (GAN) 是强大的培训生成模型,但遭受模式崩,限制生成的数据多样性.
- 在GAN中,模式崩导致生成样本缺乏多样性,阻碍了它们的应用.
- 现有的GAN培训方法在实现稳定的融合和多样化的输出方面面临挑战.
研究的目的:
- 确定GAN中模式崩的根本原因.
- 通过使用随机决策规则,提出一种新的GAN配方来解决模式崩.
- 开发一种基于实证贝叶斯原理的培训方法,以提高GAN性能.
主要方法:
- 引入了一种新的GAN配方与随机决策规则,导致分辨器收和生成器收到纳什平衡分布.
- 提出了一种经验性的贝叶斯式训练方法,将区分器视为超参数.
- 利用一个随机梯度马尔科夫链蒙特卡洛 (MCMC) 算法来模拟生成器和随机梯度下降来进行区分器更新.
主要成果:
- 建立了拟议方法与纳什平衡的理论趋同.
- 证明了该方法在解决模式崩和改善生成数据多样性的有效性.
- 成功地将该方法应用于图像生成,非参数聚类和非参数条件独立性测试.
结论:
- 拟议的GAN配方和培训方法有效地克服了模式崩.
- 经验贝叶斯方法与MCMC和SGD提供了一个稳定和融合的培训策略.
- 该方法显示出超出图像生成范围的广泛应用,包括统计任务.

相关概念视频
 01:13
Randomized Experiments
6.6K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.6K
 01:34
Woodward–Hoffmann Selection Rules and Microscopic Reversibility
2.9K
Electrocyclic reactions, cycloadditions, and sigmatropic rearrangements are concerted pericyclic reactions that proceed via a cyclic transition state. These reactions are stereospecific and regioselective. The stereochemistry of the products depends on the symmetry characteristics of the interacting orbitals and the reaction conditions. Accordingly, pericyclic reactions are classified as either symmetry-allowed or symmetry-forbidden. Woodward and Hoffmann presented the selection criteria for...
2.9K
 01:14
Decision Making: Traditional Method
3.9K
The process of hypothesis testing based on the traditional method includes calculating the critical value, testing the value of the test statistic using the sample data, and interpreting these values.
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
3.9K
 01:09
Decision Making: P-value Method
5.2K
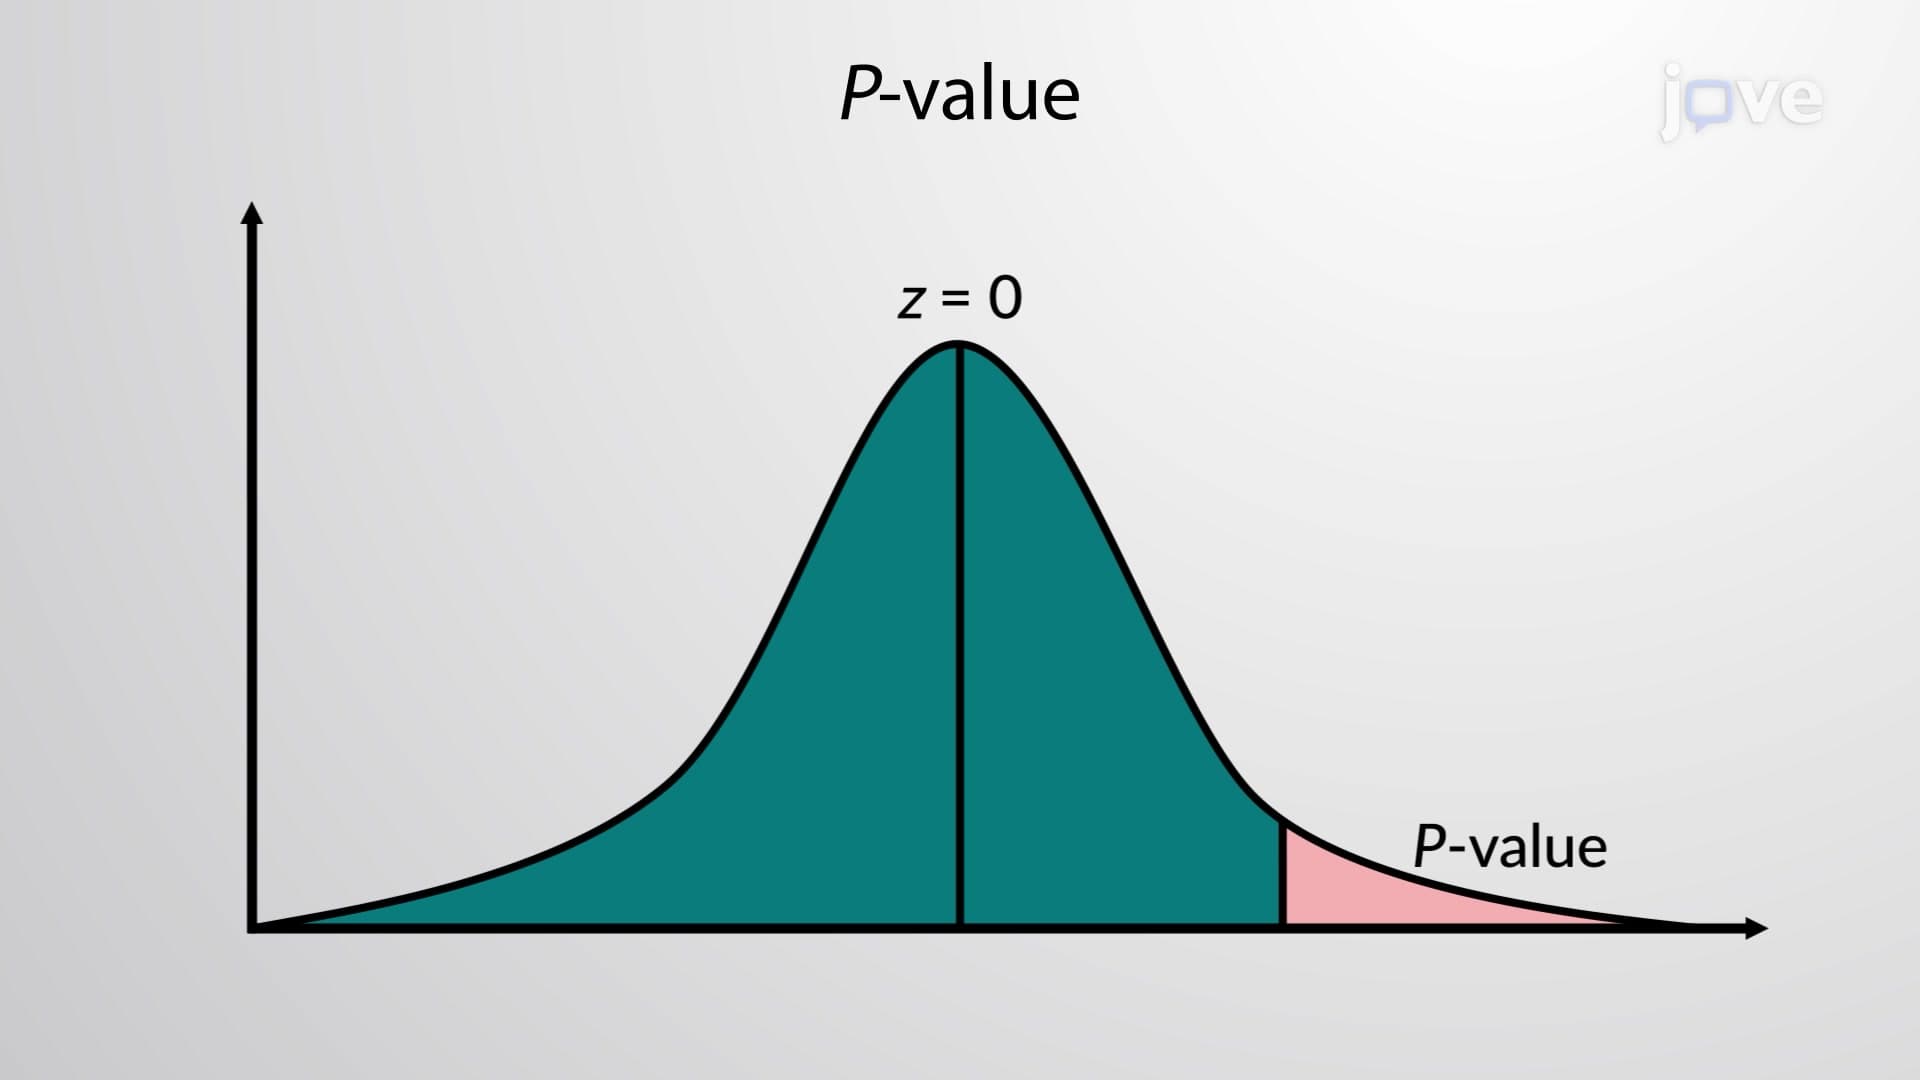
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.2K
 01:09
Random Variables
11.3K
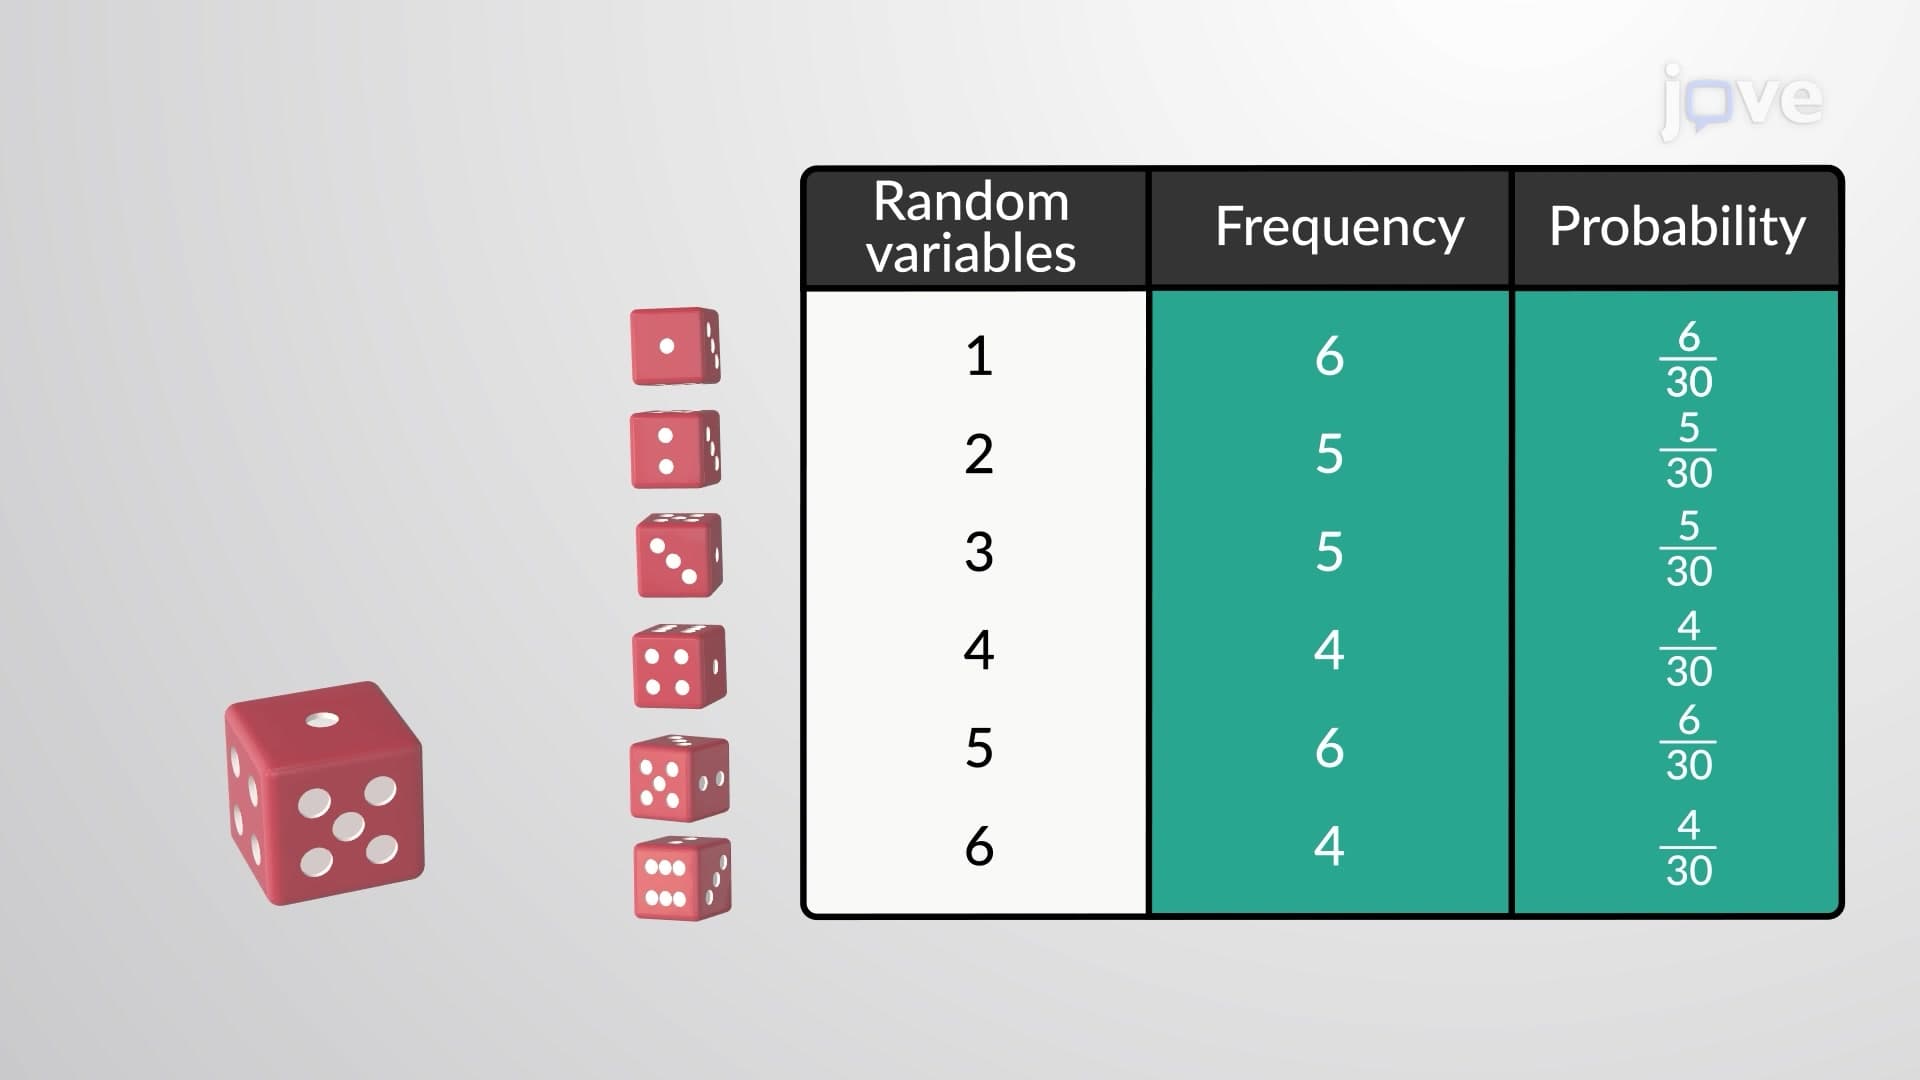
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
11.3K
 00:59
Propagation of Uncertainty from Random Error
533
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
533