
基于不同曲折调整算法的调整暴露水平的分析及其在评估噪音引起的听力损失方面的性能比较
Hengjiang Liu1, Meibian Zhang2, Xin Sun2
1Research Center for Scientific Data Hub, Zhejiang Laboratory, Hangzhou, China.
Ear and hearing
|May 8, 2025

概括
曲解调整的噪声暴露水平的几何平均和细分调整方案更准确地预测噪声引起的听力损失. 这些方法在工业环境中复杂的噪声评估中改进了算术平均值.
科学领域:
- 职业健康 职业健康 职业健康
- 声学 声学 在声学方面
- 听力学 听力学是指听力学.
背景情况:
- 库尔托斯对于评估复杂噪声引起的听力损失至关重要,它是使用第四个中心时刻和标准偏差计算的.
- 库尔托斯调整的噪声暴露水平提供了更准确的噪声引起的听力损失的预测.
- 有三种调整方案:算术平均,几何平均和细分调整.
研究的目的:
- 评估不同曲解调整方案对噪声暴露的实用性.
- 确定在工业环境中预测噪音引起的听力损失的最有效方法.
主要方法:
- 分析了来自中国4276名制造业工人的每日噪音记录.
- 使用60秒窗口和应用算术,几何和细分调整方案来计算kurtosis.
- 评估噪声引起的永久值转移 (NIPTS346) 并使用ISO 1999和Lempert模型比较预测和实际听力损失.
主要成果:
- 几何平均 (方案2) 和细分调整 (方案3) 与算术平均 (方案1) 相比,在预测听力损失方面表现相似且优越.
- 调整系数为几何平均值的6.5和细分调整的5.4.
- 几何平均和细分调整方案显著提高了听力损失预测的准确性.
结论:
- 使用几何平均值 (系数6.5) 或细分调整 (系数5.4) 调整Kurtosis的LAeq,8hr可以提高对噪声引起的听力损失的评估.
- 分段调整提供了灵活性,但需要进一步研究以减轻极端值的影响.
- 这些发现支持改善评估职业听力风险的方法.
相关概念视频
 01:24
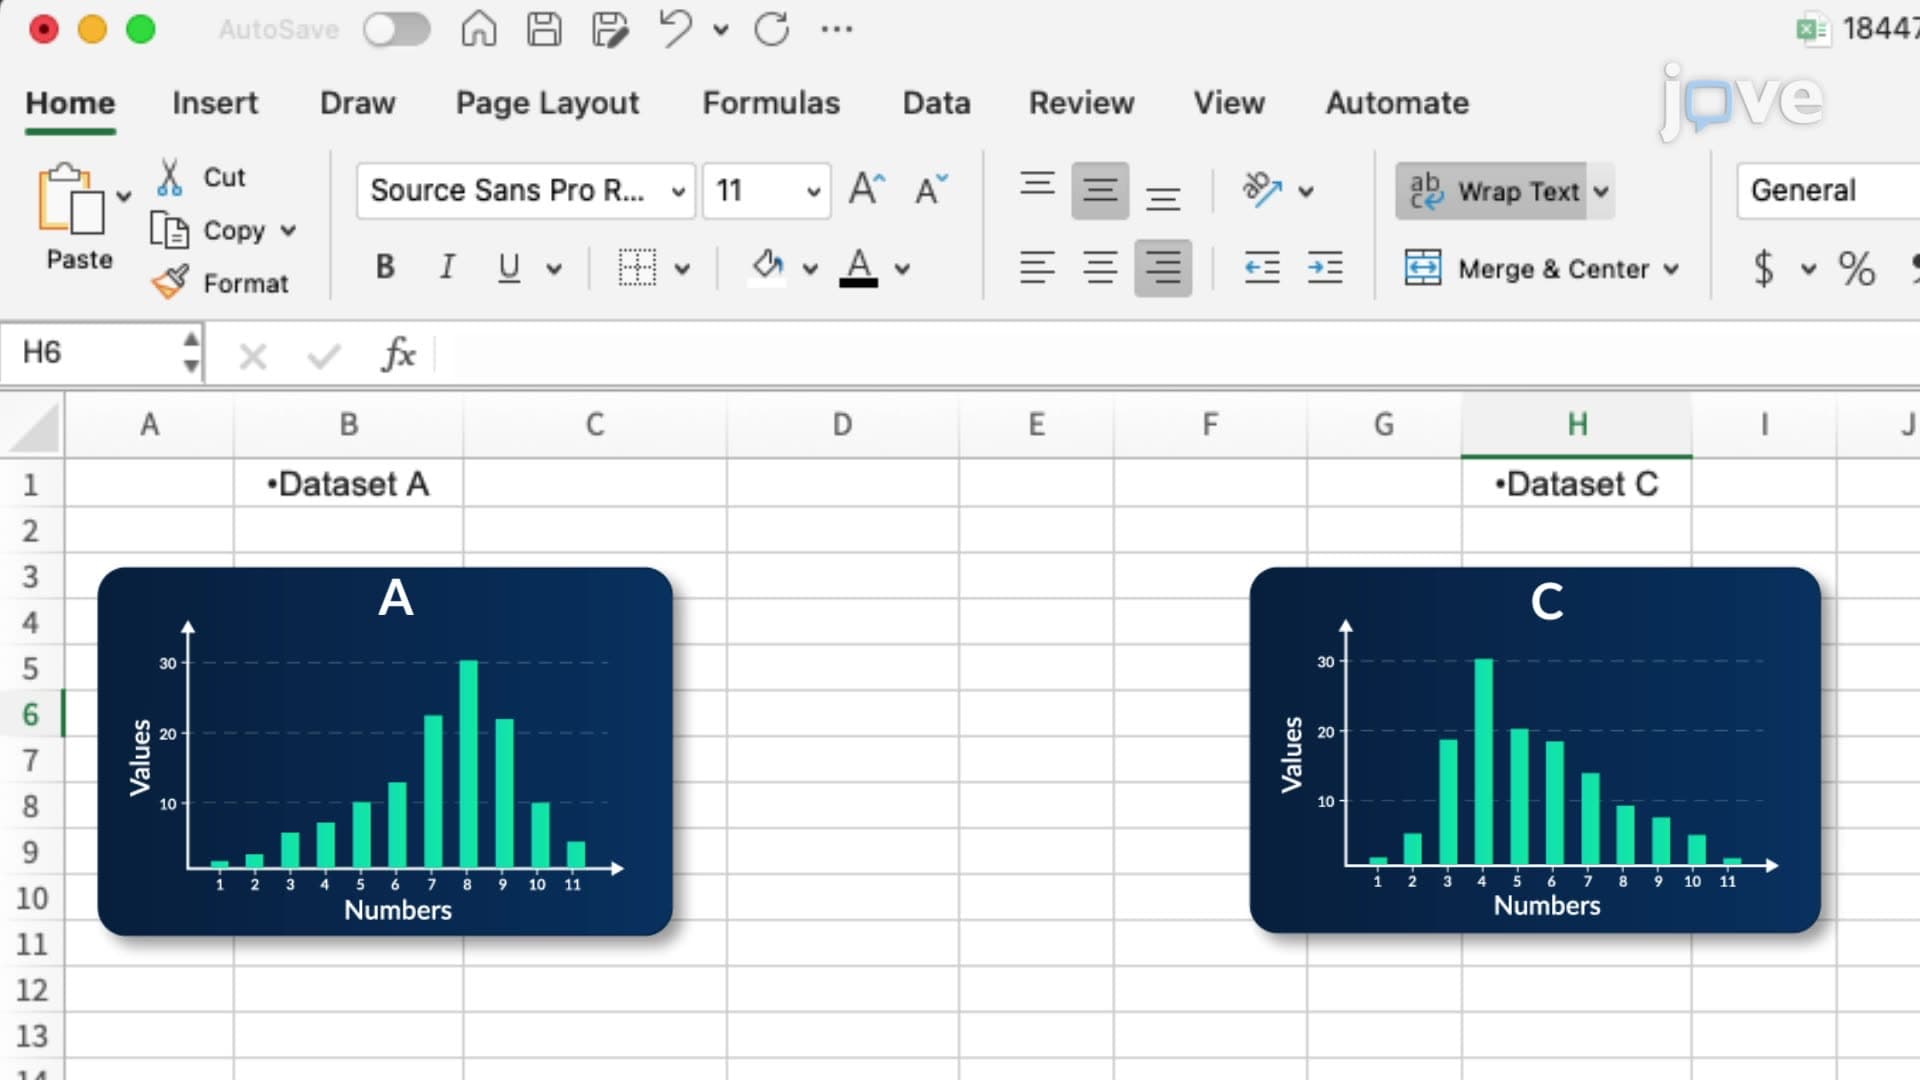
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
105
Central tendency refers to the central point or typical value of a dataset. It summarizes the data set with a single value that represents the center of its distribution. The three main measures of central tendency are:
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
105
 01:00
Detection of Gross Error: The Q Test
4.5K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
4.5K
 01:19
Kruskal-Wallis Test
488
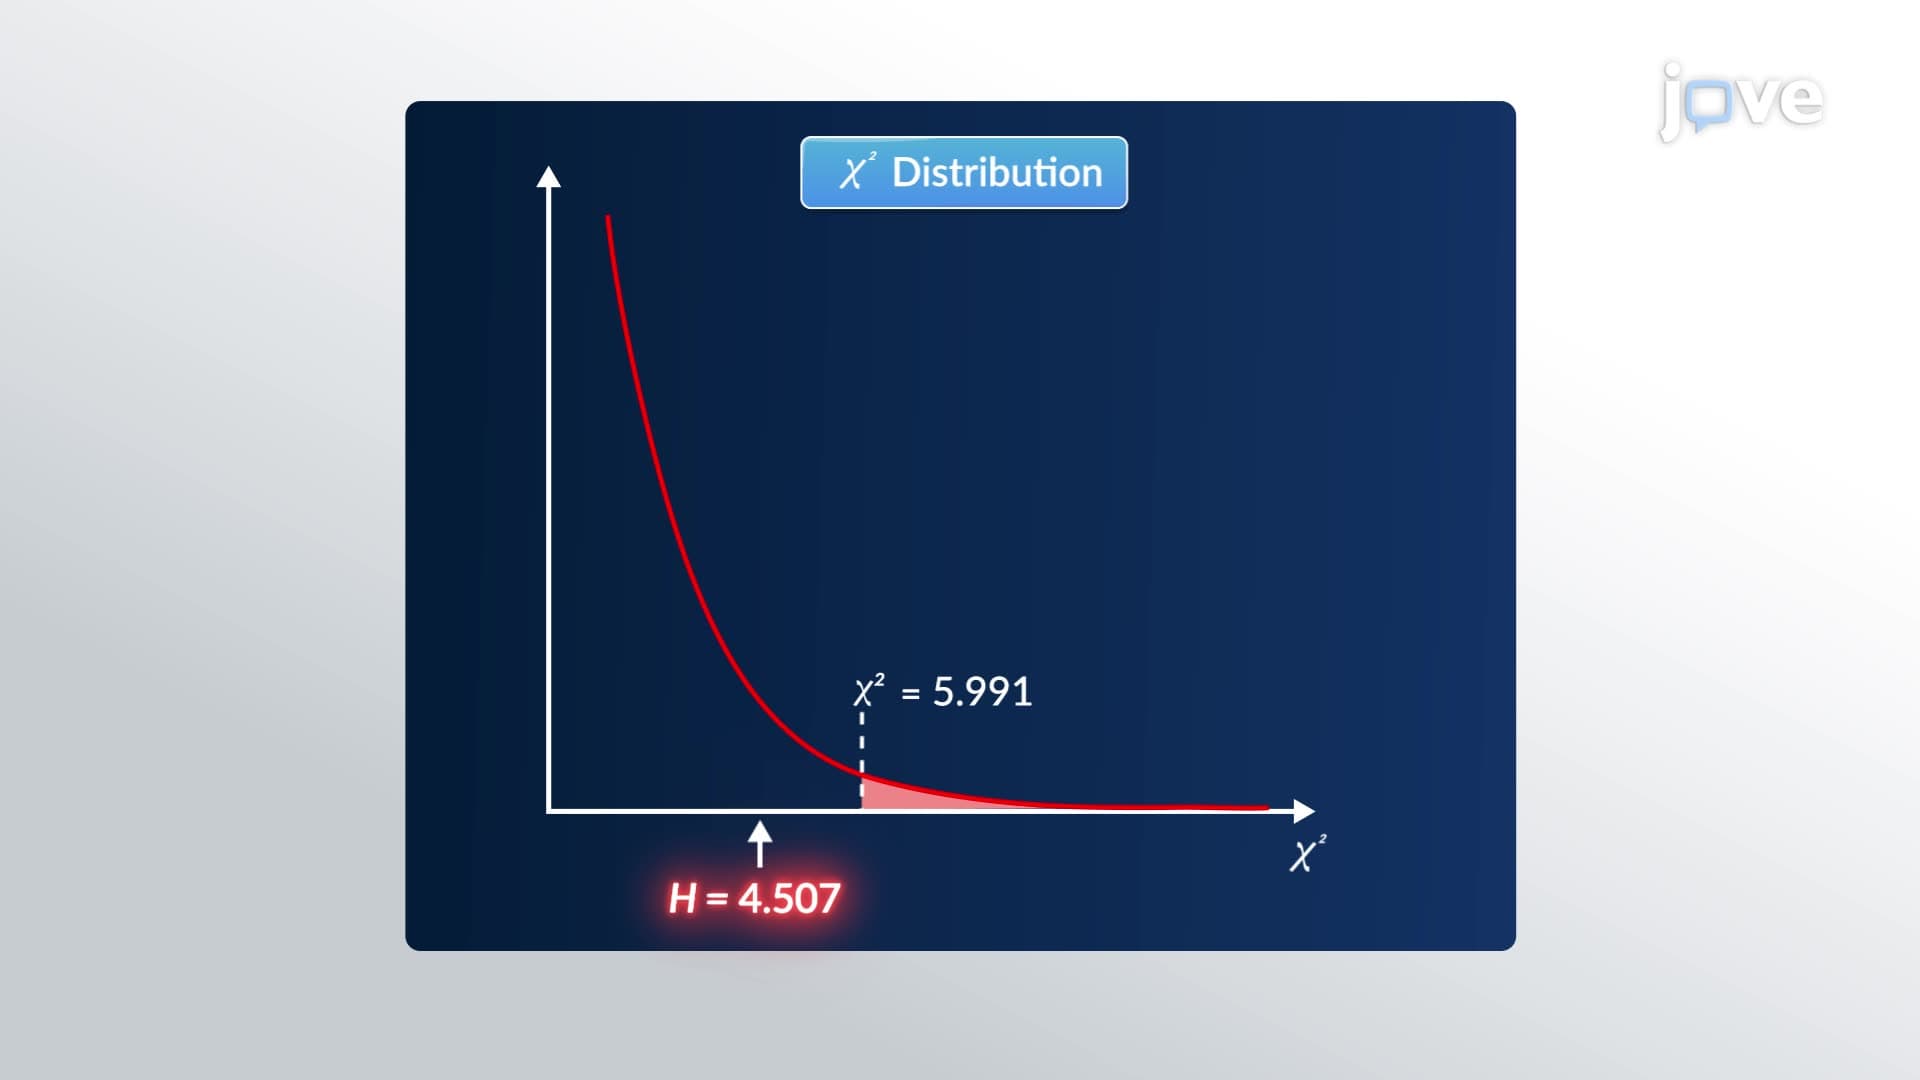
The Kruskal-Wallis test, also known as the Kruskal-Wallis H test, serves as a nonparametric alternative to the one-way ANOVA, offering a solution for analyzing the differences across three or more independent groups based on a single, ordinal-dependent variable. This statistical test is particularly valuable in scenarios where the data does not meet the normal distribution assumption required by its parametric counterparts. Kruskal-Wallis test is designed typically to handle ordinal data or...
488
 01:21
Friedman Two-way Analysis of Variance by Ranks
99
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
99
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:15
One-Way ANOVA: Unequal Sample Sizes
5.6K
One-way ANOVA can be performed on three or more samples of unequal sizes. However, calculations get complicated when sample sizes are not always the same. So, while performing ANOVA with unequal samples size, the following equation is used:
5.6K