LeFood-set:使用MT学习在医院预测剩余食物数据集水平的基线性能
Yuita Arum Sari1,2, Atsushi Nakazawa1, Yudi Arimba Wani3
1Graduate School of Interdisciplinary Science and Engineering in Health Systems, Okayama University, Kita-Ku, Okayama, Japan.
PloS one
|May 19, 2025

概括
这项研究引入了一种新的深度学习方法和LeFoodSet数据集,以准确估计患者的食物剩余,优于人类观察,以便在医疗保健中更好地监测饮食摄入量.
科学领域:
- 计算机科学 计算机科学
- 人工智能的人工智能
- 医疗保健技术 技术 医疗保健 技术
背景情况:
- 准确监测患者的饮食摄入量在医疗保健中至关重要.
- 目前估计剩余食物的方法耗时且容易产生偏见.
- 需要自动化,客观的方法来评估食物消费.
研究的目的:
- 开发一种高效的基于深度学习的方法来估计剩余的食物.
- 创建一个全面的数据集 (LeFoodSet) 用于食物剩余的分析.
- 评估人工智能模型与人类观测的性能.
主要方法:
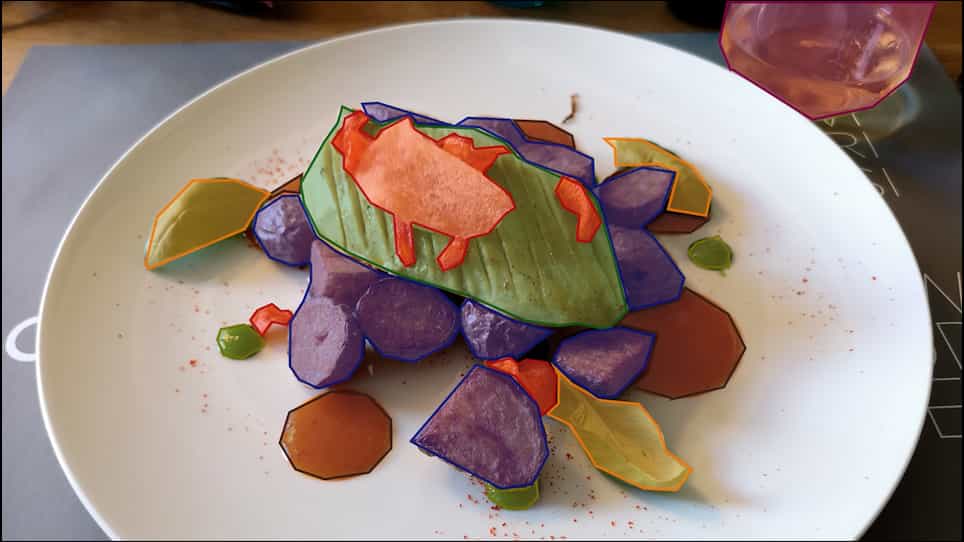
- 创建了LeFoodSet数据集,包含34个印度尼西亚食品类别的524个图像对.
- 开发多任务 (MT) 深度学习模型,同时预测剩余食品和食物类型.
- 使用了结合视觉特征提取和晚期融合方法的软参数共享.
- 与单任务 (ST) 和多任务 (MT) 模型进行比较,包括具有基础真相 (GT) 和任务间连接 (IC) 的变体.
主要成果:
- 人工智能模型,特别是MT和MT-IC,与人类观察相比,表现优越.
- 基于ResNet101的MT模型实现了剩余的平均误差 (MAE) 为0.0801,食品分类的准确率为90.44%.
- MT-IC模型实现了0.0817的MAE和92.56%的准确性,显示出强大的预测能力.
- LeFoodSet数据集是首个用于估计剩余数量和食物类型的数据集.
结论:
- 深度学习模型提供了一个有前途且准确的解决方案,用于估计剩余的食物.
- 开发的LeFoodSet数据集和AI方法可以显著改善医疗保健机构的饮食摄入量监测.
- 这项技术在医疗和护理领域有潜在的应用,提高了患者护理和运营效率.
相关概念视频
 00:56
Nominal Level of Measurement
27.6K
The way a set of data is measured is called its level of measurement. Correct statistical procedures depend on a researcher being familiar with levels of measurement. Not every statistical operation can be used with every set of data. For analysis, data are classified into four levels of measurement—nominal, ordinal, interval, and ratio.
The data that cannot be measured but can be grouped into categories fall under the nominal level of measurement. Data that is measured using a nominal...
The data that cannot be measured but can be grouped into categories fall under the nominal level of measurement. Data that is measured using a nominal...
27.6K
 01:11
Residuals and Least-Squares Property
7.2K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.2K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.4K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.4K