

一个单元级的一次膨胀β模型用于小区域预测安全带使用率
1Department of Statistics, Iowa State University, Ames, IA, USA.
Journal of applied statistics
|May 30, 2025

概括
这项研究引入了一种新的统计模型,用于估计爱荷华州县等小地理区域的安全带使用率. 该模型在处理有限数据时提高了准确性,为公共安全行为提供了更好的洞察力.
科学领域:
- 统计 统计 统计 统计
- 公共卫生 公共卫生
- 调查方法 调查方法
背景情况:
- 小面积估计对于在样本规模有限的地区提供可靠的统计数据至关重要.
- 准确估计安全带使用率对于公共卫生和安全倡议至关重要.
- 现有的方法对于像县这样的小地理单位可能缺乏精度.
研究的目的:
- 开发和评估小面积估计的单元级一次膨胀β模型.
- 为了估计特别针对爱荷华州各县的安全带使用率.
- 为了比较建议的频率主义和贝叶斯模型的性能与更简单的替代方案.
主要方法:
- 开发一个单元级的一次膨胀β模型.
- 为模型实施频率主义和贝叶斯主义方法.
- 模拟研究是用更简单的方法来比较拟议的预测因素.
- 将模型应用于爱荷华州安全带使用调查数据.
主要成果:
- 拟议的单元级一次膨胀β模型为小面积估计提供了强大的框架.
- 贝叶斯式和频率式实现都显示了提高安全带使用率估计准确度的潜力.
- 模拟结果表明,与更简单的替代方案相比,建议方法的有效性更高.
结论:
- 开发的单膨胀β模型适用于小面积估计,特别是分析边界比例,如安全带使用.
- 该研究成功地应用并验证了使用真实世界调查数据的模型的频率主义和贝叶斯版本.
- 这些发现支持使用这些先进的统计方法来提高小区域的公共安全估计.
相关概念视频
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
89
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
89
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
639
Parametric survival analysis models survival data by assuming a specific probability distribution for the time until an event occurs. The Weibull and exponential distributions are two of the most commonly used methods in this context, due to their versatility and relatively straightforward application.
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
639
 01:16
Hypothesis Test for Test of Independence
3.8K
The test of independence is a chi-square-based test used to determine whether two variables or factors are independent or dependent. This hypothesis test is used to examine the independence of the variables. One can construct two qualitative survey questions or experiments based on the variables in a contingency table. The goal is to see if the two variables are unrelated (independent) or related (dependent). The null and alternative hypotheses for this test are:
H0: The two variables (factors)...
H0: The two variables (factors)...
3.8K
 01:08
Determination of Expected Frequency
2.3K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.3K
 01:21
Introduction to Test of Independence
2.5K
In statistics, the term independence means that one can directly obtain the probability of any event involving both variables by multiplying their individual probabilities. Tests of independence are chi-square tests involving the use of a contingency table of observed (data) values.
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
2.5K
 01:17
Probability Histograms
12.2K
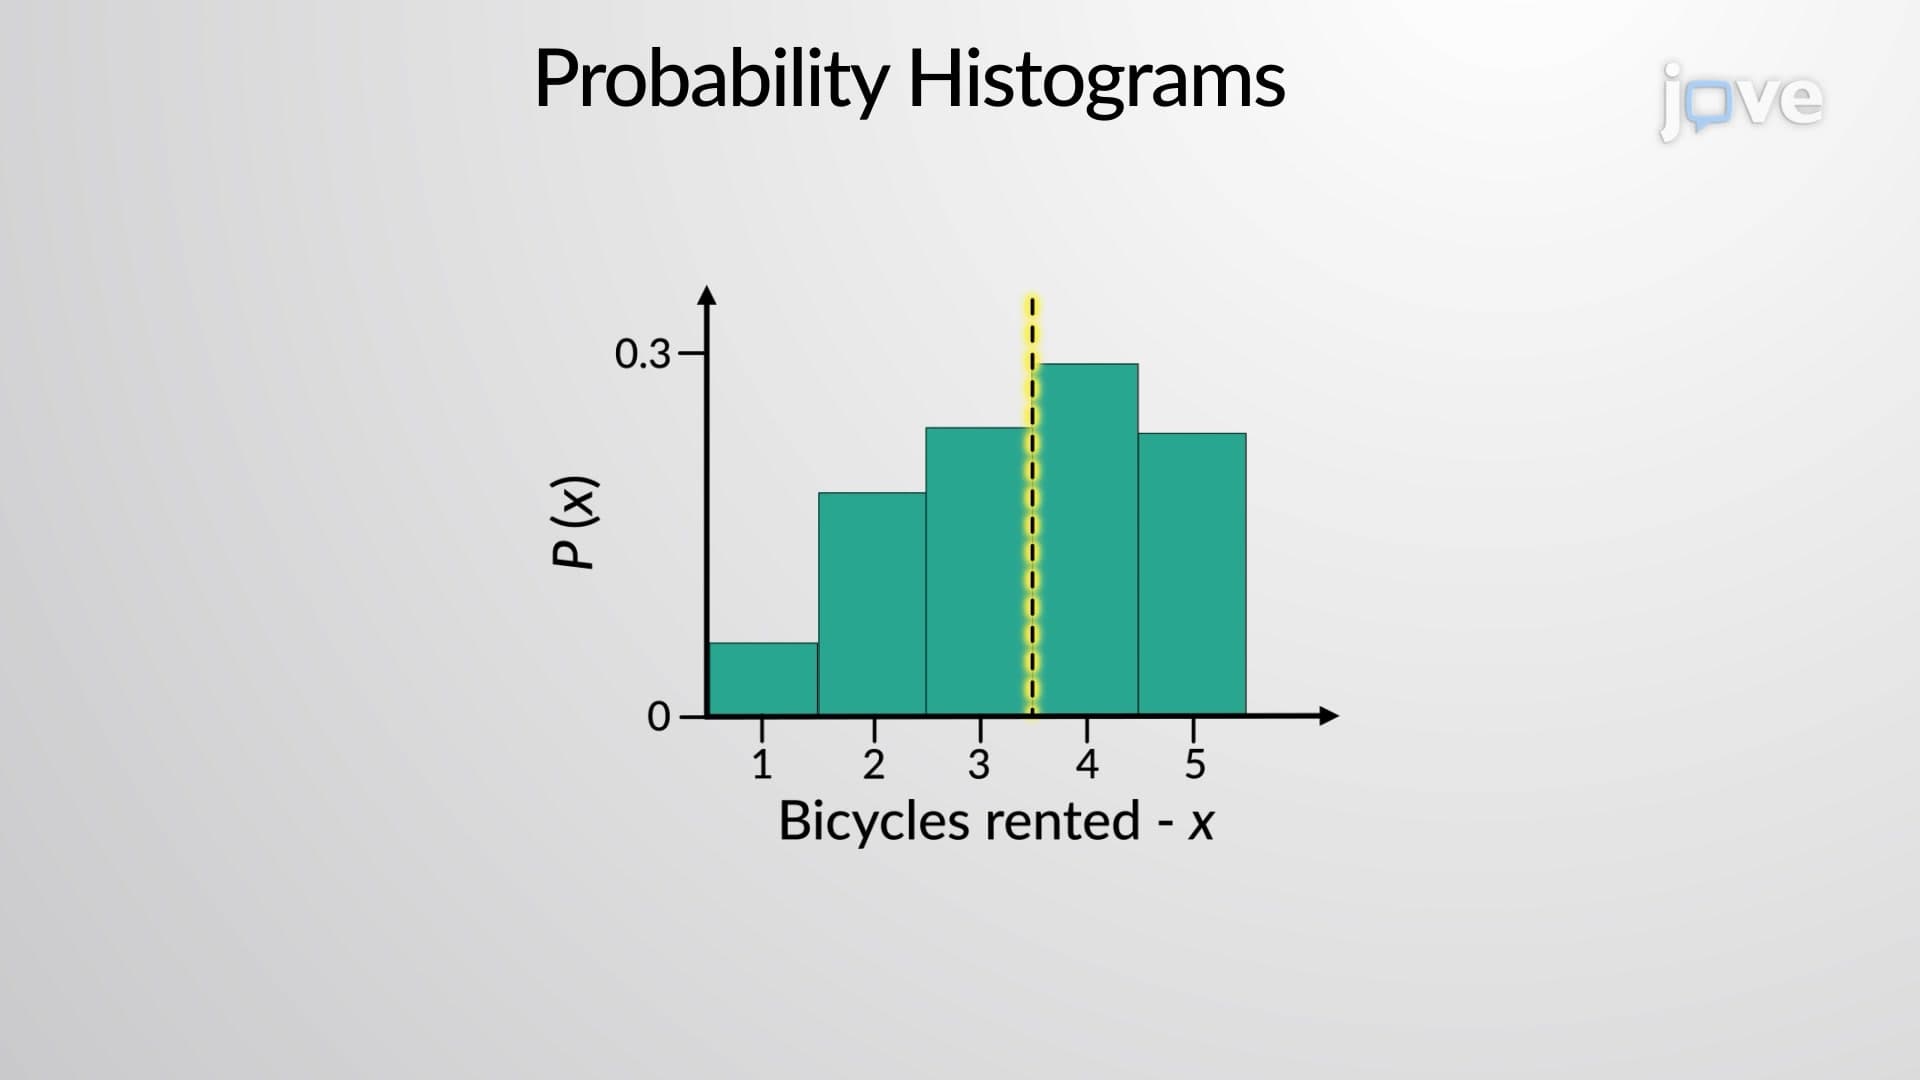
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
12.2K