学习对比的语义分解,以获得视觉接地
Jie Wu1, Chunlei Wu1, Yiwei Wei2
1Qingdao Institute of Software, College of Computer Science and Technology, China University of Petroleum (East China), Qingdao, China.

概括
本研究引入了一个新的对比语义分解网络用于视觉接地 (CSDVG). CSDVG通过更好地分离和结合视觉和语言特征来提高对象识别的准确性.
科学领域:
- 计算机视觉 计算机视觉
- 自然语言处理自然语言处理.
- 人工智能的人工智能
背景情况:
- 视觉接地将自然语言描述与图像区域联系起来.
- 目前的方法使用单独的编码器,可能缺少共享属性,并导致冗余的融合.
研究的目的:
- 为视觉接地 (CSDVG) 提出一个新的对比语义分解网络.
- 有效地分解共享的特定语义特征和模型跨模式特征,以改善视觉接地.
主要方法:
- 开发了CSDVG,用于共享特征的相关语义分支以及用于特定特征的独立语义分支.
- 引入了相关性驱动的损失函数,以平衡共享和特定特征学习.
主要成果:
- 与现有方法相比,CSDVG表现优越.
- 实验显示所有测试数据集的有效性.
结论:
- 拟议的CSDVG有效地分解和建模跨模式特征.
- 在视觉接地任务中,CSDVG解决了独立编码器和冗余融合的局限性.
更多相关视频
 06:33
Decomposing the Variance in Reading Comprehension to Reveal the Unique and Common Effects of Language and Decoding
Published on: October 11, 2018
6.9K
 09:27
Using Eye Movements Recorded in the Visual World Paradigm to Explore the Online Processing of Spoken Language
Published on: October 13, 2018
10.2K
相关概念视频
 01:21
Gestalt Principles of Perception
488
Gestalt principles provide a framework for understanding how humans perceive objects as unified wholes within their context. These principles are essential in explaining the cognitive processes that make sense of complex visual stimuli by organizing them into coherent groups. One fundamental principle is proximity, which posits that objects located close to each other are perceived as a collective group. For instance, when dots are positioned near one another, the visual system interprets them...
488
 01:26
Visual System
706
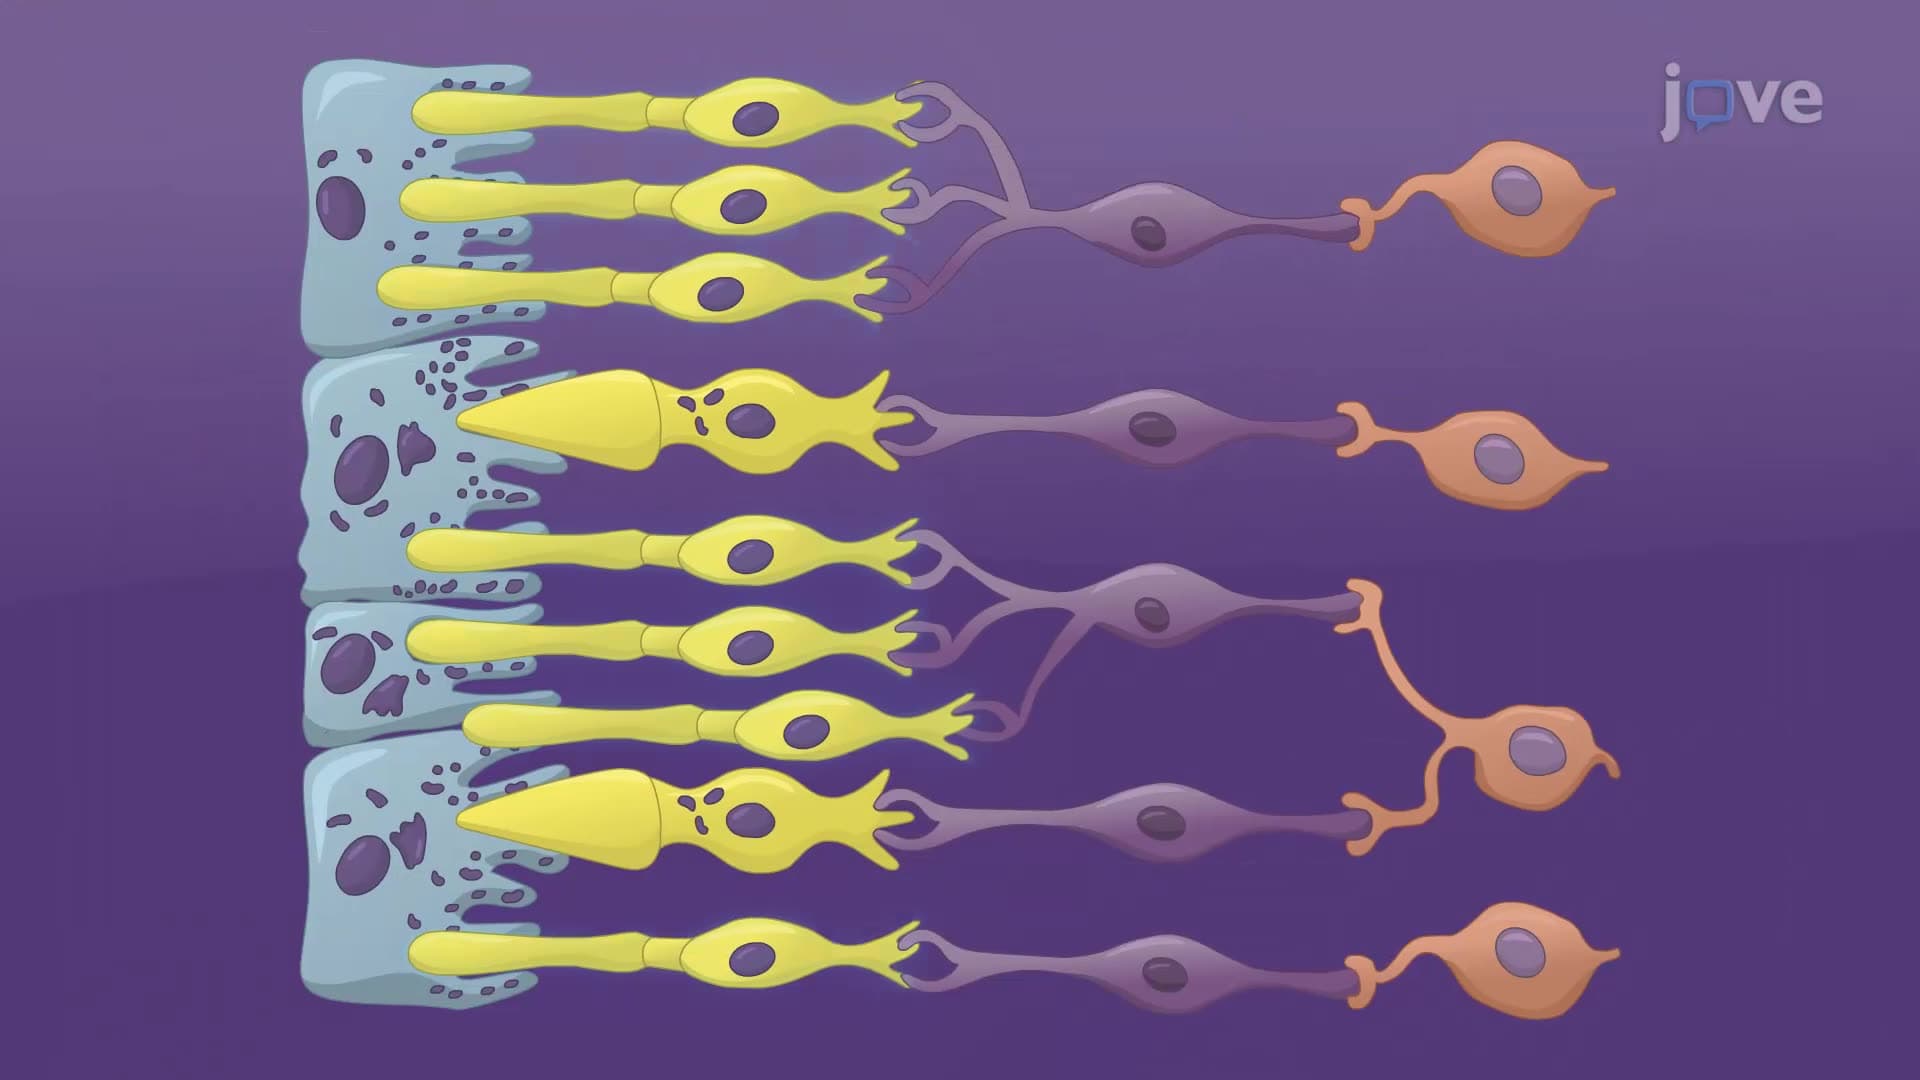
Light enters the eye through the cornea, a transparent, dome-shaped surface covering the surface of the eyeball that helps to direct and focus incoming light. This light is then channeled toward the pupil, an adjustable opening whose size is controlled by the iris. The iris, a pigmented muscle, regulates the amount of light entering the eye by contracting or dilating the pupil, thereby ensuring optimal light levels for clear vision.
Once through the pupil, the light passes through the lens, a...
Once through the pupil, the light passes through the lens, a...
706
 01:15
Depth Perception and Spatial Vision
979
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
979
 01:05
Difference from Background: Limit of Detection
7.1K
The limit of detection (LOD) is the smallest amount of analyte that can be distinguished from the background noise. The LOD value corresponds to the concentration at which the analyte signal is three times larger than the standard deviation of the blank signal. Below this value, the analyte signal cannot be differentiated from the background noise. It is calculated by dividing the calibration slope by 3 times the standard deviation of the blank signals.
The LOD indicates the presence or absence...
The LOD indicates the presence or absence...
7.1K
 01:20
Deconvolution
263
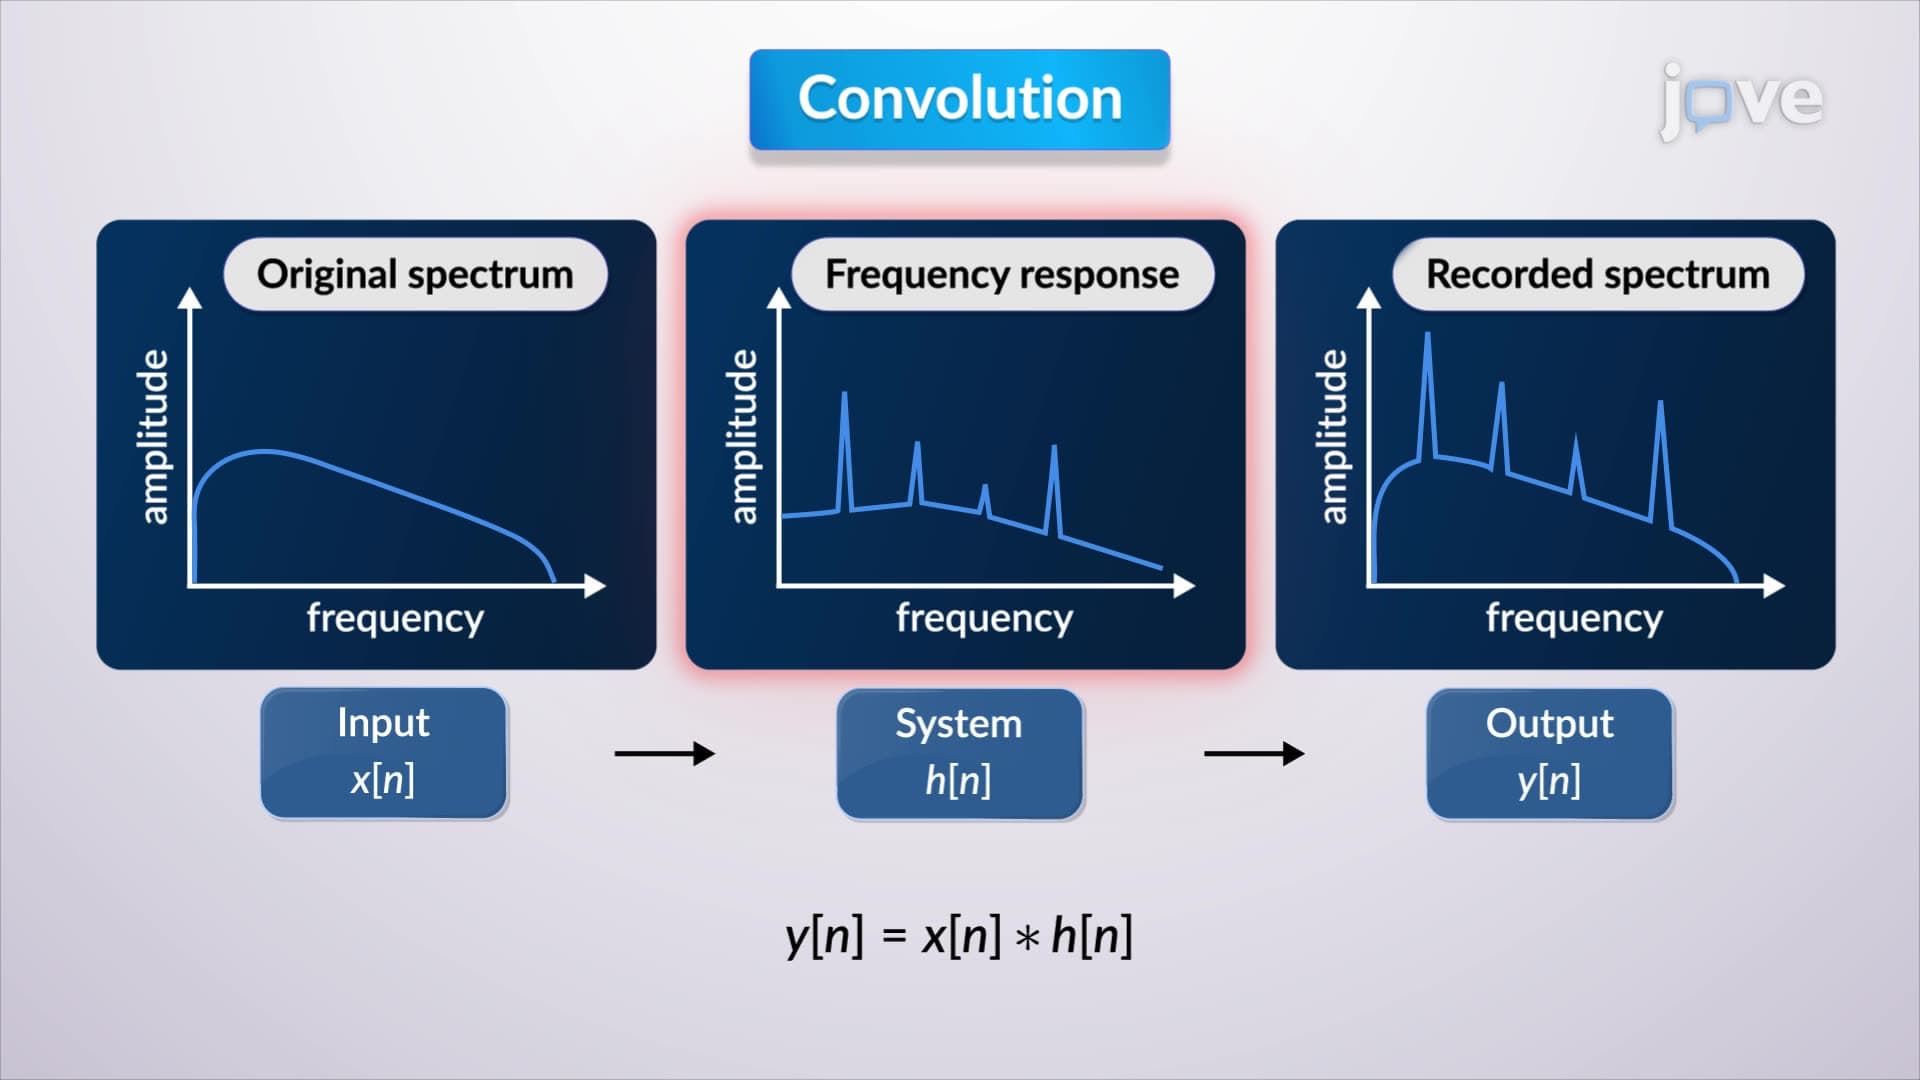
Deconvolution, also known as inverse filtering, is the process of extracting the impulse response from known input and output signals. This technique is vital in scenarios where the system's characteristics are unknown, and they must be inferred from the observable signals.
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
263
 01:20
Structural Classification of Joints
4.4K
Joints, also known as articulations, are classified based on their structural characteristics, i.e., based on whether the articulating surfaces of the adjacent bones are directly connected by fibrous connective tissue or cartilage, or whether the articulating surfaces contact each other within a fluid-filled joint cavity. These differences serve to divide the joints of the body into three structural classifications.
A fibrous joint is where the adjacent bones are united by fibrous connective...
A fibrous joint is where the adjacent bones are united by fibrous connective...
4.4K