使用预训练生成模型进行实时网络延迟估计


概括
我们开发了一种预训练生成模型 (PGM),用于快速估计网络延迟. 这种方法可以在50毫秒内实现准确的实时延迟估计,改善网络性能监控.
科学领域:
- 计算机科学 计算机科学
- 网络工程 网络工程
背景情况:
- 准确的网络延迟估计对于性能监控和管理至关重要.
- 当前的方法与现代网络的实时需求作斗争.
研究的目的:
- 引入一种用于即时网络延迟估计的新方案.
- 为了解决现有的延迟估计技术的局限性.
主要方法:
- 提出了一个两阶段预训练的基于生成模型的方案 (PGM).
- 利用预训练的生成模型来放松低级限制在延迟矩阵完成.
- 为提高效率,优化了缩小的潜伏表示,而不是完整的矩阵.
主要成果:
- 在50毫秒内实现了准确的延迟估计.
- 在PlanetLab数据集上保持了不超过0.11的相对平方误差 (RSE).
- 在真实世界的网络数据上证明了PGM的有效性.
结论:
- PGM 能够有效地进行实时网络延迟估计.
- 拟议的方法比现有技术提供了显著的改进.
- 理论上的保证支持了PGM计划的误差极限.
相关概念视频
 01:03
Prediction Intervals
3.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.3K
 01:06
What are Estimates?
8.2K
It isn't easy to measure a parameter such as the mean height or the mean weight of a population. So, we draw samples from the population and calculate the mean height or mean weight of the individuals in the sample. This sample data acts as a representative measure of the population parameter. These sample statistics are known as estimates.
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
8.2K
 01:05
Estimation of the Physical Quantities
7.2K
On many occasions, physicists, other scientists, and engineers need to make estimates of a particular quantity. These are sometimes referred to as guesstimates, order-of-magnitude approximations, back-of-the-envelope calculations, or Fermi calculations. The physicist Enrico Fermi was famous for his ability to estimate various kinds of data with surprising precision. Estimating does not mean guessing a number or a formula at random. Instead, estimation means using prior experience and sound...
7.2K
 02:07
Improving Translational Accuracy
14.1K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
14.1K
02:07Improving Translational Accuracy
3.6K
3.6K
 01:07
End Point Prediction: Gran Plot
1.2K
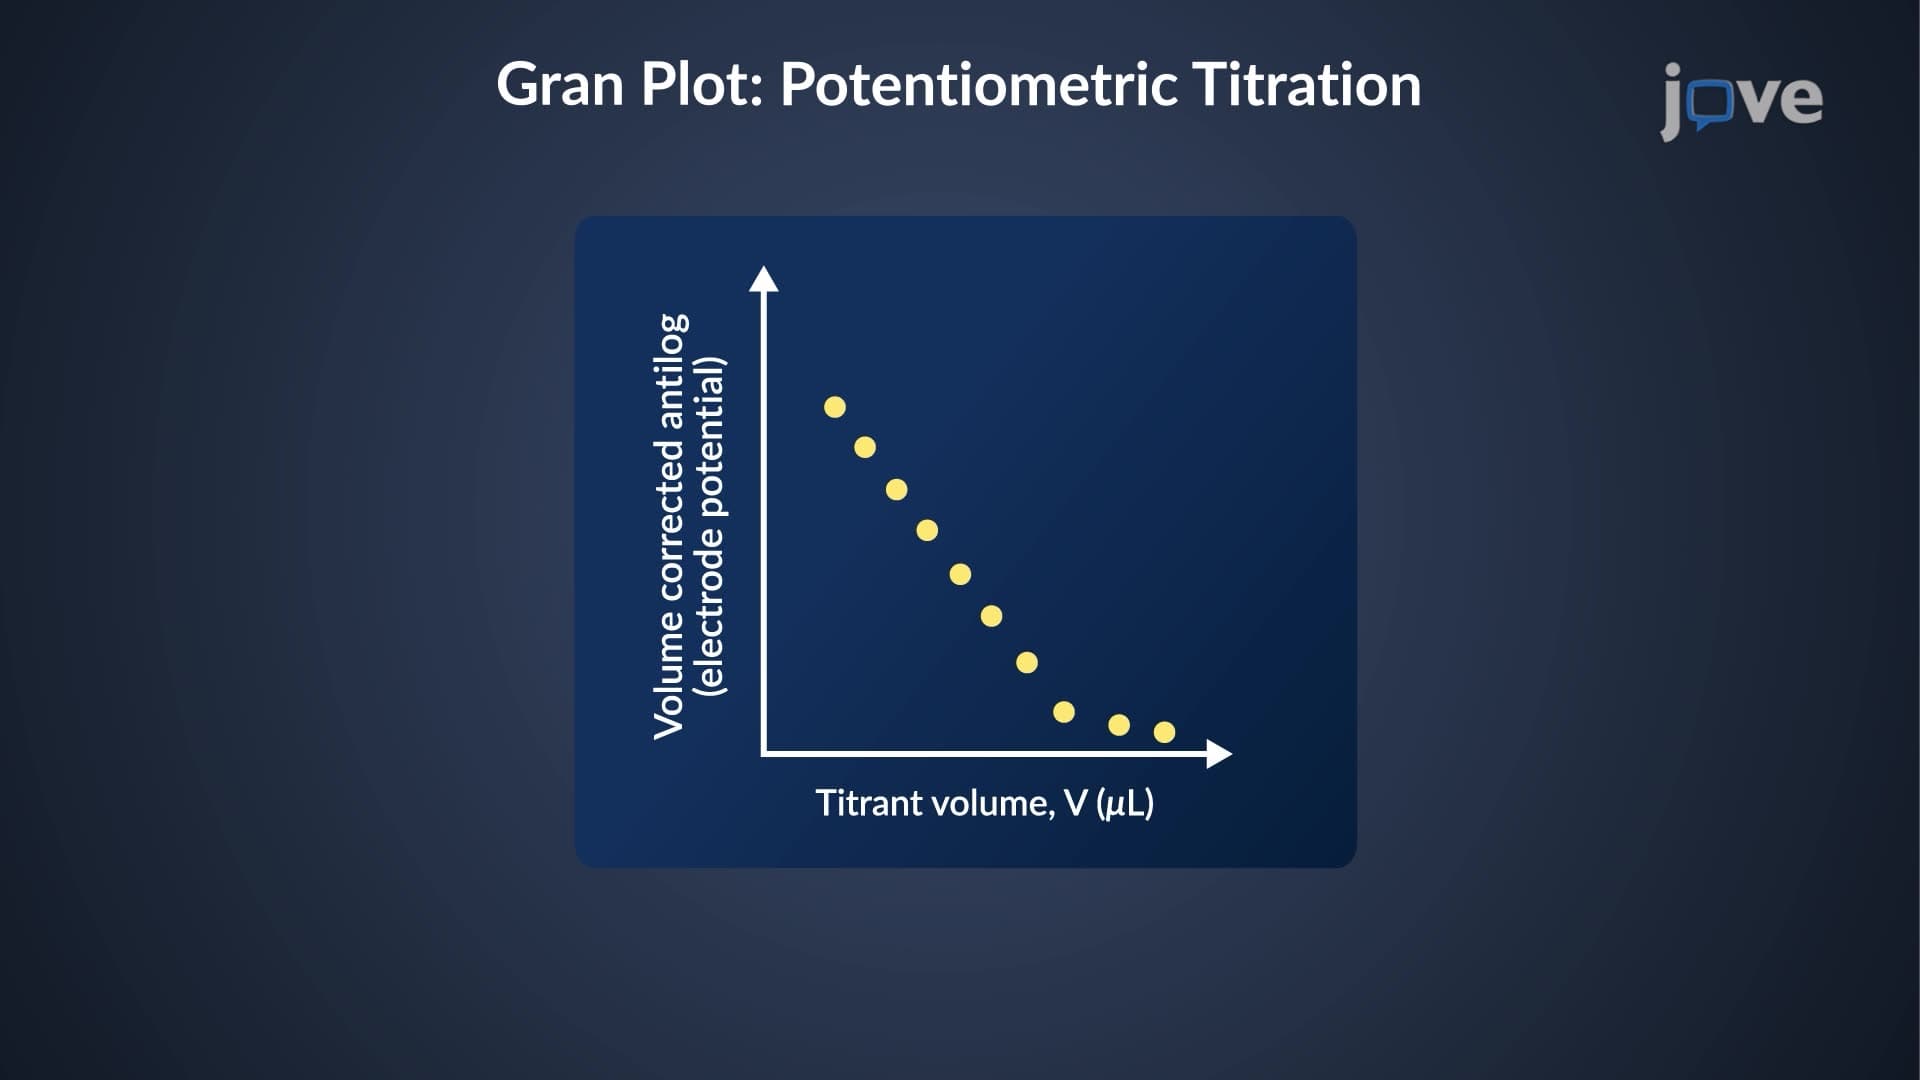
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
1.2K