混合密度网络中的处罚回归线
Quentin Edward Seifert1, Anton Thielmann2, Elisabeth Bergherr1
1Chair of Spatial Data Science and Statistical Learning, University of Göttingen, Göttingen, Germany.
The international journal of biostatistics
|June 4, 2025

概括
混合密度网络 (MDN) 经常在识别潜在组件方面遇到困难. 用被处罚的立方回归分线取代隐藏层,在混合物模型中显著改善了组件识别.
科学领域:
- 统计 统计 统计 统计
- 机器学习 机器学习
- 计算统计学 计算统计学
背景情况:
- 混合密度网络 (MDNs) 模型数据来自多个底层分布.
- 在准确识别这些潜在组件方面,MDN可能面临挑战.
- 目前的解决方案,如自定义重量初始化是主观和次优的.
研究的目的:
- 解决混合密度网络中的组件识别问题.
- 为MDN中传统的隐藏层提供替代方案.
- 为了提高混合模型中参数估计的可靠性.
主要方法:
- 在MDNs中取代了标准隐藏层,用处罚的立方回归线.
- 使用这些splines估计的分布参数.
- 在模拟的高斯和玛混合分布上测试了这种方法.
主要成果:
- 提出的基于spline的方法大大提高了组件识别性能.
- 在模拟中,Splines可靠地汇聚到真实参数值.
- 对于间接参考区间估计的有效性已被证明.
结论:
- 处罚立方回归线为MDN组件识别提供了强大的解决方案.
- 这种方法克服了主观初始化策略的局限性.
- 这种方法对复杂的密度估计任务具有前景.
相关概念视频
 01:52
Regression Toward the Mean
6.5K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.5K
 01:11
Regression Analysis
6.1K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
6.1K
 01:11
Residuals and Least-Squares Property
7.9K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.9K
 01:25
Multiple Regression
3.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.2K
 01:09
Poisson Probability Distribution
8.5K
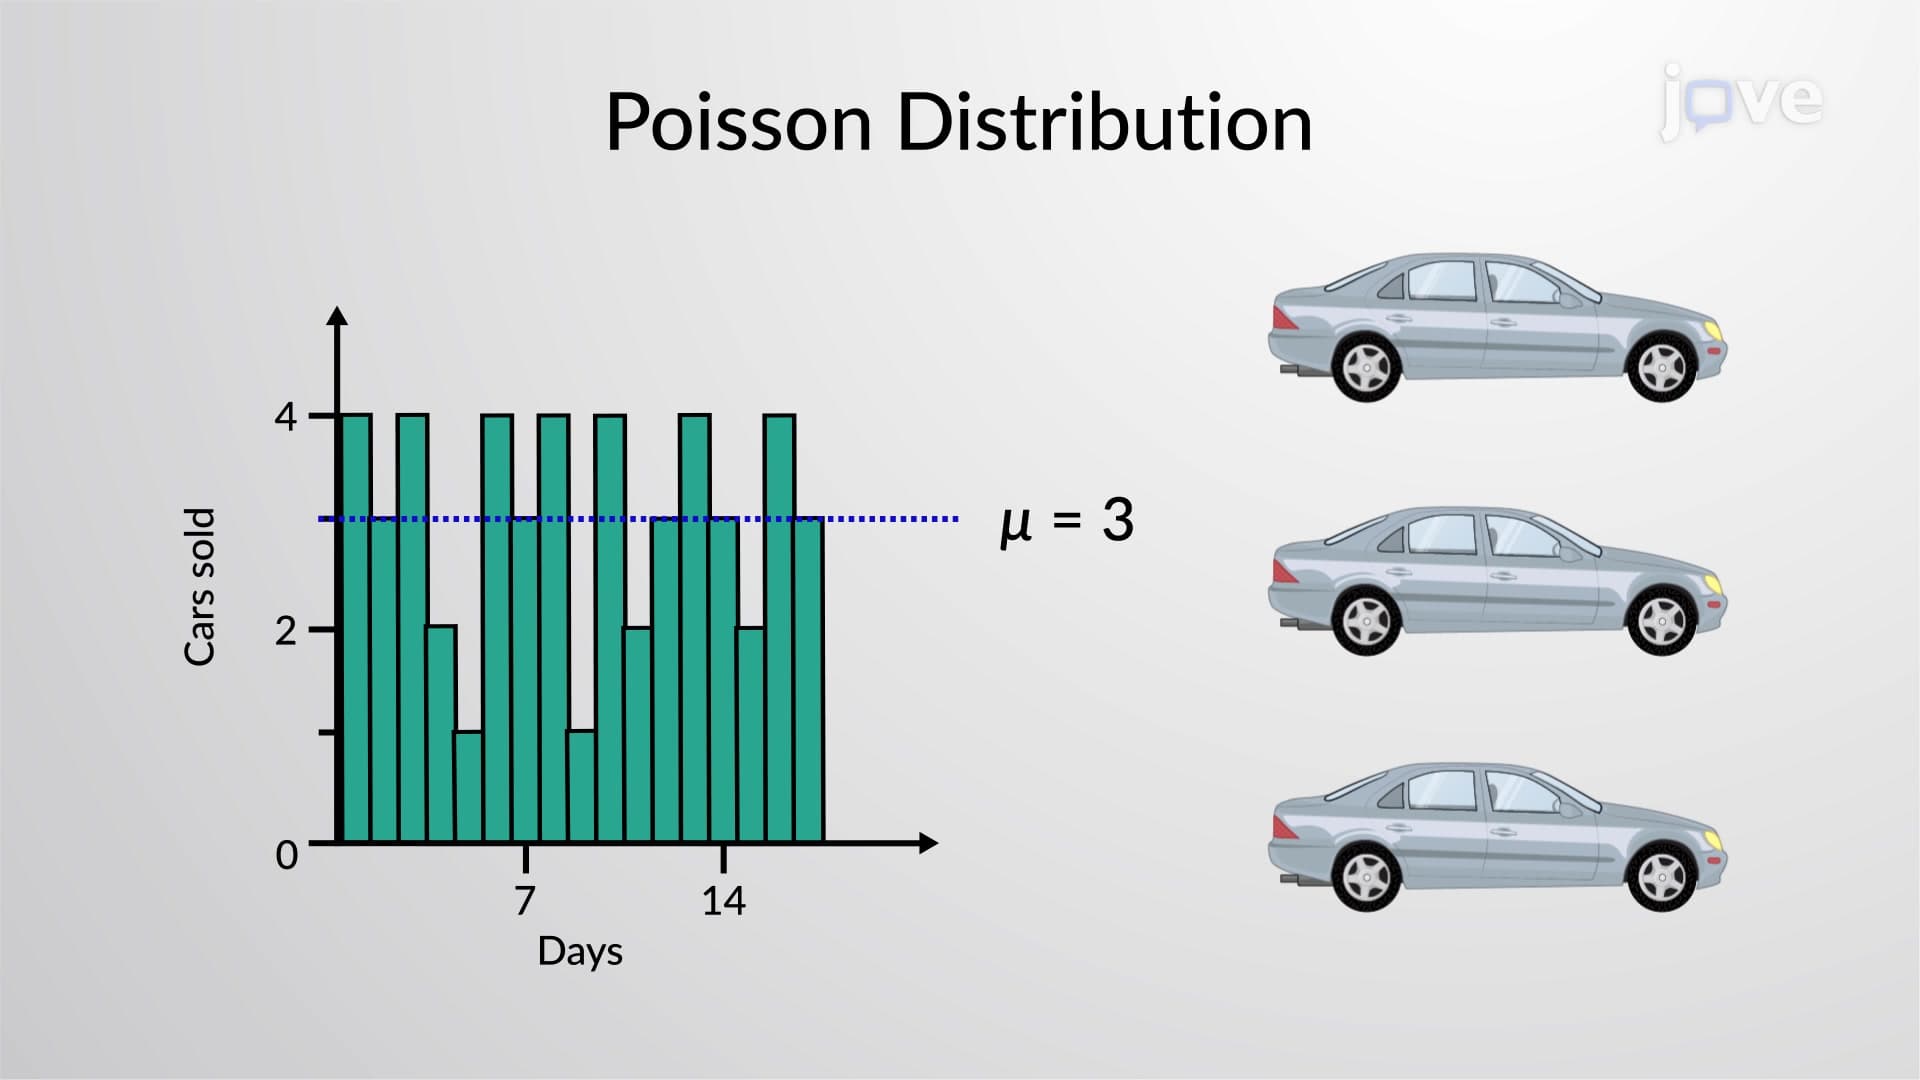
A Poisson probability distribution is a discrete probability distribution. It gives the probability of a number of events occurring in a fixed interval of time or space if these events happen at a known average rate and independently of the time since the last event. For example, a book editor might be interested in the number of words spelled incorrectly in a particular book. It might be that, on average, there are five words spelled incorrectly in 100 pages. The interval is 100 pages.
The...
The...
8.5K
 01:32
Probability Distributions
8.0K
The probability of a random variable x is the likelihood of its occurrence. A probability distribution represents the probabilities of a random variable using a formula, graph, or table. There are two types of probability distribution– discrete probability distribution and continuous probability distribution.
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
8.0K