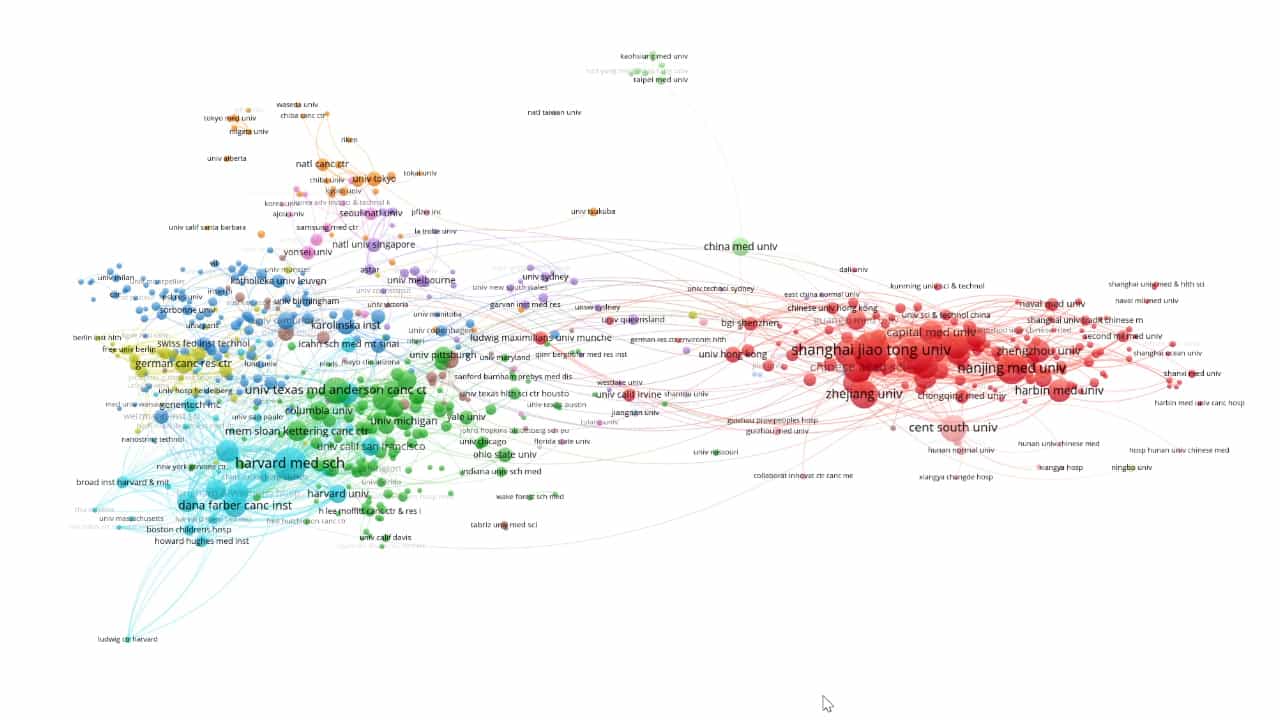
对台湾每月谷歌搜索量和自杀的交叉相关性分析,2012-2022年
Cheng-Fang Yen1,2,3, Yu-Hsuan Lin4,5,6,7, Ray C Hsiao8,9
1Department of Psychiatry, Kaohsiung Medical University Hospital, Kaohsiung Medical University, Kaohsiung, Taiwan.
Depression and anxiety
|June 13, 2025

概括
谷歌搜索"疼痛"和"台湾经济"可能会预测未来的自杀. "催眠"和"过敏"等特定术语也显示了老年人的相关性,有助于预测自杀.
科学领域:
- 公共卫生 公共卫生
- 流行病学 流行病学
- 数字健康数字健康
背景情况:
- 自杀在全球范围内仍然是一个重大的公共卫生问题.
- 了解自杀的预测因素对于预防工作至关重要.
- 数字数据源,如搜索引擎查询,为监测人口心理健康趋势提供了新的途径.
研究的目的:
- 调查谷歌搜索术语与台湾的自杀率之间的潜在关联.
- 检查这些关联在不同的时间滞后 (1,2,3个月).
- 识别特定的搜索术语,这些术语可以作为自杀风险的早期指标.
主要方法:
- 来自台湾死亡原因统计 (2012-2022) 的每日自杀数据的分析.
- 使用谷歌趋势提取37个相关术语的谷歌搜索量.
- 计算月度搜索量和自杀数量之间的交叉相关系数在1,2,3个月的滞后.
主要成果:
- 每月谷歌搜索"疼痛"和"台湾经济"的数量正面地预测了普通人口的每月自杀率.
- 搜索术语"催眠"显示,在3个月的滞后后,65岁及以上的个人中,与自杀率存在负相关性.
- 搜索术语"过敏"在1个月的滞后后,在65岁及以上的个人中,与自杀率有积极的相关性.
结论:
- 谷歌搜索术语"疼痛"和"台湾经济"是整体自杀率的潜在主要指标.
- 搜索术语"催眠"和"过敏"显示了老年人中自杀风险的特定预测价值.
- 这些发现表明,分析特定的谷歌搜索趋势可以增强自杀预测模型.
相关概念视频
 01:21
Cancer Survival Analysis
334
Cancer survival analysis focuses on quantifying and interpreting the time from a key starting point, such as diagnosis or the initiation of treatment, to a specific endpoint, such as remission or death. This analysis provides critical insights into treatment effectiveness and factors that influence patient outcomes, helping to shape clinical decisions and guide prognostic evaluations. A cornerstone of oncology research, survival analysis tackles the challenges of skewed, non-normally...
334
 01:09
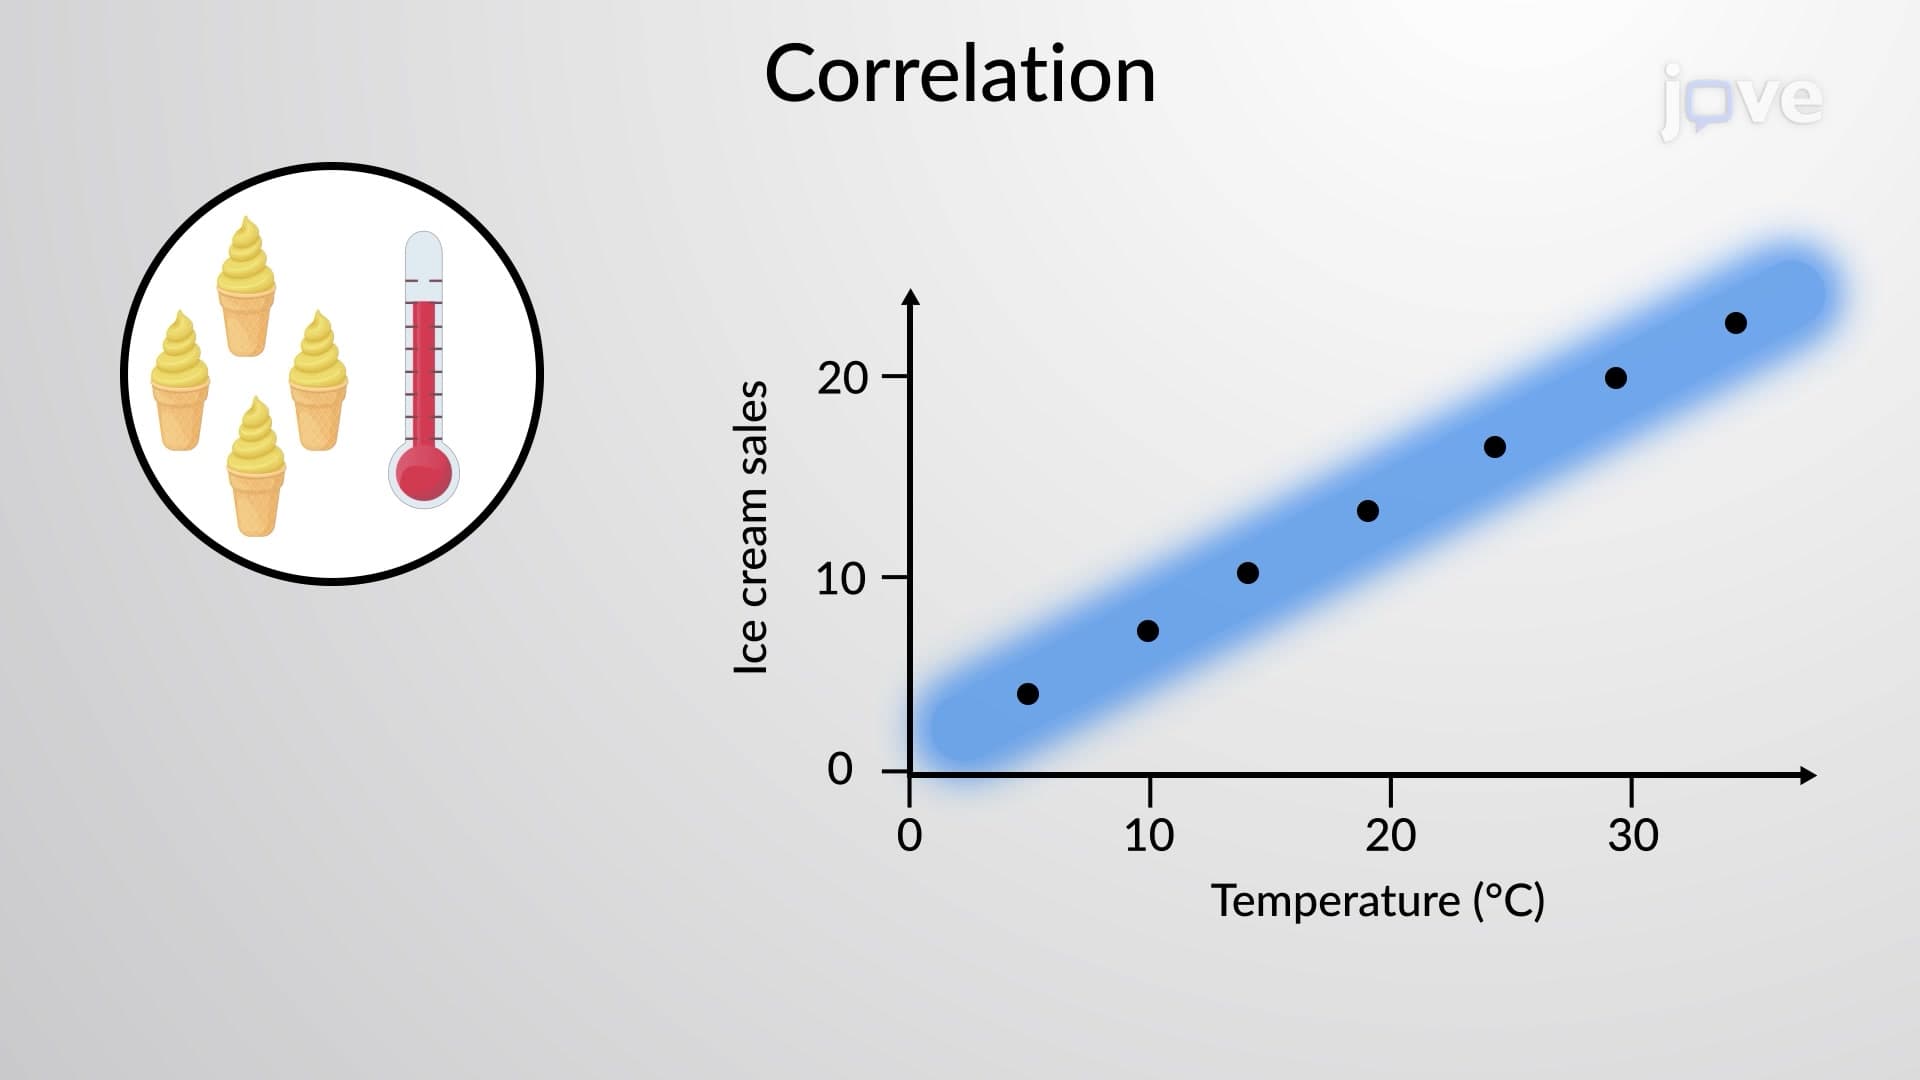
Correlation
11.7K
In statistics, two variables are said to be correlated if the values of one variable are associated with the other variable. Depending on the relationship between two variables, correlation can be of three types– positive correlation, negative correlation, and zero correlation.
Two variables, for example, a and b, are said to be positively correlated if both variables move in the same direction. In other words, a positive correlation exists between two variables, a and b, if:
Two variables, for example, a and b, are said to be positively correlated if both variables move in the same direction. In other words, a positive correlation exists between two variables, a and b, if:
11.7K
 02:20
Correlations
32.7K
Correlation means that there is a relationship between two or more variables (such as ice cream consumption and crime), but this relationship does not necessarily imply cause and effect. When two variables are correlated, it simply means that as one variable changes, so does the other. We can measure correlation by calculating a statistic known as a correlation coefficient. A correlation coefficient is a number from -1 to +1 that indicates the strength and direction of the relationship between...
32.7K
 01:15
Drug Concentration Versus Time Correlation
678
The plasma drug concentration-time curve is a crucial tool in pharmacokinetics, representing the drug's concentration in plasma at different time intervals post-administration. This curve illustrates the drug's journey from absorption into the systemic circulation, distribution to body tissues, and eventual elimination through excretion or biotransformation.
Two pivotal parameters are the minimum effective concentration (MEC) and the minimum toxic concentration (MTC). The MEC is the...
Two pivotal parameters are the minimum effective concentration (MEC) and the minimum toxic concentration (MTC). The MEC is the...
678
 01:25
Statistical Methods for Analyzing Epidemiological Data
330
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
330
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K