
优化客户流失预测使用基于表式生成对抗网络 (GAN) 的混合采样方法和成本敏感的学习
I Nyoman Mahayasa Adiputra1, Paweena Wanchai1, Pei-Chun Lin2
1College of Computing, Khon Kaen University, Khon Kaen, Thailand.
PeerJ. Computer science
|June 26, 2025

概括
CostLearnGAN是一种新的混合采样方法,通过处理不平衡的数据,增强了用于预测客户流失的经典机器学习. 这种方法提高了模型的性能和稳定性,为大型数据集提供了高效的解决方案.
科学领域:
- 机器学习 机器学习
- 数据科学数据科学数据科学
- 人工智能的人工智能
背景情况:
- 在客户流失预测中的不平衡和重叠数据会对分类准确性产生负面影响.
- 现有的采样和混合采样方法显示了与经典机器学习算法的局限性.
- 经典算法与在流失预测中常见的不平衡数据集作斗争.
研究的目的:
- 为客户流失预测优化经典机器学习性能.
- 引入CostLearnGAN,一个成本敏感的学习框架,集成生成对抗网络 (GAN) 和混合采样.
- 提高经典机器学习算法的有效性,以识别客户流失.
主要方法:
- 开发了CostLearnGAN,这是一个表式生成对抗网络 (GAN) 混合抽样方法.
- 应用了成本敏感的学习视角来改进经典机器学习算法.
- 使用六种比较采样方法,六个数据集和三种机器学习算法进行实验.
主要成果:
- 在所有评估指标上,CostLearnGAN 取得了卓越的表现,平均平均排名得分为 1.44.
- 证明了CostLearnGAN的稳定性,其表现优于其他采样方法,平均稳定性值为5.68.
- 验证了经典机器学习算法的效率,以更短的执行时间来进行大规模的流失预测.
结论:
- 在客户流失预测中,CostLearnGAN显著提高了经典机器学习模型的性能和稳定性.
- 成本敏感的学习方法与GAN混合采样相结合,为不平衡的数据挑战提供了有效的解决方案.
- 通过CostLearnGAN增强的经典机器学习算法,适合在大客户群中高效预测流失率.
相关概念视频
 01:03
Prediction Intervals
2.4K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.4K
 01:19
Survival Tree
166
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
166
 01:07
End Point Prediction: Gran Plot
614
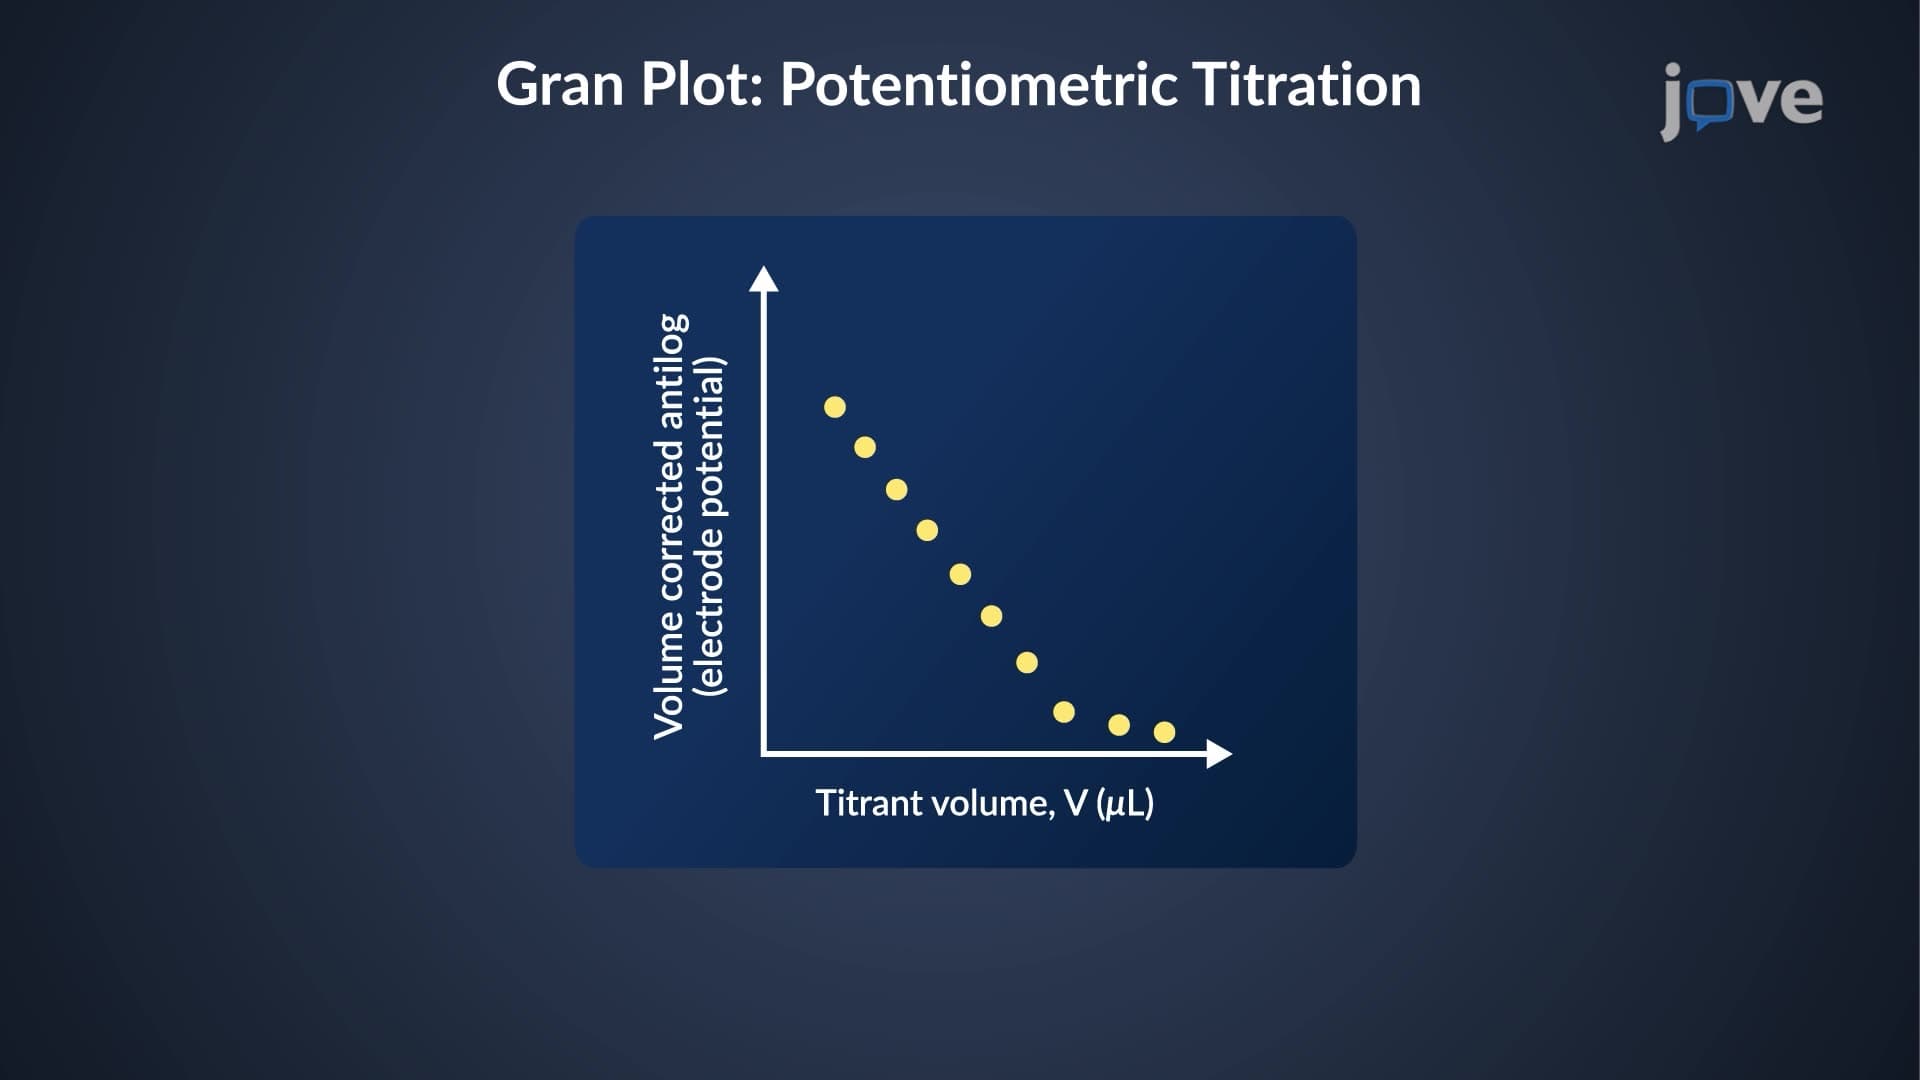
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
614
 01:20
Cluster Sampling Method
12.9K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
12.9K
 01:07
Ogive Graph
5.9K
An ogive graph is sometimes called a cumulative frequency polygon. It is one type of frequency polygon that shows cumulative frequency. In other words, the cumulative percentages are added to the graph from left to right. An ogive graph plots cumulative frequency on the vertical y-axis and class boundaries along the horizontal x-axis. It’s very similar to a histogram; only instead of rectangles, an ogive displays a single point where the top right of the rectangle would be. Creating this...
5.9K
 01:09
Random Sampling Method
12.5K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. Data are the result of sampling from a population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest. Among the various sampling methods used by...
12.5K