相关实验视频
Updated: Sep 17, 2025

05:37

An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.2K
两家α-maxmin平均偏差保险公司之间的再保险投资游戏
Qian Zhang1, Guoyong Zhou1, Jing Fu2
1School of Mathematics and Physics, Leshan Normal University, Leshan, Sichuan, China.
PloS one
|June 27, 2025

概括
本研究探讨了一种竞争性的再保险投资游戏,使用一个强大的标准,确定面临市场模两可和相对绩效问题的保险公司的最佳策略. 这些发现提供了对保险市场强有力的平衡策略的见解.
科学领域:
- 精算科学 精算科学
- 金融数学 金融数学
- 游戏理论 游戏理论
背景情况:
- 具有竞争力的保险公司面临着关于再保险和投资的复杂决策.
- 模型的模糊性和相对性能是保险公司决策的关键因素.
- 随机差异游戏为分析金融市场战略互动提供了一个框架.
研究的目的:
- 分析两个竞争性保险公司之间的非零和随机差异再保险投资游戏.
- 将[公式:见文本]-最大平均偏差标准应用于模拟保险公司在模两可的情况下的效用.
- 为再保险和投资推导出强大的平衡策略.
主要方法:
- 制定一个非零和的随机微分游戏.
- [公式:请参阅文本]-最大平均方差实用性的应用.
- 解决扩展的汉密尔顿 - 雅各比 - 贝尔曼 (HJB) 方程.
- 导出平衡策略的导出. 平衡策略.
主要成果:
- [公式:见文本] - - 强平衡再保险和投资策略的衍生.
- 该研究确定了考虑终端余和相对业绩的最佳策略.
- 数字示例说明了模型参数对平衡策略的影响.
结论:
- [公式:见文本]-最大平均偏差标准有效地模拟了保险公司在模两可的情况下的行为.
- 由此产生的策略为保险公司的竞争性决策提供了坚实的框架.
- 了解参数影响对于保险和投资的实际应用至关重要.
相关概念视频
 01:20
Actuarial Approach
140
The actuarial approach, a statistical method originally developed for life insurance risk assessment, is widely used to calculate survival rates in clinical and population studies. This method accounts for participants lost to follow-up or those who die from causes unrelated to the study, ensuring a more accurate representation of survival probabilities.
Consider the example of a high-risk surgical procedure with significant early-stage mortality. A two-year clinical study is conducted,...
Consider the example of a high-risk surgical procedure with significant early-stage mortality. A two-year clinical study is conducted,...
140
 01:12
Relative Risk
361
Relative risk (RR) is a statistical measure commonly used in epidemiology to compare the likelihood of a particular event occurring between two groups. This metric is important for evaluating the relationship between exposure to a specific risk factor and the probability of a particular outcome. It plays a crucial role in medical research, public health studies, and risk assessment. Relative risk quantifies how much more (or less) likely an event is to occur in an exposed group compared to an...
361
 01:15
Expected Value
4.2K
The expected value is known as the "long-term" average or mean. This means that over the long term of experimenting over and over, you would expect this average. The expected average is represented by the symbol μ. It is calculated as follows:
4.2K
 01:15
One-Way ANOVA: Equal Sample Sizes
3.5K
One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
3.5K
 01:19
Routh-Hurwitz Criterion II
421
In the application of the Routh-Hurwitz criterion, two specific scenarios can arise that complicate stability analysis.
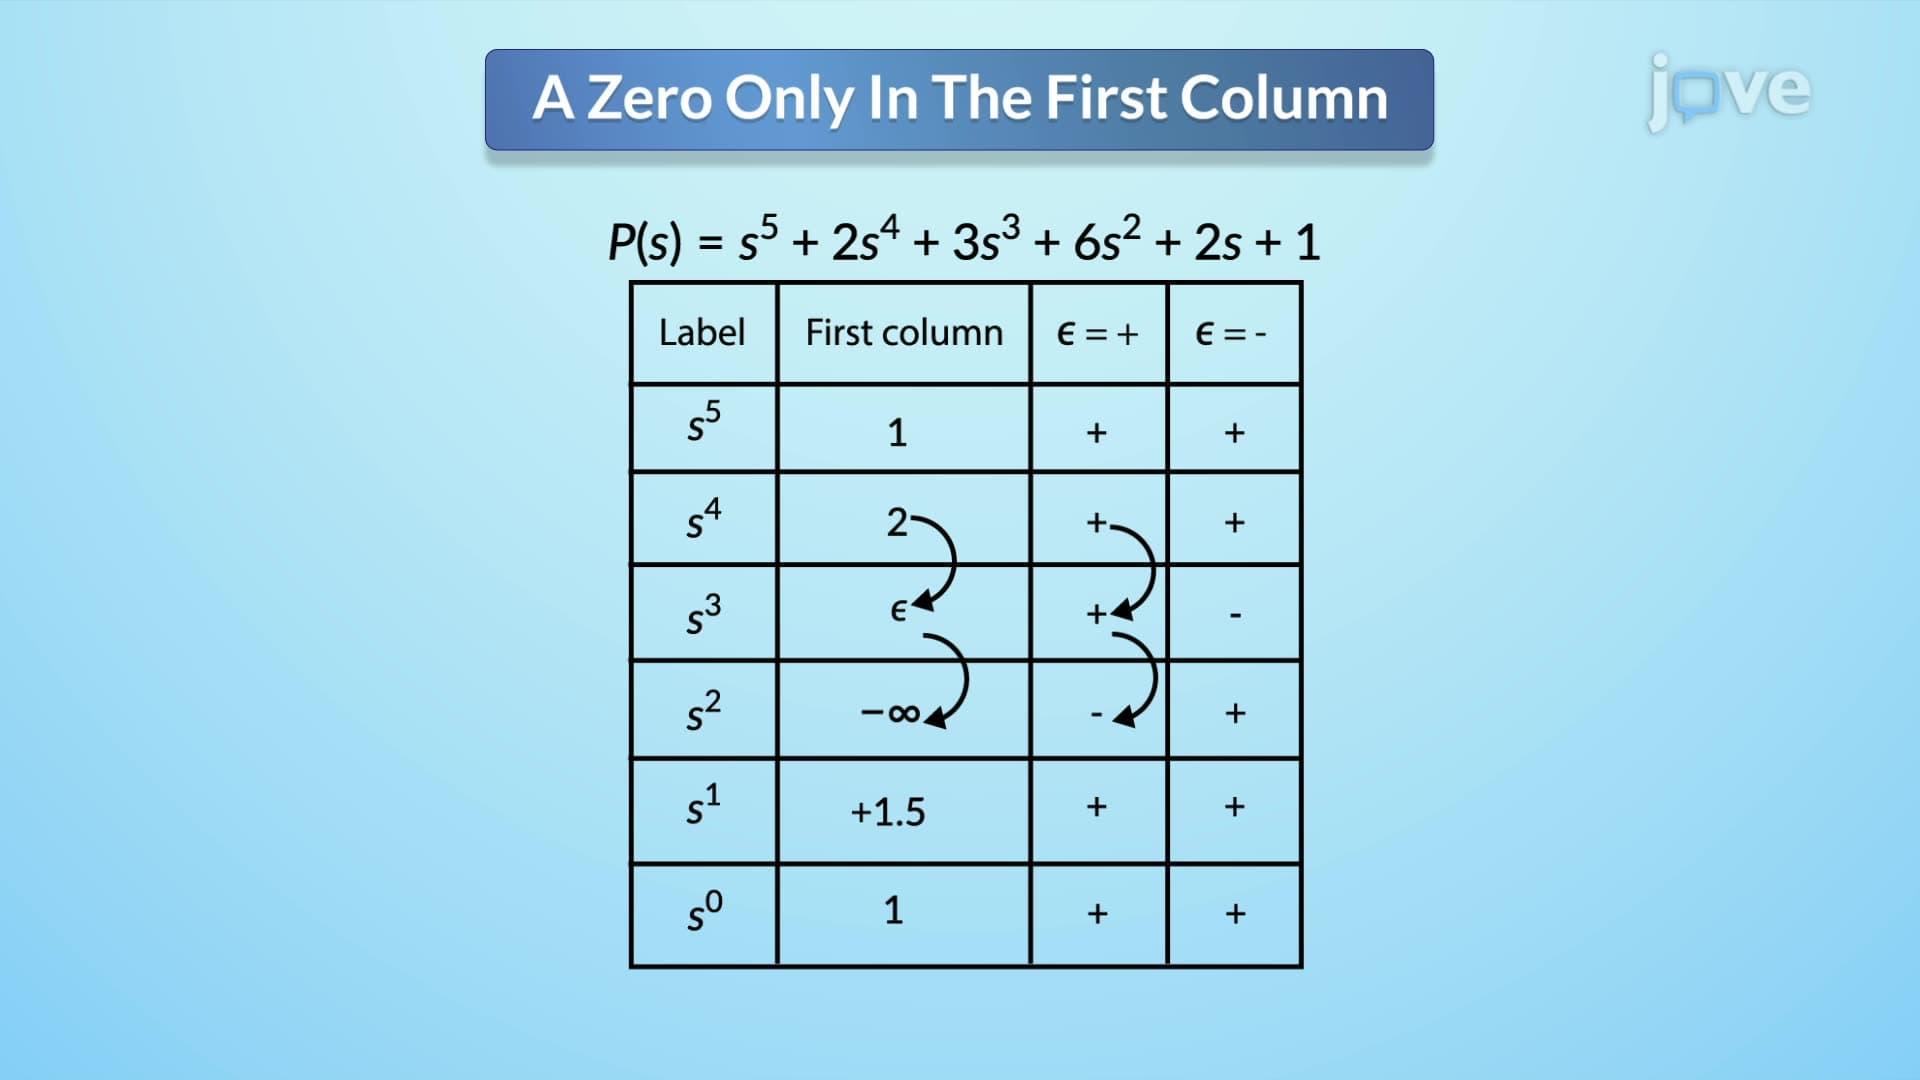
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
421
 01:17
Wald-Wolfowitz Runs Test II
328
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
328