一种新的方法来估计习惯性摄入的营养素与扭曲分布的新方法
Smitha Joseph1, Sumathi Swaminathan2, Santu Ghosh3
1Research Scholar, Manipal Academy of Higher Education, Manipal, Karnataka, India; Division of Epidemiology and Biostatistics, St. John's Research Institute, St Johns National Academy of Health Sciences (a Unit of CBCI Society for Medical Education), Bangalore, Karnataka, India.
The Journal of nutrition
|June 30, 2025

概括
一种新的玛回归方法准确地估计了习惯性营养摄入量,即使数据偏差. 这种更简单的方法提供了与现有的复杂方法可比的结果,使饮食评估更有效.
科学领域:
- 营养科学 营养科学
- 统计建模 统计建模
- 公共卫生研究 公共卫生研究
背景情况:
- 估计习惯性营养摄入量通常依赖于多个24小时的饮食回忆.
- 目前用于偏斜摄入分布的方法是计算密集的.
研究的目的:
- 引入和评估一种新的玛回归方法,用于估计习惯性营养摄入量.
- 为了应对人口研究中偏差营养摄入量分布的挑战.
主要方法:
- 建议的玛回归方法与国家研究委员会和爱荷华州立大学 (ISU) 的方法进行了比较.
- 分析了来自印度比哈尔的120名儿童 (0.5-5岁) 的数据,使用了4个非连续的饮食回忆.
- 对比涉及评估习惯性营养摄入量及其95%置信区间与8.2%的等效限之间的差异.
- 进行了模拟,以评估不同数据偏差对估计的影响.
主要成果:
- 玛回归提供了896千卡路里的中位能量摄入量估计,蛋白质为22.6克,铁为5.8毫克,维生素A为107毫克RAE.
- 对玛回归的百分比偏差在所有研究的营养素 (能量,蛋白质,铁,维生素A) 的8.2%等效限内.
- 模拟证实了玛回归与ISU方法在不同水平的斜率上的可比性.
结论:
- 玛回归法是一种可行的,更简单的替代方法,用于估计习惯性营养摄入量,以偏斜的分布.
- 它提供了与ISU方法等更复杂的方法相当的估计.
- 这种方法提高了人口研究中饮食评估的效率.
相关概念视频
 01:26
Distributions to Estimate Population Parameter
4.3K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.3K
 01:22
Estimating Population Mean with Unknown Standard Deviation
8.3K
In practice, we rarely know the population standard deviation. In the past, when the sample size was large, this did not present a problem to statisticians. They used the sample standard deviation s as an estimate for σ and proceeded as before to calculate a confidence interval with close enough results. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
William S. Gosset (1876–1937) of the...
William S. Gosset (1876–1937) of the...
8.3K
 01:06
Skewness
12.7K
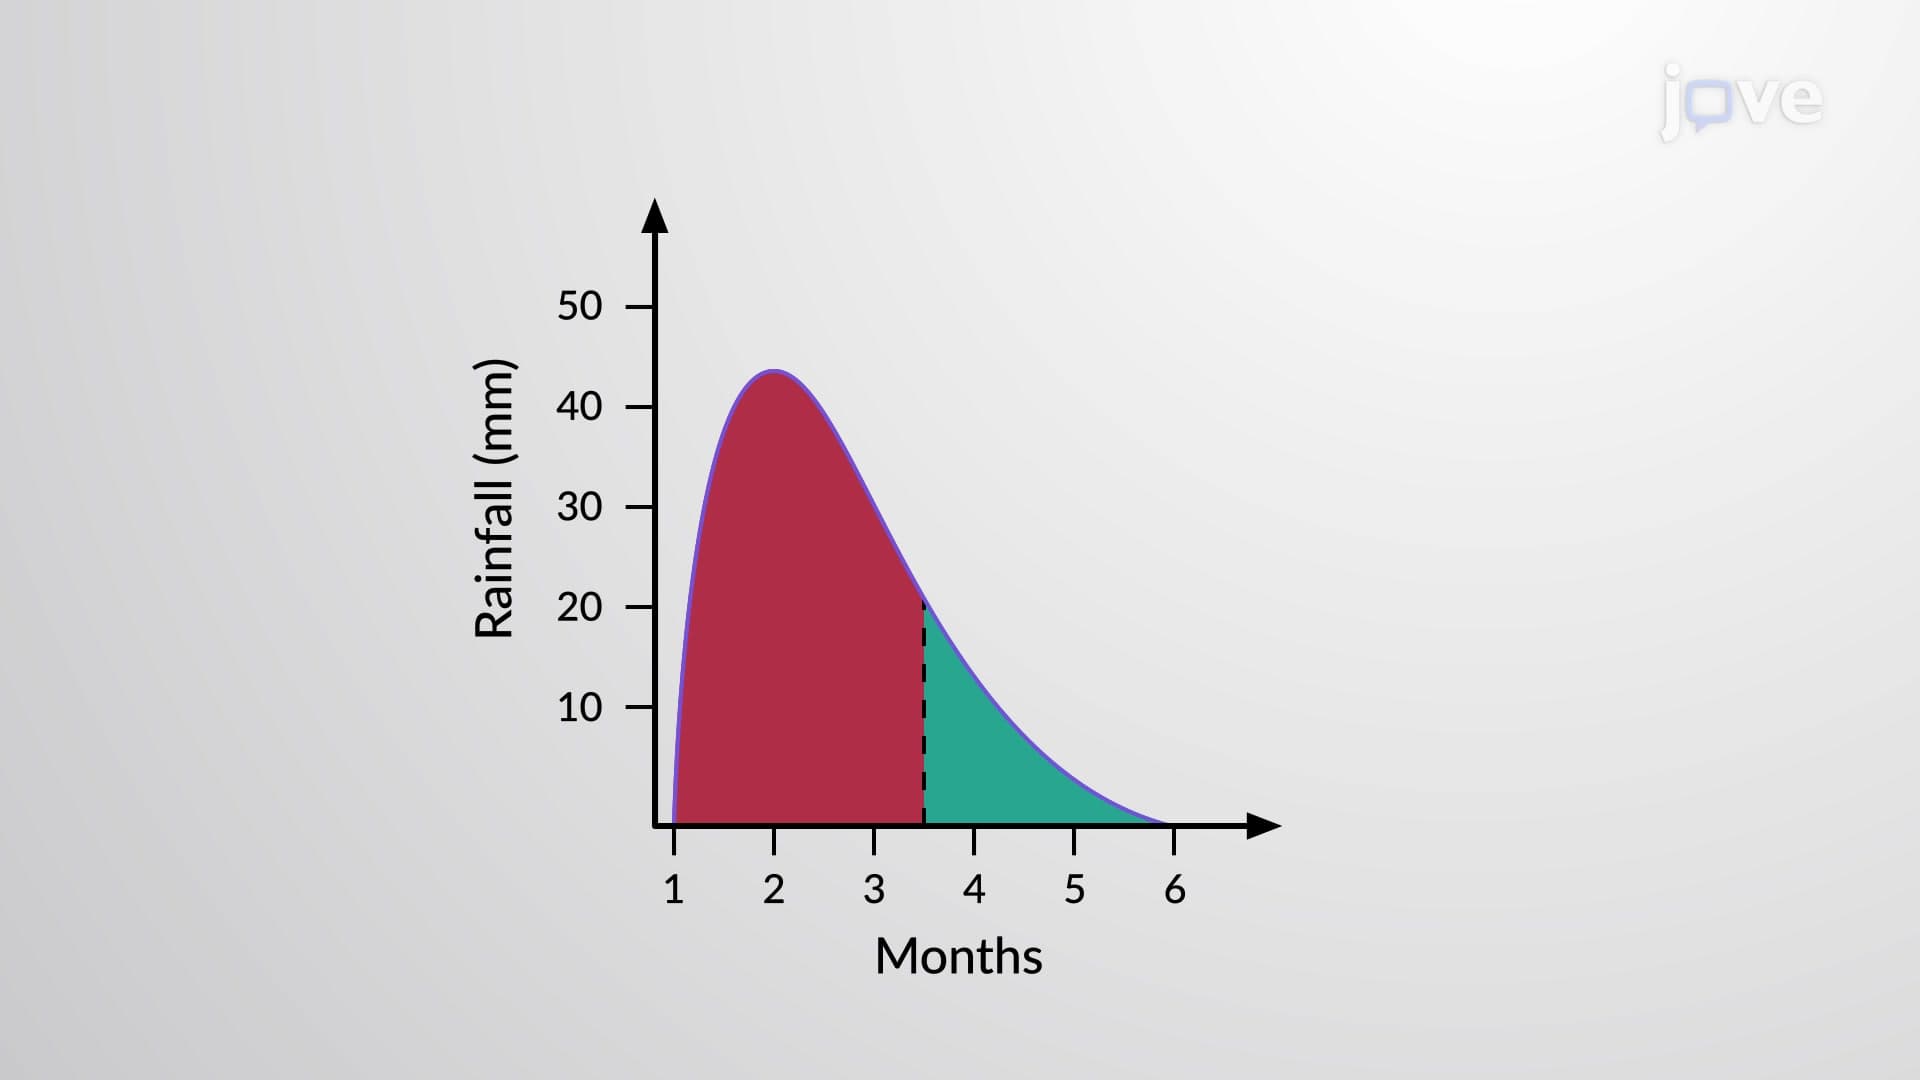
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
12.7K
 01:14
Central Limit Theorem
16.0K
The central limit theorem, abbreviated as clt, is one of the most powerful and useful ideas in all of statistics. The central limit theorem for sample means says that if you repeatedly draw samples of a given size and calculate their means, and create a histogram of those means, then the resulting histogram will tend to have an approximate normal bell shape. In other words, as sample sizes increase, the distribution of means follows the normal distribution more closely.
The sample size, n, that...
The sample size, n, that...
16.0K
 01:25
Choosing Between z and t Distribution
2.9K
The z and the Student t distribution estimate the population mean using the sample mean and standard deviation. However, to decide which distribution to use for a calculation, one needs to determine the sample size, the nature of the distribution, and whether the population standard deviation is known. If the population standard deviation is known and the population is normally distributed, or if the sample size is greater than 30, the z distribution is preferred. The Student t distribution is...
2.9K
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
131
Pharmacokinetic models are mathematical constructs that represent and predict the time course of drug concentrations in the body, providing meaningful pharmacokinetic parameters. These models are categorized into compartment, physiological, and distributed parameter models.
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
131