比较原始分数差异,多级建模和结构方程建模方法,以估计二的差异
Amber McEnturff1, Qi Chen2, Robin K Henson2
1Alexandria City Public Schools, Alexandria, VA, United States.
Frontiers in psychology
|July 4, 2025

概括
推使用原始分数差异 (RSD) 和结构方程建模 (SEM) 方法来估计二次差异分数. 多级建模 (MLM) 的可靠性很差,因此不适合在心理学研究中的实际应用.
科学领域:
- 心理学 心理学 心理学
- 统计 统计 统计 统计
- 量化研究方法 量化研究方法
背景情况:
- 双向数据分析在心理学研究中至关重要,用于检查对 (例如,父母-孩子,配偶) 之间的关系.
- 准确估计二次差异分数对于可靠的结果预测至关重要.
- 计算这些分数的方法有几种,但它们的比较准确性尚未得到充分证实.
研究的目的:
- 为了比较不同二次差异差异得分估计方法的准确性.
- 确定哪种方法提供最可靠的差异估计和最佳结果预测.
- 评估各种设计因素对估计准确性的影响.
主要方法:
- 使用蒙特卡洛模拟来比较三个差异得分估计方法:原始得分差 (RSD),多级建模 (MLM) 和结构方程建模 (SEM).
- 关键的模拟因素包括类内相关性 (ICC),集群数,可靠性,差异效果大小和效果大小差异.
主要成果:
- 多级建模 (MLM) 产生了差异估计的可靠性较差,特别是在高ICC,高效果大小差异和低集群数量的条件下.
- 原始分数差 (RSD) 和结构方程建模 (SEM) 方法在模拟条件下显示了可比且稳定的性能.
- 研究的设计因素并没有显著影响RSD或SEM估计的准确性.
结论:
- 原始分数差 (RSD) 和结构方程建模 (SEM) 是由于其可靠性和稳定性而被推用于实际应用,用于估计二次差异分数.
- 多级建模 (MLM) 不建议用于差异得分估计,因为它的可靠性相对较差.
- 未来的研究应该考虑这些方法在多样化的二级数据结构下的性能.
更多相关视频
 09:00
Author Spotlight: Validation of SICOLE-R for Assessing Cognitive and Reading Skills in Spanish-Speaking Children and Its Role in Personalized Education
Published on: August 16, 2024
918
 04:35
Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
3.4K
相关概念视频
 01:21
Friedman Two-way Analysis of Variance by Ranks
306
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
306
 01:15
One-Way ANOVA: Equal Sample Sizes
3.5K
One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
3.5K
 02:45
Self-Discrepancy Theory
18.5K
One influential perspective on what motivates people's behavior is detailed in Tory Higgin's self-discrepancy theory (Higgins, 1987). He proposed that people hold disagreeing internal representations of themselves that lead to different emotional states.
18.5K
 01:17
Two-Way ANOVA
2.8K
The two-way ANOVA is an extension of the one-way ANOVA. It is a statistical test performed on three or more samples categorized by two factors - a row factor and a column factor. Ronald Fischer mentioned it in 1925 in his book 'Statistical Methods for Researchers.'
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the...
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the...
2.8K
 02:01
Group Design
9.7K
The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between...
9.7K
 01:19
Variation
7.2K
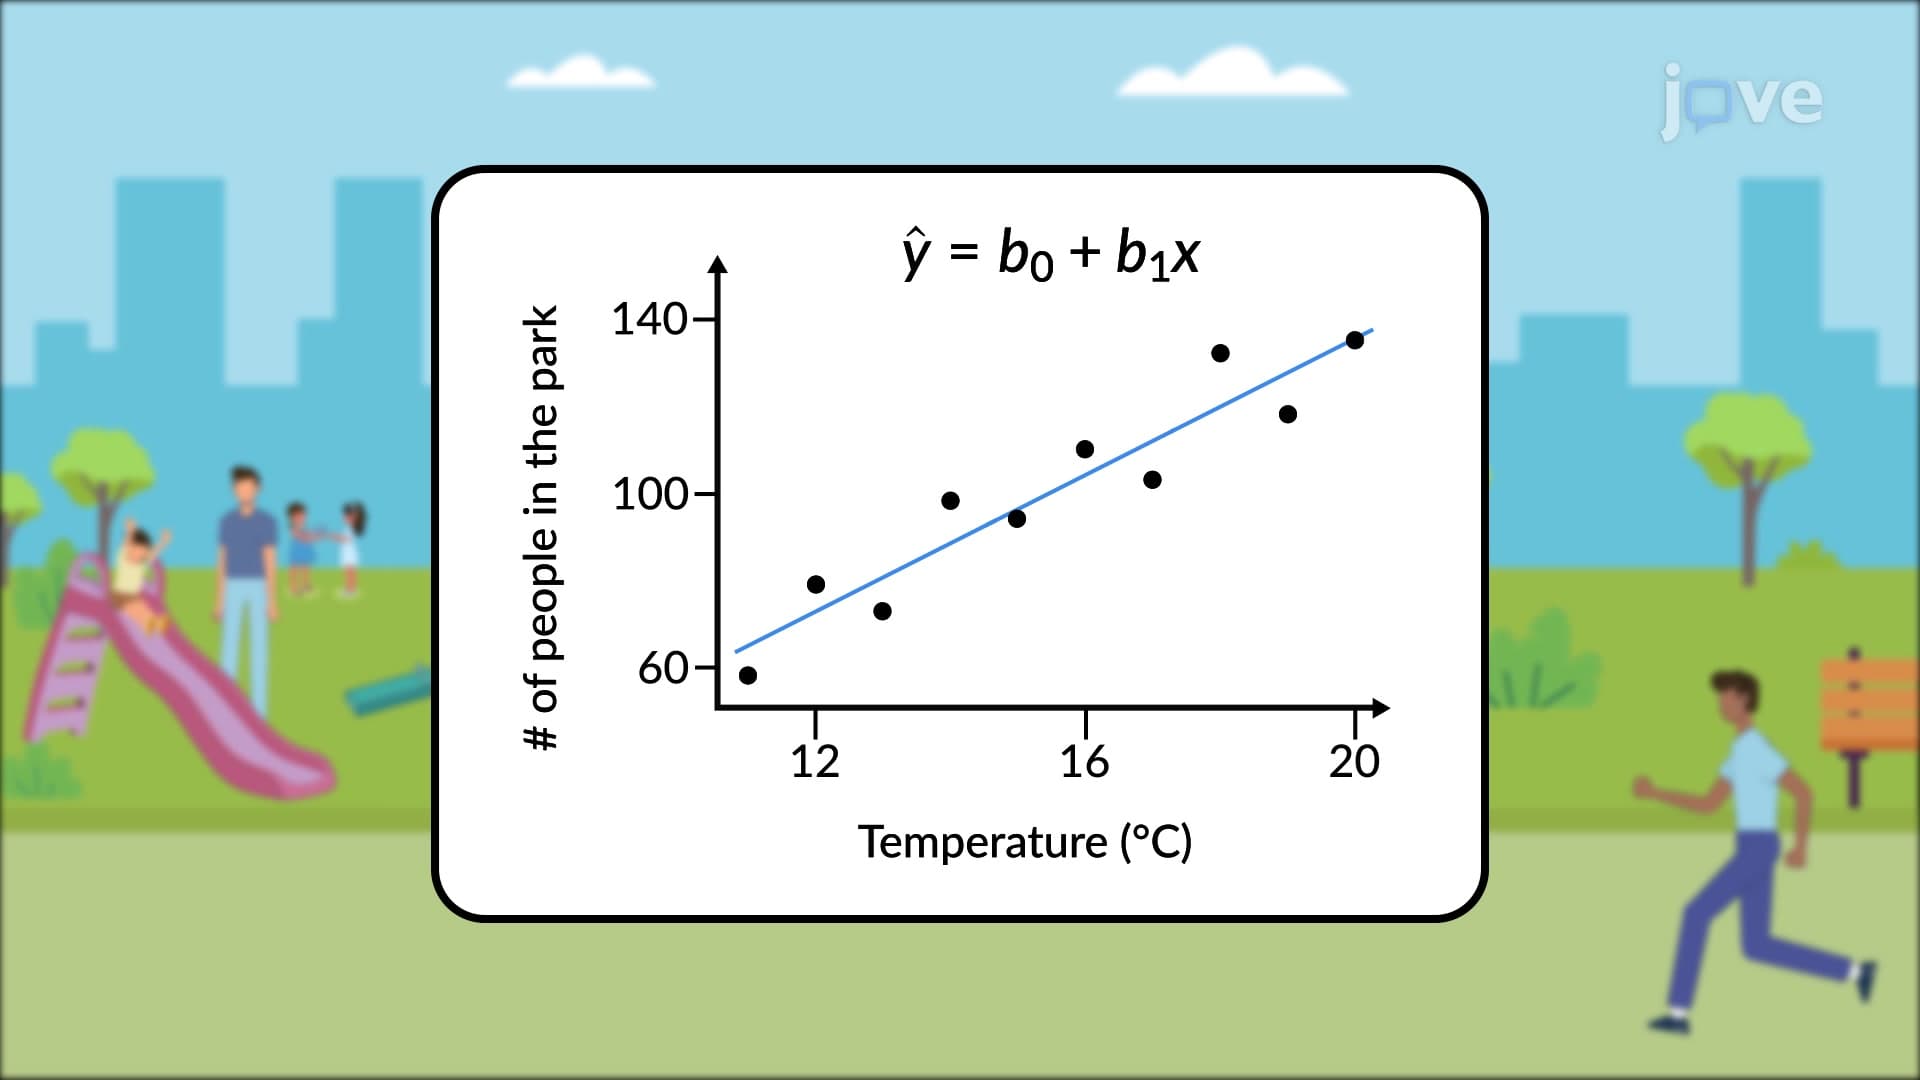
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
7.2K