

联合学习的风险是歪曲微调特征和表现不佳的稳定性

概括
具有微调 (FT) 的联合学习风险模型的稳定性. 一个新的通用噪音投影 (GNP) 算法增强了稳定性而不会牺牲准确性,改进了联合学习应用程序.
科学领域:
- 机器学习 机器学习
- 人工智能的人工智能
- 数据科学数据科学数据科学
背景情况:
- 联合学习 (FL) 与微调 (FT) 结合,解决了特定领域数据集中的数据稀缺性和隐私问题.
- 然而,FL可以通过歪曲FT特征,对预训练模型的分布外 (OOD) 稳定性产生负面影响.
研究的目的:
- 调查联合学习对模型稳定性的影响.
- 提出一种新的算法,以减轻这些负面影响并增强模型的稳定性.
主要方法:
- 引入了三个可靠性指标来分析数据表示,可转移性和模型偏差.
- 开发了一个基于一般噪音投影 (GNP) 的强大算法.
- 包括从预训练到微调模型的强度转移,并添加了高斯噪声.
主要成果:
- 联合学习被发现有风险歪曲FT特征并损害OOD的稳定性.
- 拟议的GNP算法有效地提高了各种场景中的模型稳定性.
- 该方法保持了目标分布的准确性,同时提高了对标签和数量分布偏差的稳定性.
结论:
- 联合学习对模型稳定性,特别是OOD稳定性提出了挑战.
- 全国普惠算法提供了一种可行的解决方案,可以在不降低性能的情况下提高联邦微调的稳定性.
- 该方法支持各种参数效率高的FT技术和不同的数据分布偏差.

相关概念视频
 01:09
Types of Skewness
12.6K
If the frequency distribution of a data set is more inclined towards smaller or larger values, the distribution is said to be skewed. If data values are skewed to the right, then the distribution is called positively skewed. Conversely, if the plot is skewed to the left, the distribution is called negatively skewed.
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
12.6K
 01:19
Survival Tree
164
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
164
 01:06
Skewness
12.7K
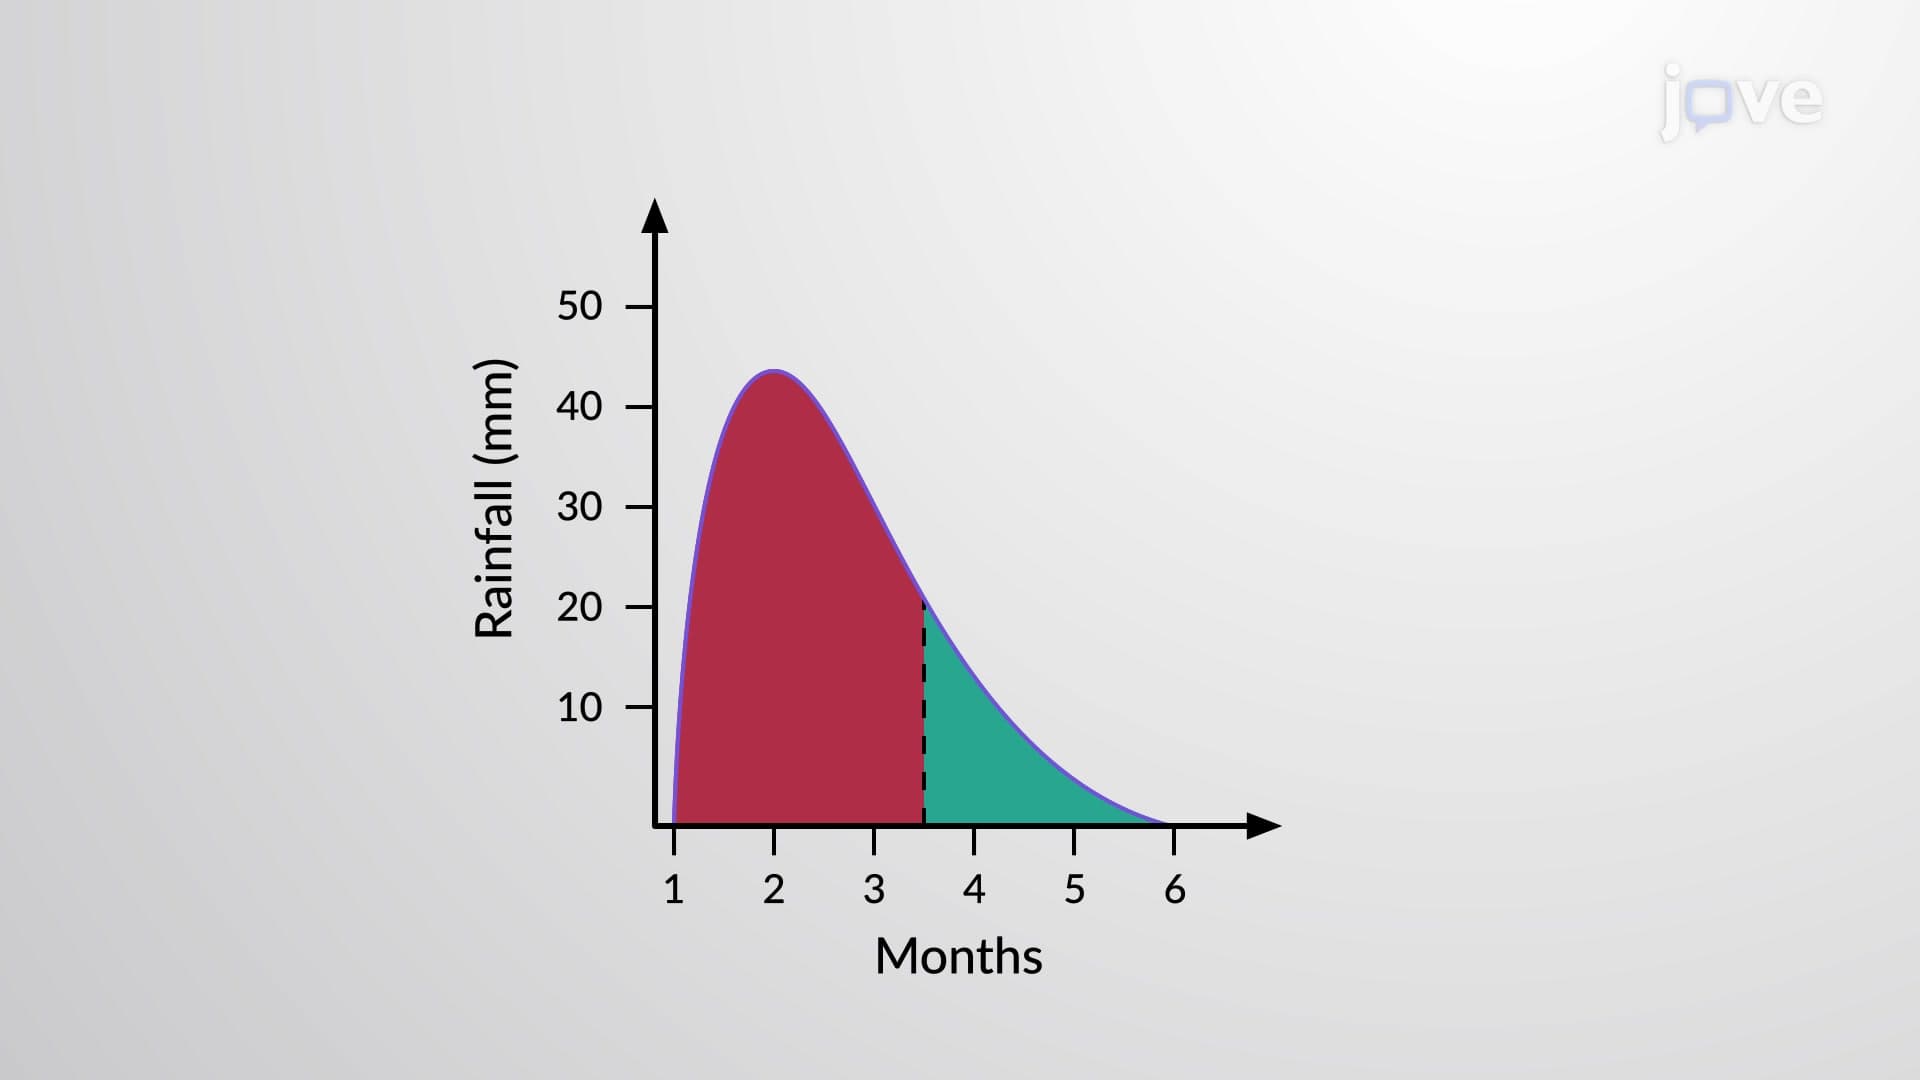
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
12.7K
 02:07
Improving Translational Accuracy
11.9K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
11.9K
 01:52
Regression Toward the Mean
6.5K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.5K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K