

基于机器学习的学术成绩预测,可用于教育机构中增强决策的解释性
Wesam Ahmed1, Mudasir Ahmad Wani2, Pawel Plawiak3,4
1Department of Information Technology, Faculty of Computers and Artificial Intelligence, Hurghada University, Hurghada, Egypt.
Scientific reports
|July 24, 2025

概括
本研究使用机器学习 (ML) 和集体投票回归 (VR) 来预测学业绩. 虚拟现实模型在各种数据集中预测学生成绩方面表现出卓越的准确性,为教育策略提供了有价值的见解.
科学领域:
- 教育技术的教育技术
- 机器学习在教育中的应用
- 高等教育中的数据科学
背景情况:
- 高等教育机构越来越多地使用人工智能来改善教学.
- 预测学术成绩对于大学排名和学生机会至关重要.
- 在绩效分析,质量教育和学生评估方面存在挑战.
研究的目的:
- 开发和评估用于预测学业绩的机器学习模型.
- 在不同的数据集上比较各种回归模型的概括性.
- 确定学生学业成功的关键驱动因素.
主要方法:
- 采用了10种回归模型,包括独立的ML和集合投票回归 (VR) 模型.
- 两个具有不同特征集和大小的数据集被用于模型评估.
- 局部可解释的模型不可知解释 (LIME) 和夏普利添加式解释 (SHAP) 用于模型的可解释性.
主要成果:
- 在独立的ML模型中,线性回归表现最好.
- 拟议的整体VR模型在两个数据集上都实现了卓越的性能.
- 虚拟现实模型在第一个数据集上实现了0.9890的R2,在第二个数据集上达到0.7716.
- 虚拟现实模型在不同的学术环境中表现出了强度和适应性.
结论:
- 机器学习,特别是集体虚拟现实,为预测学业成绩提供了一种强大的方法.
- 该研究为教育工作者和政策制定者提供了可操作的见解,以提高教育战略.
- 以数据为基础的决策可以提高学生支持和机构效率.

相关概念视频
 01:19
Variation
7.2K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
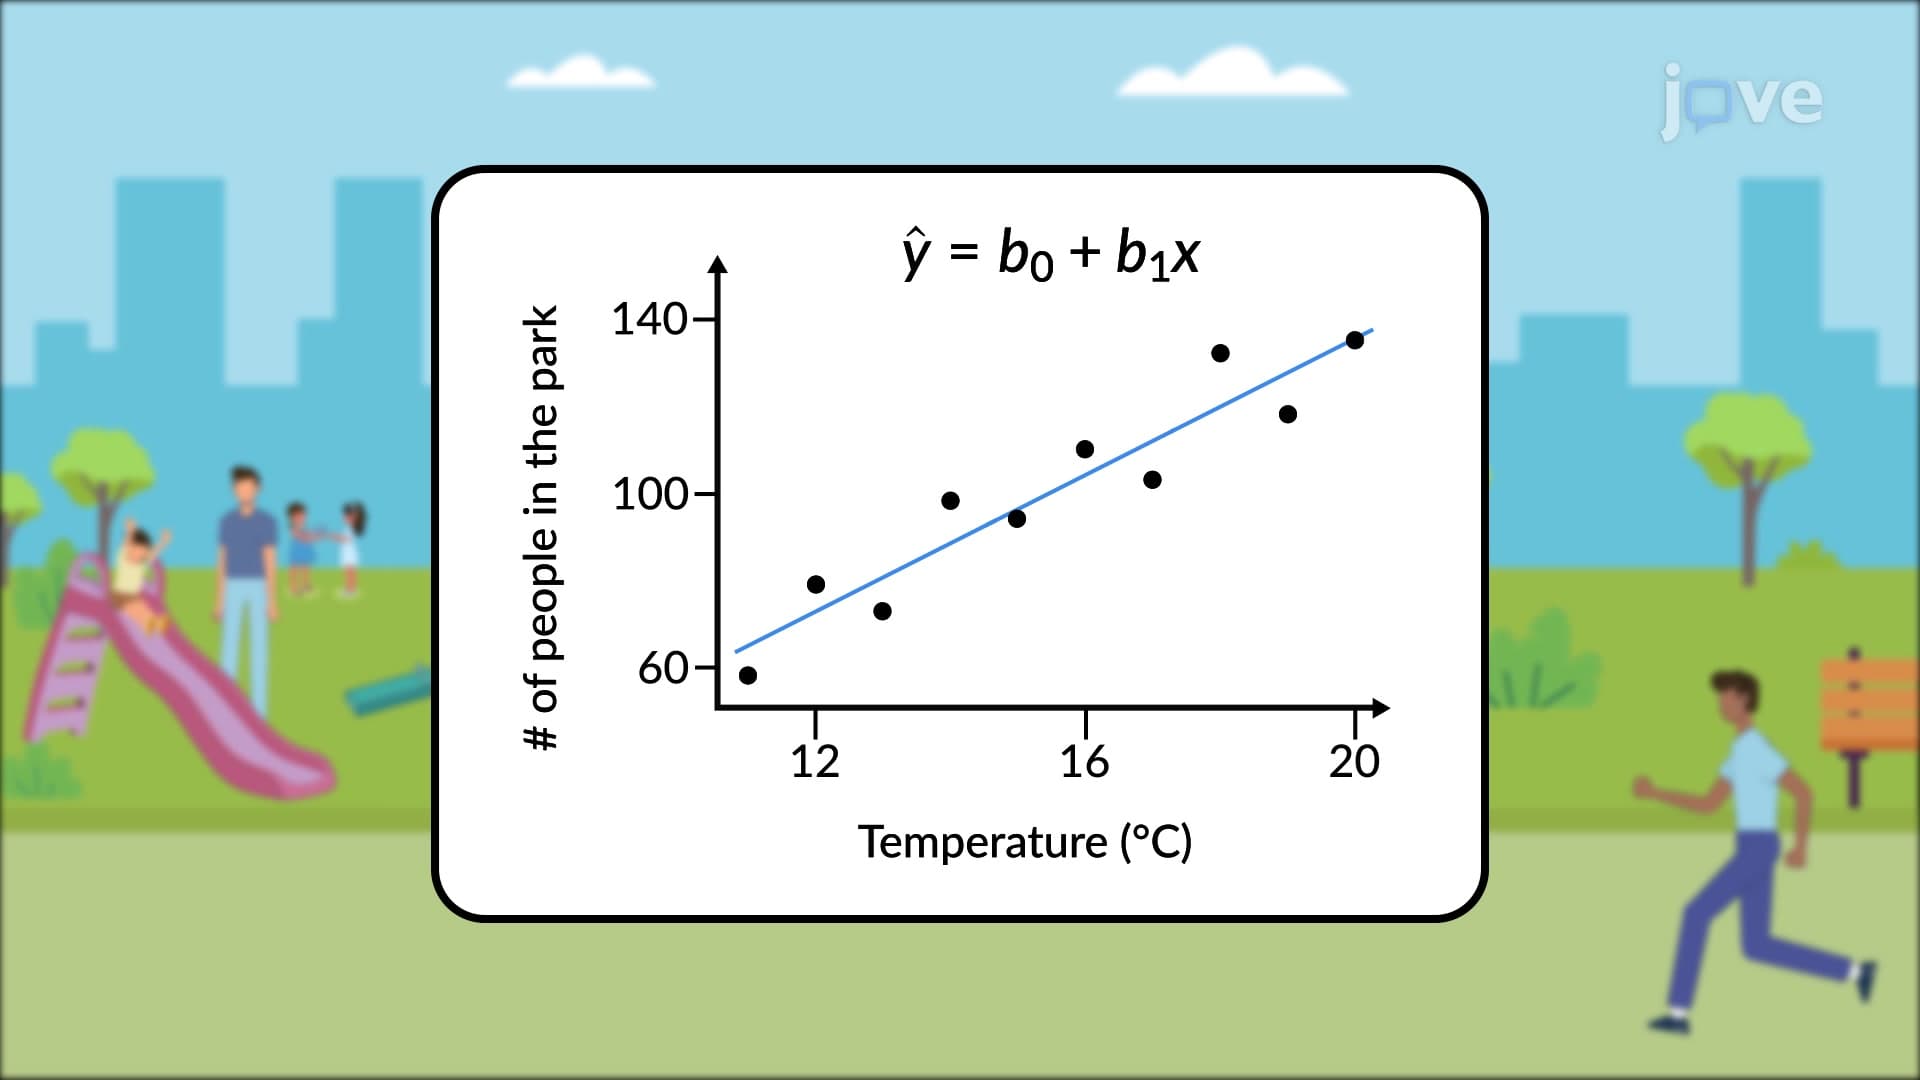
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
7.2K
 01:25
Multiple Regression
3.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.2K
 01:29
Reliability and Validity
13.2K
Reliability and validity are two important considerations that must be made with any type of data collection. Reliability refers to the ability to consistently produce a given result. In the context of psychological research, this would mean that any instruments or tools used to collect data do so in consistent, reproducible ways.
13.2K
 01:12
Hindsight Biases
3.9K
Hindsight bias leads you to believe that the event you just experienced was predictable, even though it really wasn’t. In other words, you knew all along that things would turn out the way they did. Can you relate this to the phrase "Hindsight is 20/20" now?
3.9K
 01:08
Outliers and Influential Points
4.2K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.2K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K