
什么是异常值-一致的异常值或不一致的异常值?
1Department of Applied Chemistry School of Science and Technology Meiji University Kawasaki Kanagawa Japan.
Analytical science advances
|July 28, 2025

概括
本研究引入了回归分析中异常值样本的新分类:一致的异常值 (CO) 和不一致的异常值 (ICO). 一种新的方法有效地区分了CO和ICO,使机器学习和材料设计中更好地利用数据.
科学领域:
- 数据科学数据科学数据科学
- 机器学习 机器学习
- 计算化学的计算化学
背景情况:
- 在回归分析中的异常样本可以显著影响模型性能.
- 像坏杆和垂直异常值这样的现有分类不能完全捕捉异常值的行为.
研究的目的:
- 将异常值样本分为一致的异常值 (CO) 和不一致的异常值 (ICO).
- 开发一种方法,有效地利用异常样本进行回归分析.
- 提出一个指数来识别不一致的异常值.
主要方法:
- 根据解释变量和依赖变量的关系,将异常值分为CO和ICO.
- 开发使用三重交叉验证和平均绝对误差的ICO相似性指数.
- 使用数值模拟和复合数据集 (沸点) 的验证.
主要成果:
- 一种新的方法有效地区分了CO和ICO.
- 拟议的ICO相似度指数有助于识别异常情况.
- 提供了处理ICO (错误检查,添加新变量) 和CO (外推) 的指导方针.
结论:
- 新的分类和歧视方法提高了对异常样本的理解和利用.
- 有效处理异常值可以提高回归模型在各种科学领域的准确性和适用性.
更多相关视频
相关概念视频
 01:08
Outliers and Influential Points
4.2K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.2K
 01:12
What Are Outliers?
4.2K
Outliers are observed data points that are far from the least squares line. They have unusual values and need to be examined carefully. Though an outlier may result from erroneous data, at other times, it may hold valuable information about the population under study and should be included in the data. Hence, it is crucial to examine what causes a data point to be an outlier.
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
4.2K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
2.1K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
2.1K
 01:00
Detection of Gross Error: The Q Test
6.4K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.4K
 00:57
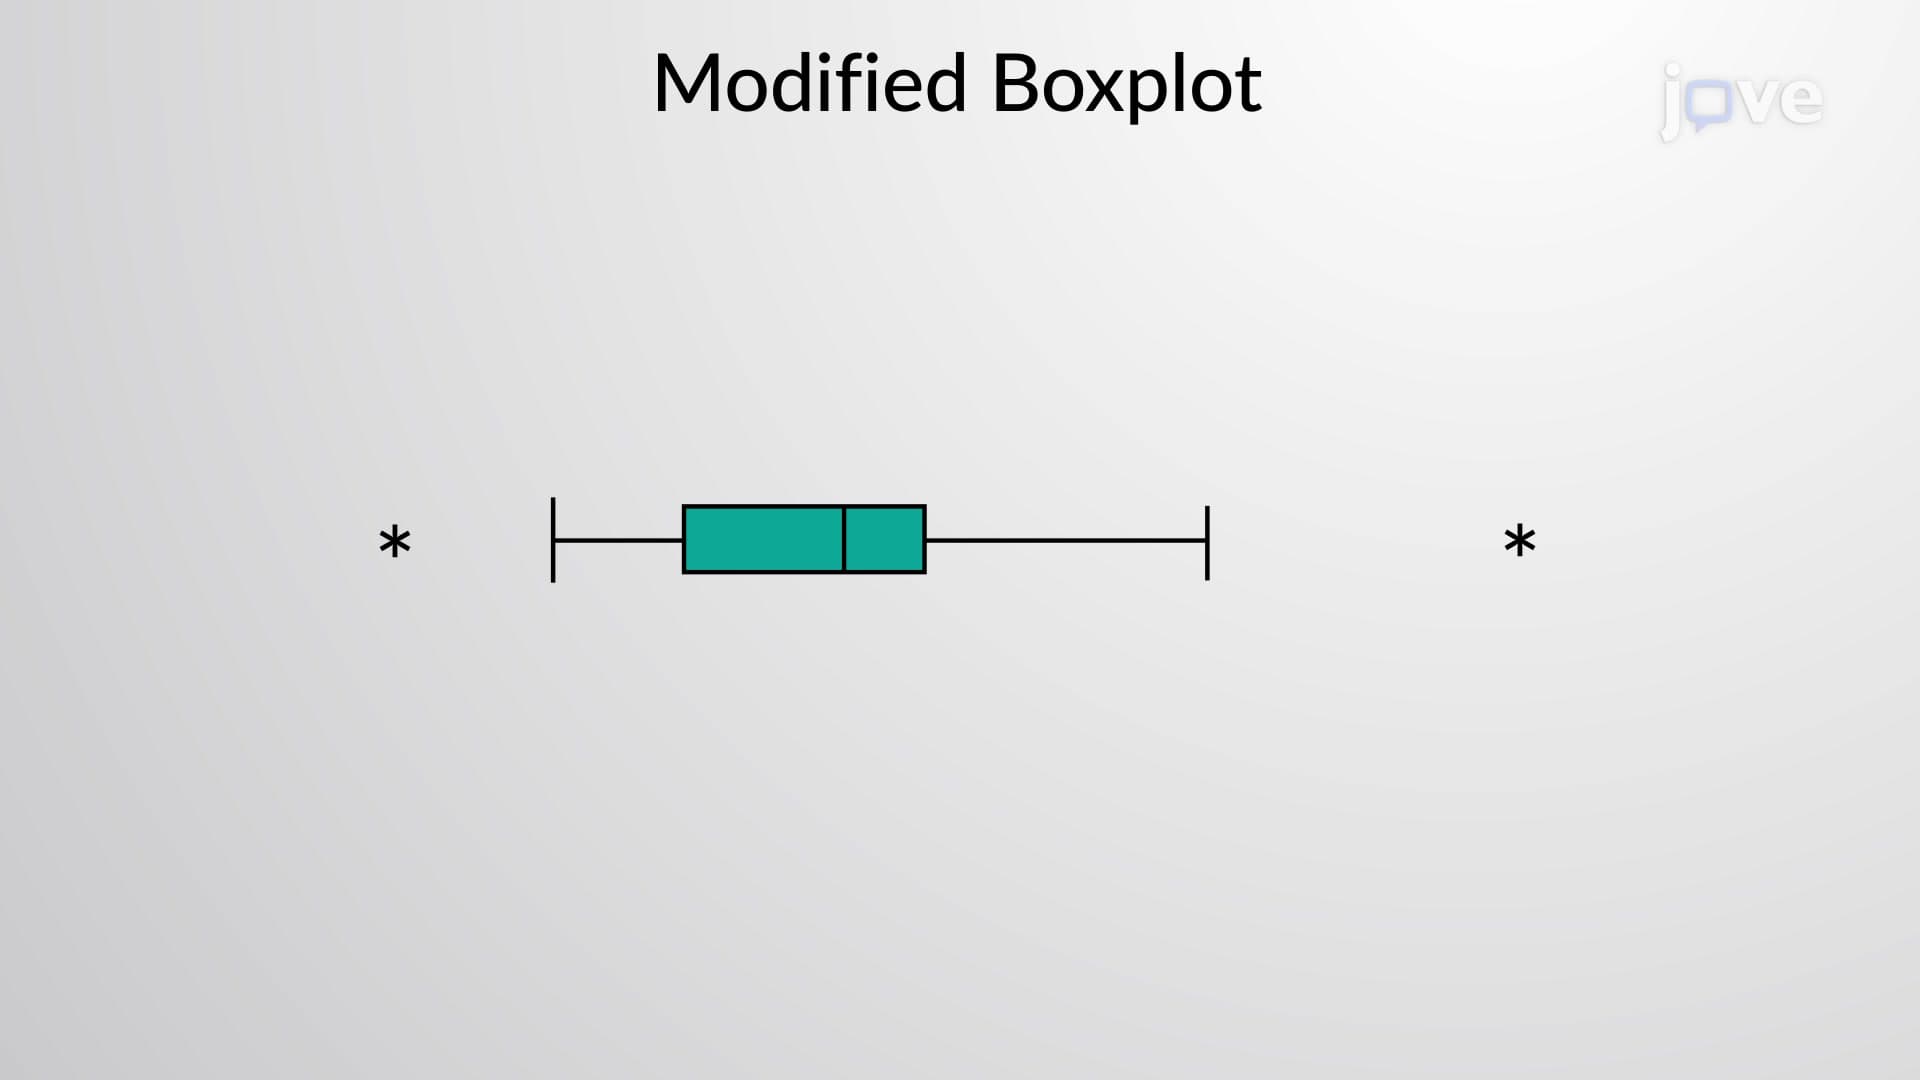
Modified Boxplots
10.1K
A standard box and whisker plot informs us about the spread of the data in a given sample. One can identify the minimum value, maximum value, first quartile value, second quartile or median value, and third quartile.
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
10.1K
 01:52
Regression Toward the Mean
6.5K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.5K