
信息 - 内容 - 信息 - 肯德尔 - 陶关联方法:将缺失的值解释为有用的信息
Robert M Flight1,2,3, Praneeth S Bhatt4, Hunter Nb Moseley1,2,3,5,6
1Markey Cancer Center, University of Kentucky, Lexington, KY 40536, USA.
bioRxiv : the preprint server for biology
|August 8, 2025

概括
本研究引入了信息-内容-信息的肯德尔-tau (ICI-Kt) 方法,以整合omics数据中的左边被审查的缺失值. 这种方法将缺少的数据视为信息,改进相关性分析和生物数据集中的网络构建.
科学领域:
- 生物信息学是一种生物信息学.
- 计算生物学 计算生物学
- 统计遗传学 统计遗传学
背景情况:
- 传统的相关性测量通常会忽略或归咎于缺失的数据,从而丢失有价值的信息.
- 在omics数据中缺失的值,特别是低于检测极限的左边审查值,不是随机的,并且包含有用的信息.
- 现有的方法无法利用从分析测量中缺少的数据中固有的信息.
研究的目的:
- 开发一种新的方法,即信息内容信息的Kendall-tau (ICI-Kt),将左边审查的缺失值集成到相关性分析中.
- 展示ICI-Kt如何将缺少的数据重新解释为信息,增强相关系数计算.
- 为改进异常值检测提供工具,并在omics研究中提供特征网络构建.
主要方法:
- 开发了信息-内容-信息的肯达尔-tau (ICI-Kt) 方法.
- 整合左边被审查的缺失值到肯德尔-陶相关系数定义中.
- 实现了理论最大值和对完全性的计算,以提高解释能力.
- 使用模拟和真实世界的RNA-seq,代谢学和脂质学数据验证了方法.
主要成果:
- ICI-Kt方法成功地将左边被审查的缺失数据作为可解释的信息.
- 使用ICI-Kt.证明了异常值样本的改进确定.
- 在omics数据集中展示了增强的功能-功能网络构建.
- 通过R和Python对大型数据集的并行实现,实现了快速计算.
结论:
- ICI-Kt方法提供了一种强大的方法来处理omics中的左边审查的缺失数据.
- 这种方法通过利用所有可用的数据来提高相关性分析的解释性.
- 开源的R和Python软件包可供广泛采用和应用.

相关概念视频
 01:16
Kendall's Tau Test
820
Kendall's tau test, also known as the Kendall rank coefficient test, is a nonparametric method for assessing association between two variables. This test is particularly useful for identifying significant correlations when the distributions of the sample and population are unknown. Developed in 1938 by the British statistician Sir Maurice George Kendall, the tau coefficient (denoted as τ) serves as a rank correlation coefficient, with values ranging from -1 to +1.
A τ value...
A τ value...
820
 01:20
Kendall's Coefficient of Concordance
531
Kendall's Coefficient of Concordance (W), also known as Kendall's W, is a non-parametric statistical measure used to assess the agreement or concordance between multiple raters or judges when they rank a set of items. It is often used when you have ordinal data (ranks) and you want to see if there is consistency or consensus among the raters. It is widely applied in research areas such as psychology, medicine, and social sciences, where multiple judges are asked to rank or rate subjects...
531
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
6.4K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable, x, and the dependent variable, y. Hence, it is also known as the Pearson product-moment correlation coefficient. It can be calculated using the following equation:
6.4K
 00:53
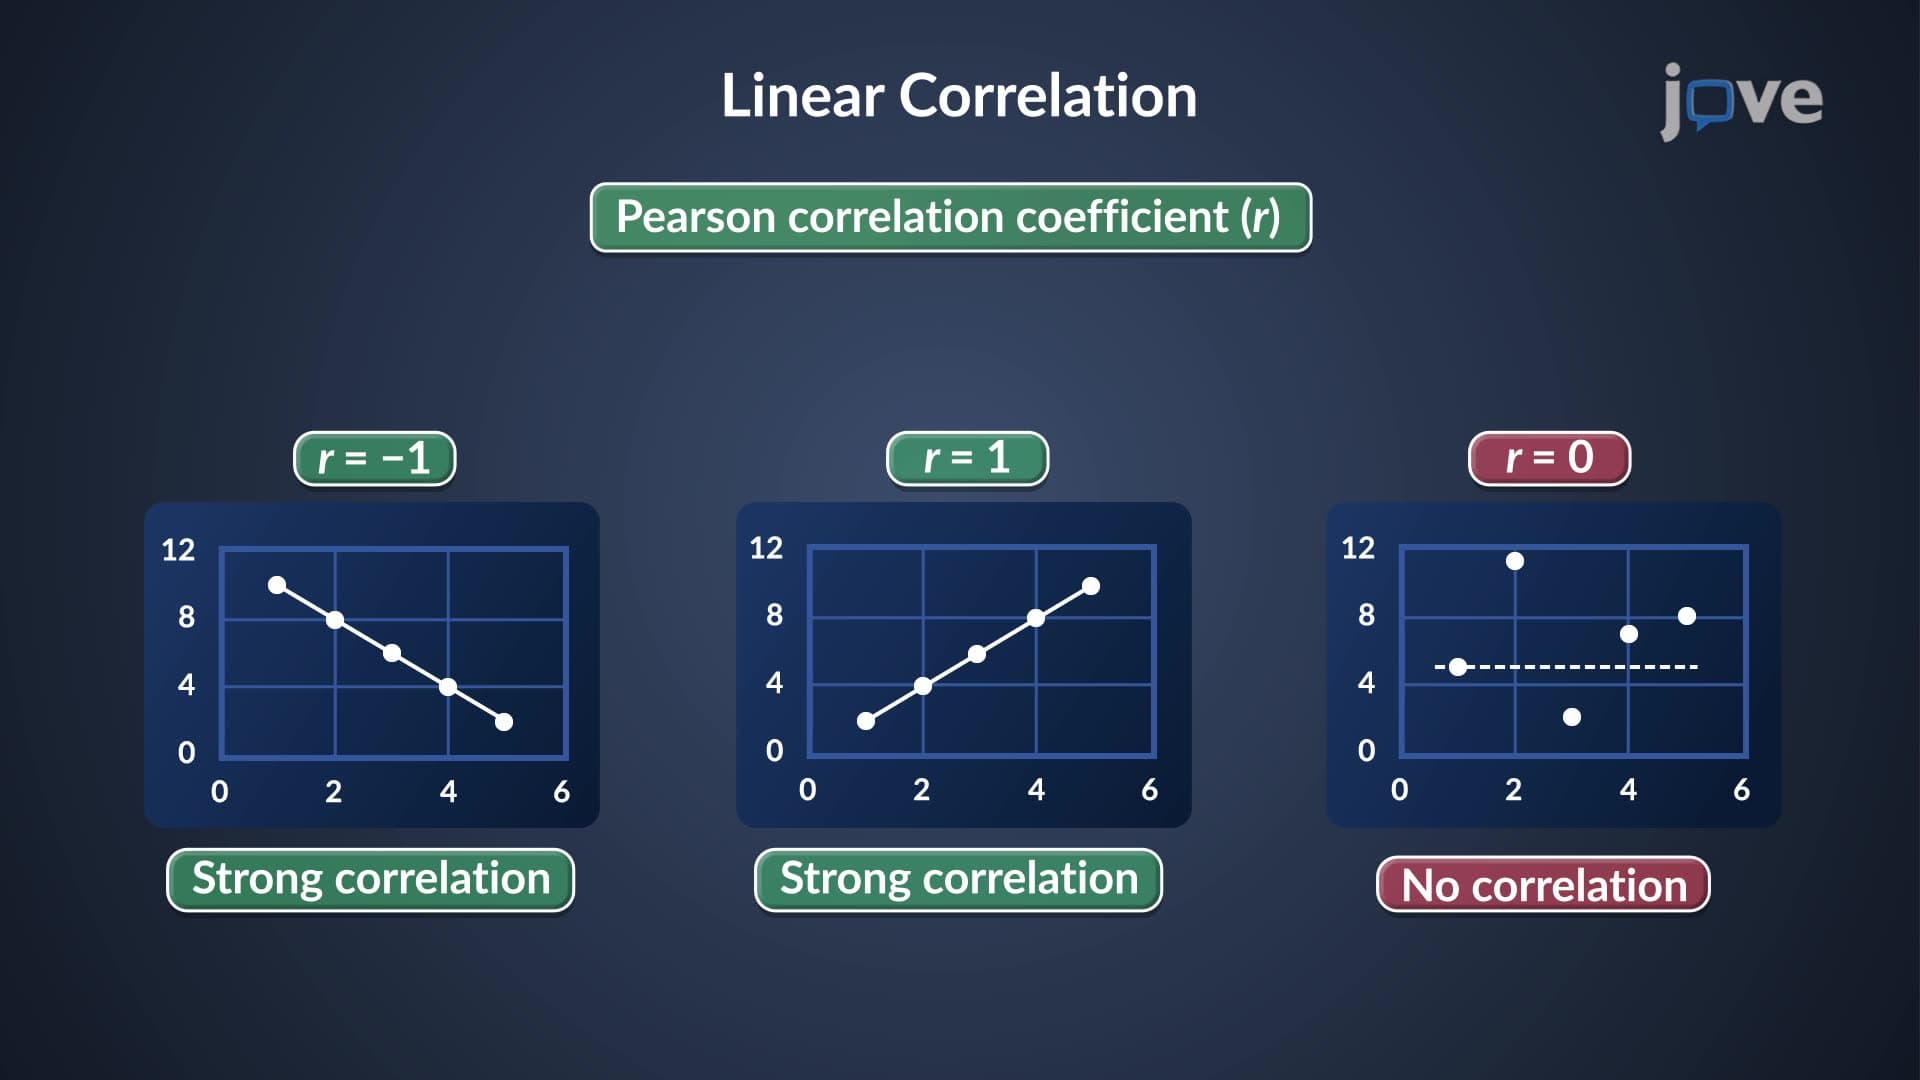
Correlation and Regression
1.9K
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
1.9K
 01:12
Coefficient of Correlation
6.4K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable x and the dependent variable y.
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
6.4K
 01:00
Detection of Gross Error: The Q Test
6.4K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.4K