
高可信度目击者识别的错误率
Ryan J Fitzgerald1, Ira E Hyman2, Kimberley A Wade3
1Department of Psychology, Simon Fraser University, Burnaby, Canada.
Memory (Hove, England)
|August 19, 2025

概括
目击者识别错误很常见,即使信任度很高. 一项元分析发现,八分之一的高可信度识别是错误的,这凸显了刑事调查中目击证人的证词的不可靠性.
科学领域:
- 心理学 心理学 心理学
- 法医科学 法医科学 法医科学
- 刑事司法 刑事司法 刑事司法
背景情况:
- 目击者鉴定是刑事调查的关键组成部分.
- 对初始识别的高度信心并不能保证准确性.
- 现有的错误定罪数据往往缺乏初步的目击者信任度.
研究的目的:
- 对目击者识别准确性的现场数据进行元分析.
- 评估高可信度目击者鉴定的错误率.
- 探索导致目击者错误识别的因素.
主要方法:
- 对实际刑事调查数据的元分析.
- 包括使用盲目阵容管理员的研究.
- 审查在不同偏差条件下检查高可信度识别错误率的实验室研究.
主要成果:
- 在实地研究中,12.5% (8分之一) 的高可信度识别是错误的.
- 实验室研究表明,高可信度的错误率可以在0%到40%之间.
- 怀疑偏见,包括基于外表的怀疑,社交媒体污染和错误的先前熟悉度,影响了错误率.
结论:
- 目击者识别陌生人容易出错,无论最初的信心如何.
- 盲目管理员的现场数据为真实世界的识别可靠性提供了关键的见解.
- 了解和减轻嫌疑人的偏见对于提高目击者识别准确度至关重要.
相关概念视频
 01:22
Eyewitness Memory
160
Eyewitness memory refers to the recollection of events by someone who has directly witnessed them, often serving as critical evidence in legal settings. This type of memory is commonly used in criminal cases where a witness describes details like a suspect's appearance, clothing, or behavior during a crime. However, despite its perceived reliability, eyewitness memory is prone to significant errors.
One such error is memory distortion, which occurs because human memory does not function...
One such error is memory distortion, which occurs because human memory does not function...
160
 01:13
Accuracy and Errors in Hypothesis Testing
282
Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
282
 01:19
Interpretation of Confidence Intervals
6.5K
A confidence interval is a better estimate of the population than a point estimate, as it uses a range of values from a sample instead of a single value.
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
6.5K
 01:24
Confidence Coefficient
7.8K
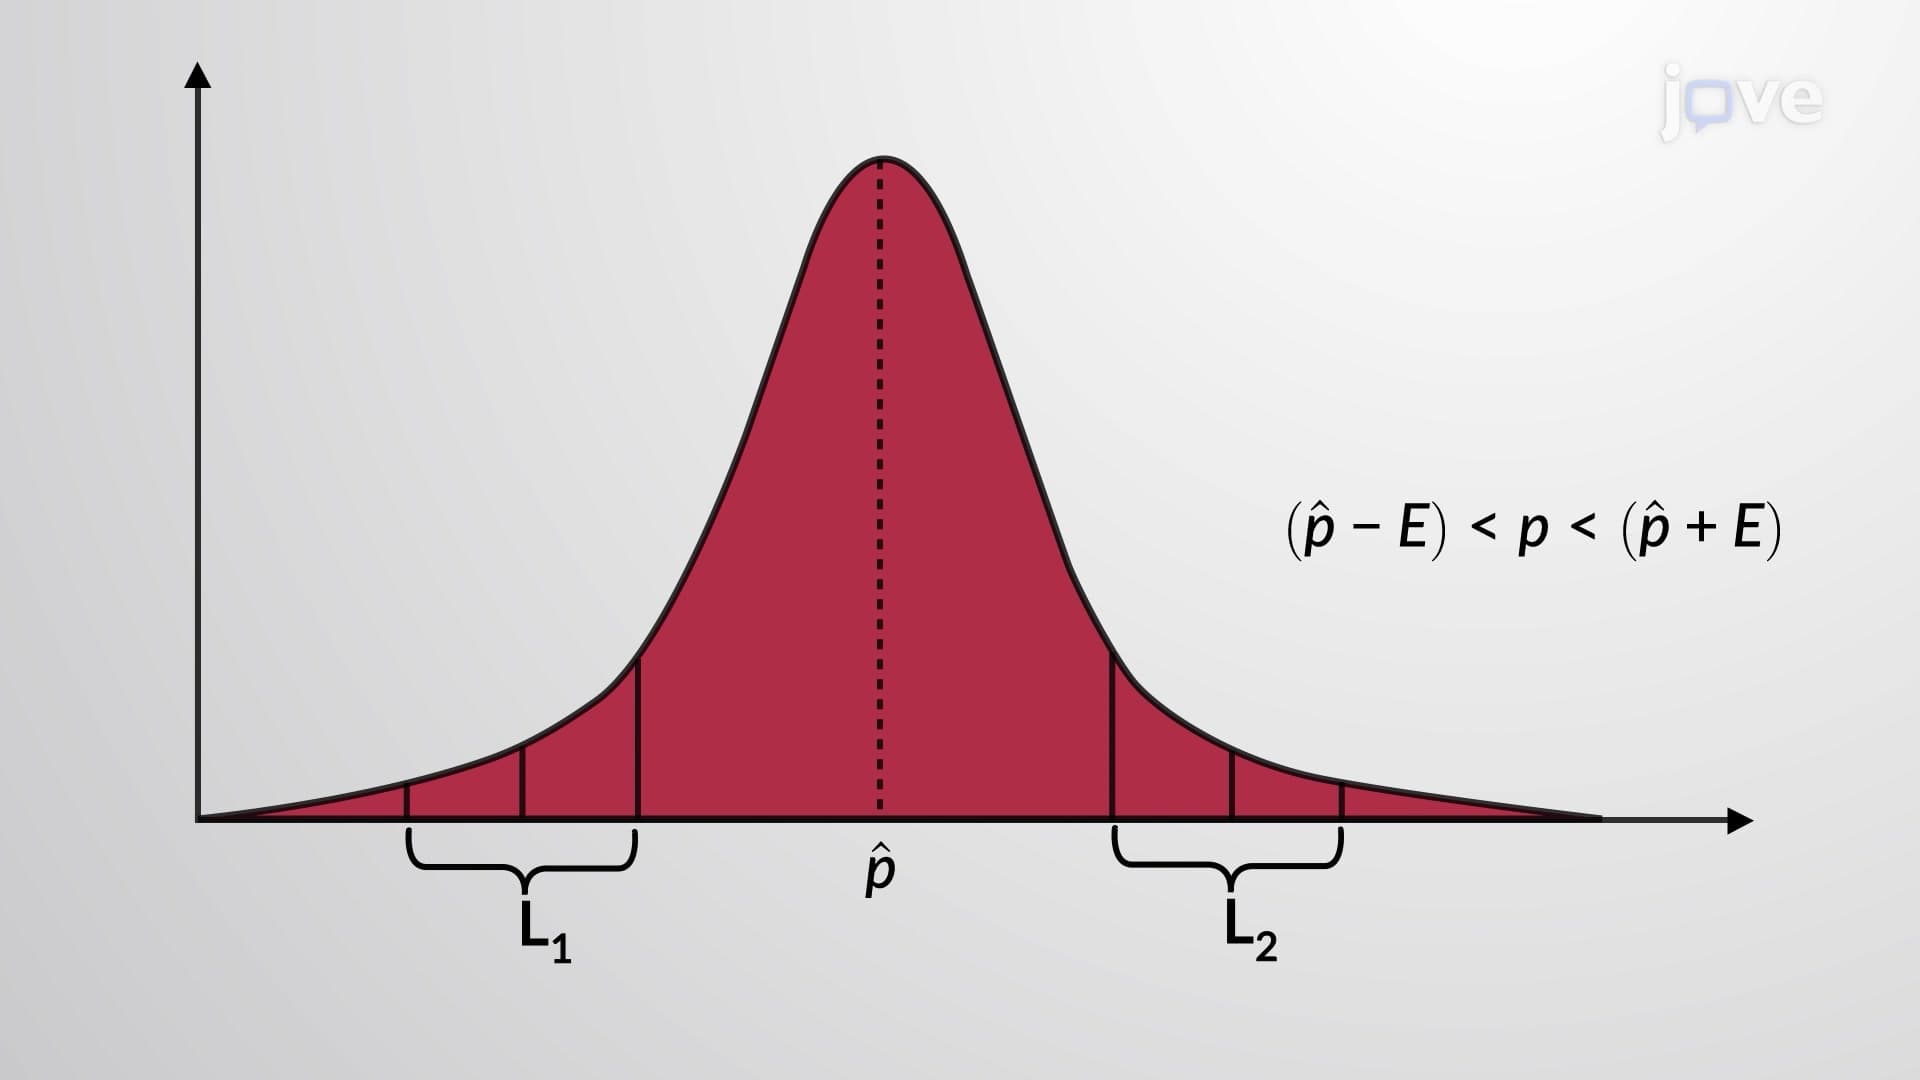
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.8K
 01:31
Confirmation Biases
7.2K
The confirmation bias is the tendency to focus on information that confirms our existing beliefs and ignore information that is inconsistent with our expectations. For example, if you think that your professor is not very nice, you notice all of the instances of rude behavior exhibited by the professor while ignoring the countless pleasant interactions he is involved in on a daily basis. Have you ever fallen prey to the confirmation bias, either as the source or target of such bias?
7.2K
 01:27
Margin of Error
4.5K
The margin of error is also called the maximum error of an estimate. The margin of error is the maximum possible or expected difference between the observed sample parameter value and the actual population parameter value. For proportion, it is the maximum difference between the value of sample proportion obtained from the data and the true value of population proportion. As the true value of the population parameter is not known, the margin of error is calculated using the sample statistic.
4.5K