
人工神经网络和多重线性回归的比较,以预测大米中的度:中国广西的一项现场研究
Junyang Zhao1, Fuhai Zheng2, Baoshan Yu1
1Guangxi Key Laboratory of Agro-Environment and Agric-Products Safety, College of Agriculture, Guangxi University, Nanning 530004, China.
Toxics
|August 27, 2025

概括
我们开发了两种模型来预测大米中的 (Cd). 反向传播人工神经网络 (BP-ANN) 模型在预测大米含量方面表现比多重线性回归 (MLR) 模型更好.
科学领域:
- 环境科学 环境科学
- 农业科学 农业科学
- 土壤科学 土壤科学
背景情况:
- 土壤-大米系统中的 (Cd) 转移是复杂的,限制了当前土壤-植物模型的有效性.
- 准确预测大米中的Cd含量对于食品安全和风险评估至关重要.
研究的目的:
- 为了比较反向传播人工神经网络 (BP-ANN) 模型和多重线性回归 (MLR) 模型的预测性能,用于估计米粒中的含量.
- 确定影响大米中积累的关键土壤参数.
主要方法:
- 利用486个配对的土壤和大米谷物样本进行培训和验证,以及另外30个来自广西省的样本进行测试.
- 使用土壤可用 (ACd),土壤总 (TCd),土壤有机物 (SOM) 和pH作为预测变量.
- 使用根平均平方误差 (RMSE),相对百分比差异 (RPD) 和相关系数 (R2) 评估模型性能.
主要成果:
- 使用pH,TCd和ACd的MLR模型,实现了0.551的R2,2.398的RPD和0.049的米的RMSE (RCd).
- 使用相同变量的BP-ANN模型,给出了R2的0.6846和RMSE的0.104的RCd.
- 与MLR模型相比,BP-ANN模型显示出更高的预测准确性.
结论:
- 反向传播人工神经网络 (BP-ANN) 模型对预测米中的含量是有效的.
- 与传统的多重线性回归 (MLR) 相比,BP-ANN为土壤-大米系统中的预测提供了更好的性能.

相关概念视频
 01:25
Multiple Regression
3.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.2K
 01:11
Regression Analysis
6.0K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
6.0K
 00:53
Correlation and Regression
1.8K
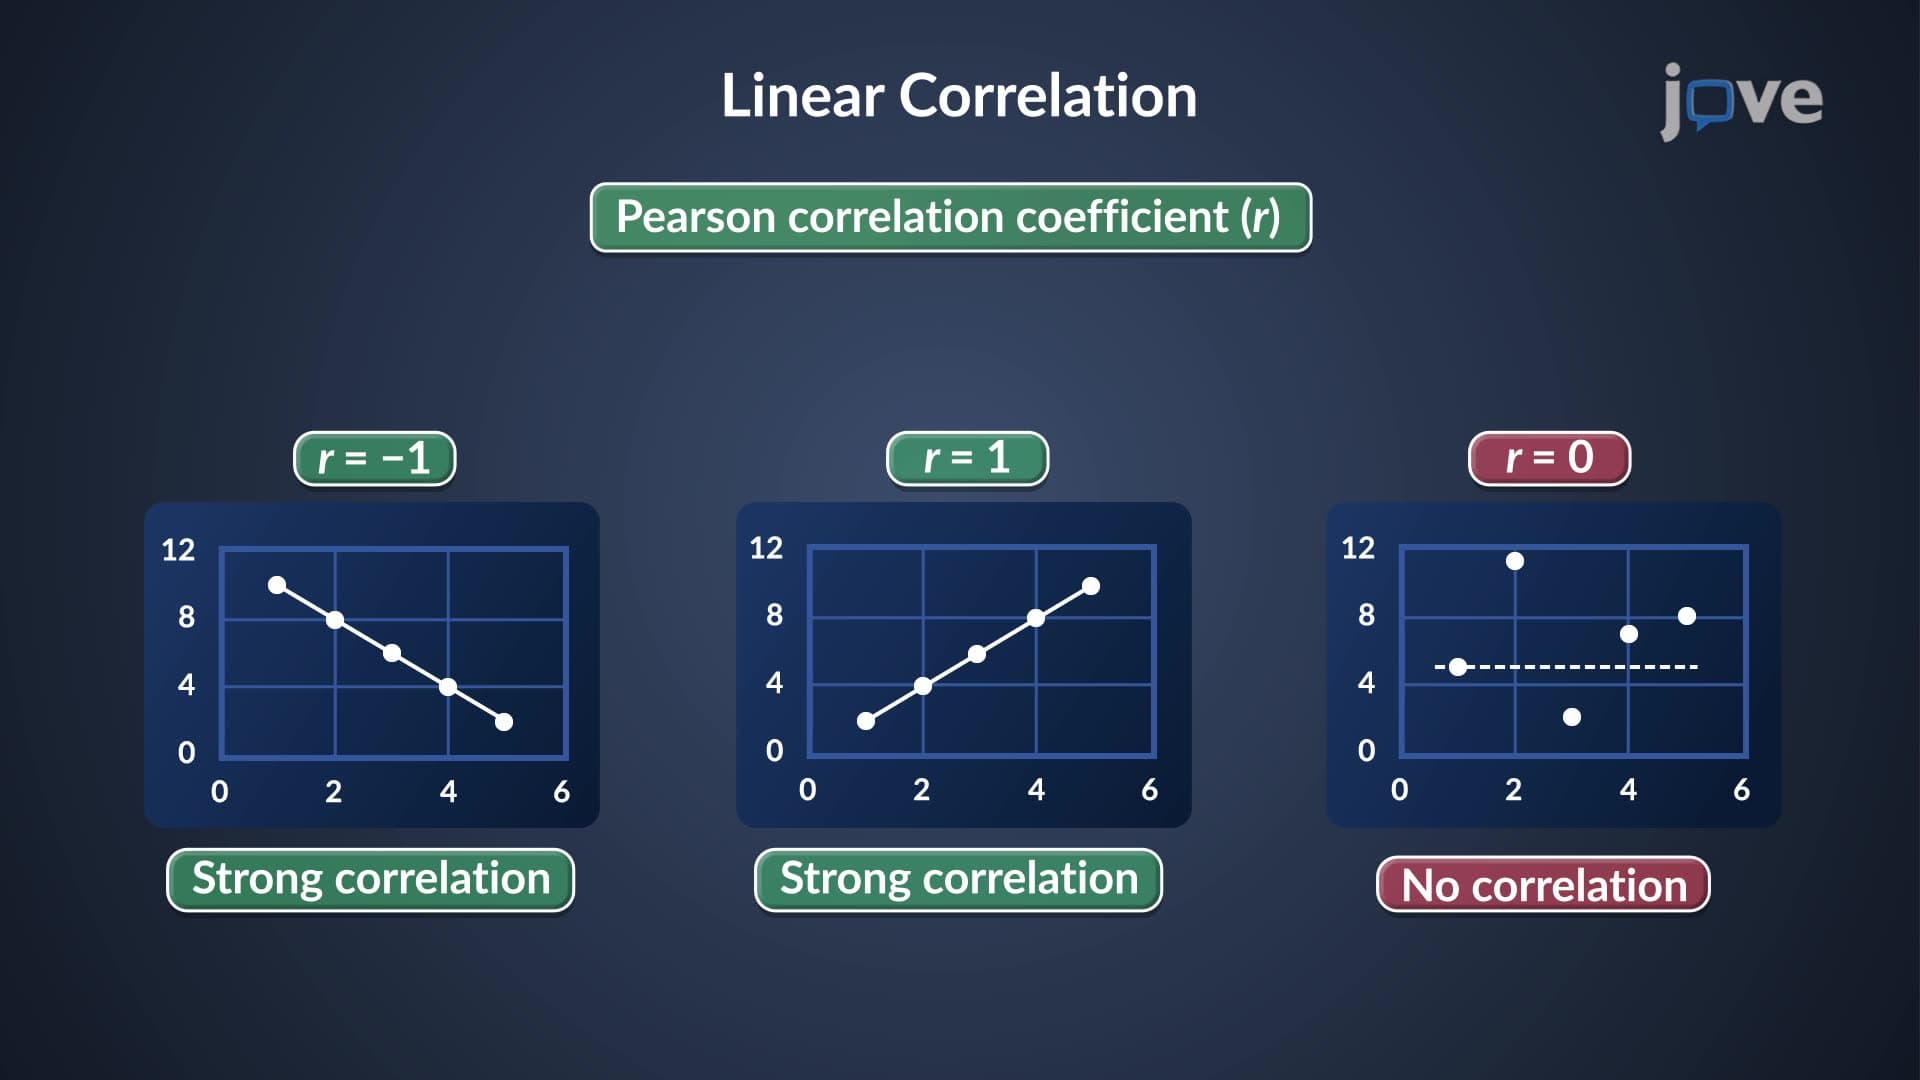
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
1.8K
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
6.4K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable, x, and the dependent variable, y. Hence, it is also known as the Pearson product-moment correlation coefficient. It can be calculated using the following equation:
6.4K