
在二次尺度中的比例解释组件方差:隐性变量建模方法的说明
Tenko Raykov1, Christine DiStefano2, Yusuf Ransome3
1Michigan State University, East Lansing, MI, USA.
Educational and psychological measurement
|August 29, 2025

概括
这项研究引入了一种新方法,以评估行为尺度组件的变异程度是由底层特征解释的. 这一指数补充了现有的测量方法,并提供了评估心理测量尺度的可靠方法.
科学领域:
- 心理测量
- 行为科学
- 统计模型
背景情况:
- 评估行为尺度中潜在特征所解释的差异对于心理测定至关重要.
- 像欧米茄等级系数这样的现有方法在完全捕捉解释差异方面存在局限性.
- 二级因子结构在复杂的行为尺度中很常见.
研究的目的:
- 概述一个程序来评估第二阶层结构的行为尺度中的基本特征所解释的组件方差的比例.
- 引入一种新的指数来补充传统的心理指数.
- 描述这个新指数的点和间隔估计方法.
主要方法:
- 在潜变量建模中使用确认因子分析 (CFA).
- 开发了一种计算尺度组件中解释差异的比例的程序.
- 对拟议的指数采用点和间隔估计技术.
主要成果:
- 建议的指数有效地量化了由底层特征解释的差异比例.
- 该指数作为omega-hierarchical系数和解释组件相关性的信息补充.
- 这种估计方法很实用,可以使用标准的统计软件来实现.
结论:
- 开发的程序为评估行为尺度的心理特征提供了有价值的工具.
- 这一新指数有助于人们更好地了解底层特征如何解释尺度组件的差异.
- 这种方法支持在研究中严格评估尺度可靠性和有效性.
相关概念视频
 01:19
Variation
7.2K
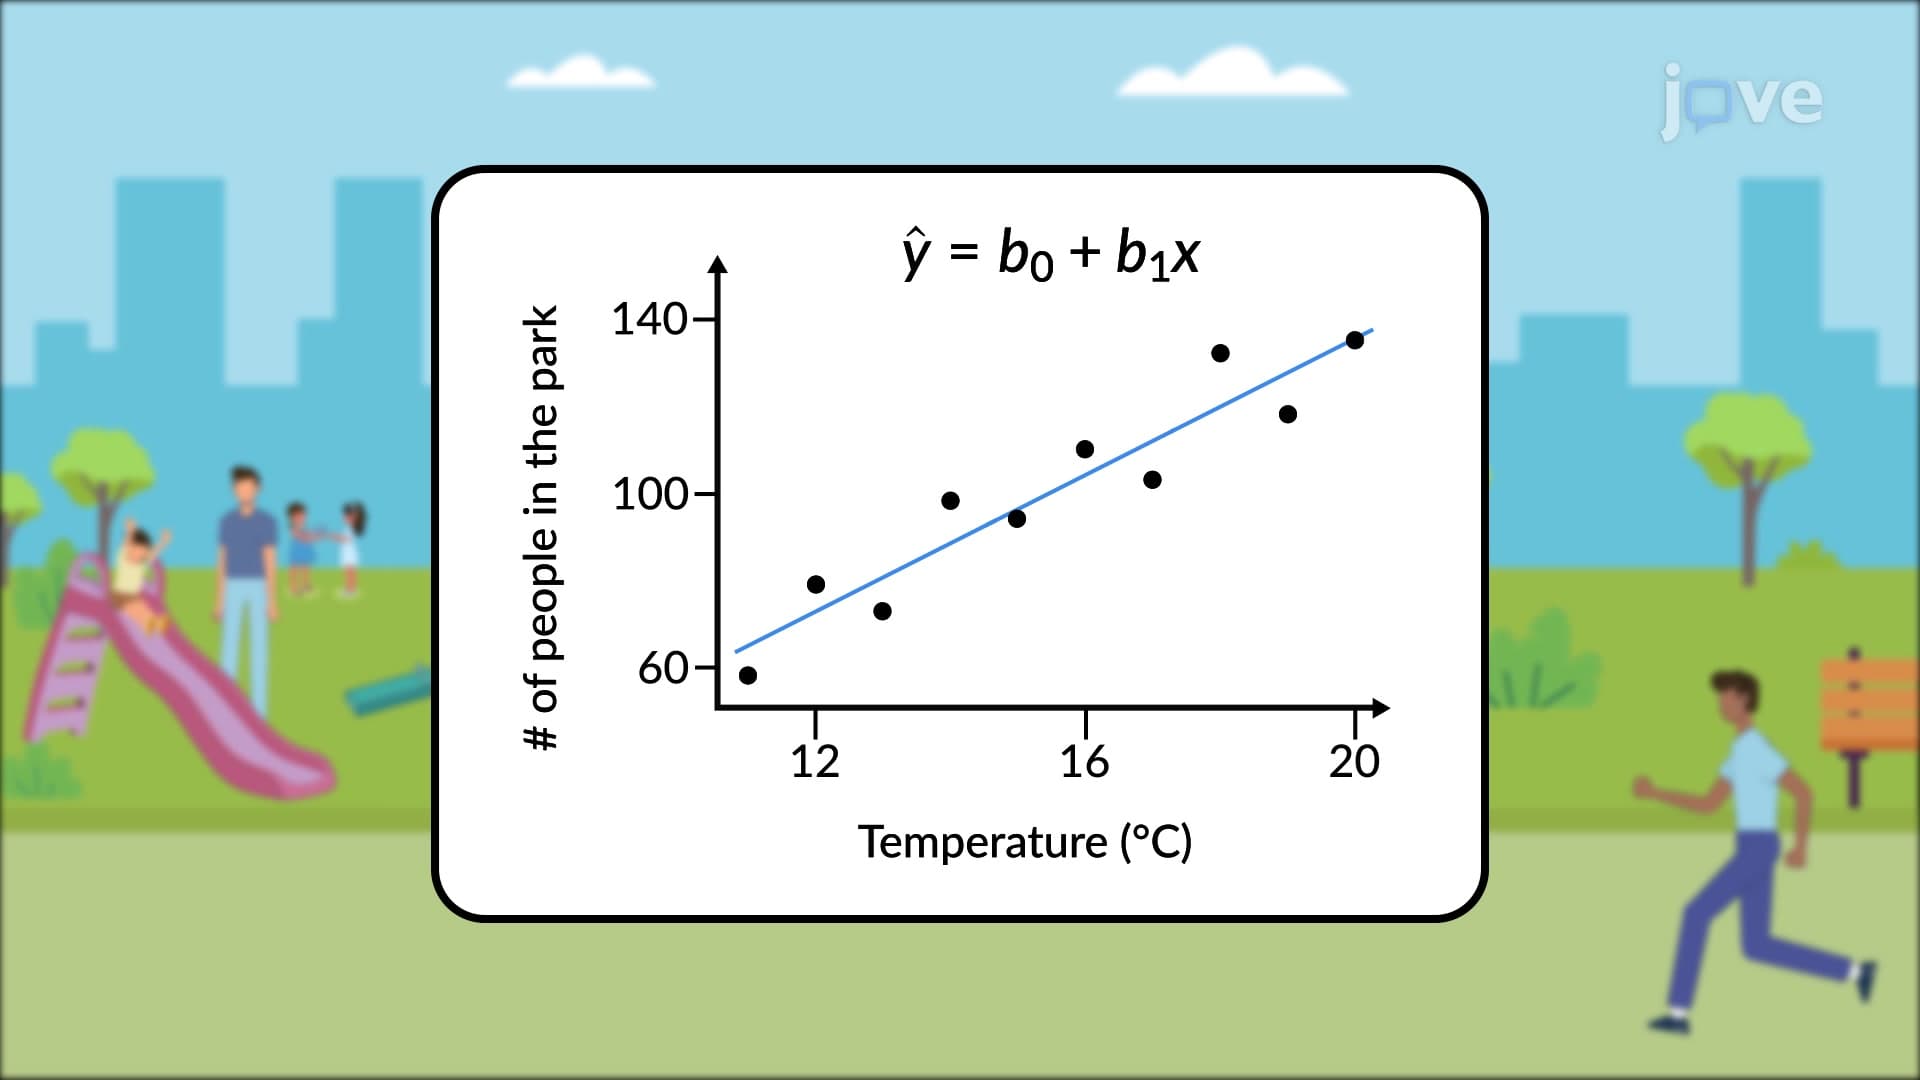
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
7.2K
 01:21
Friedman Two-way Analysis of Variance by Ranks
296
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
296
 01:25
Multiple Regression
3.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.2K
 01:11
Variability: Analysis
189
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
189
 01:17
Two-Way ANOVA
2.8K
The two-way ANOVA is an extension of the one-way ANOVA. It is a statistical test performed on three or more samples categorized by two factors - a row factor and a column factor. Ronald Fischer mentioned it in 1925 in his book 'Statistical Methods for Researchers.'
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the...
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the...
2.8K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
85
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
85