美国学区中K-12学生成绩与家庭收入之间的关联的功能形式
Maria N Wodarz1, Natalia L Komarova2, Timmy Ma3
1University High School, Irvine, California, United States of America.
PloS one
|September 10, 2025

概括
在美国,学生的学业成绩与收入有关. 这项研究揭示了各州家庭收入和K-12学生熟练程度之间的不同数学关系,其中一些显示线性趋势,而另一些则显示和效应.
科学领域:
- 教育研究教育研究
- 社会经济研究是社会经济研究.
- 定量分析是一种量化分析.
背景情况:
- 众所周知,收入与美国K-12学生的学业成绩有相关性.
- 精确的数学关系及其州级变化并未得到充分理解.
研究的目的:
- 量化描述美国公立学校区中家庭收入中位数与K-12学生表现之间的关系.
- 探讨这种关系如何根据州,学科 (英语语言艺术,数学) 和年级水平 (三年级,八年级) 变化.
主要方法:
- 对K-12学生绩效评分 (满足年级水平预期的百分比) 与家庭收入中位数的分析.
- 检查了42个美国州的12,200多个公立学校区在2018-2019学年.
- 利用统计方法来确定描述收入-绩效关系的最合适的数学函数.
主要成果:
- 大约一半的州表现出对收入的熟练程度的线性增长;另一半表现出和功能.
- 与较富裕的州相比,较不富裕的州显示出相对于收入的表现增长较快.
- 在大多数地区,从三年级到八年级的数学成绩显著下降.
结论:
- 社会经济因素与教育成果有显著的相关性,在各州,科目和年级之间存在显著差异.
- 该研究提供了对教育公平的数学见解,突出了对量化,基于证据的方法的需求.
- 调查结果强调了美国收入,学业表现和教育差异之间的复杂相互作用.
相关概念视频
 01:08
Outliers and Influential Points
6.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
6.1K
 01:29
Introduction to Normal Distributions
25
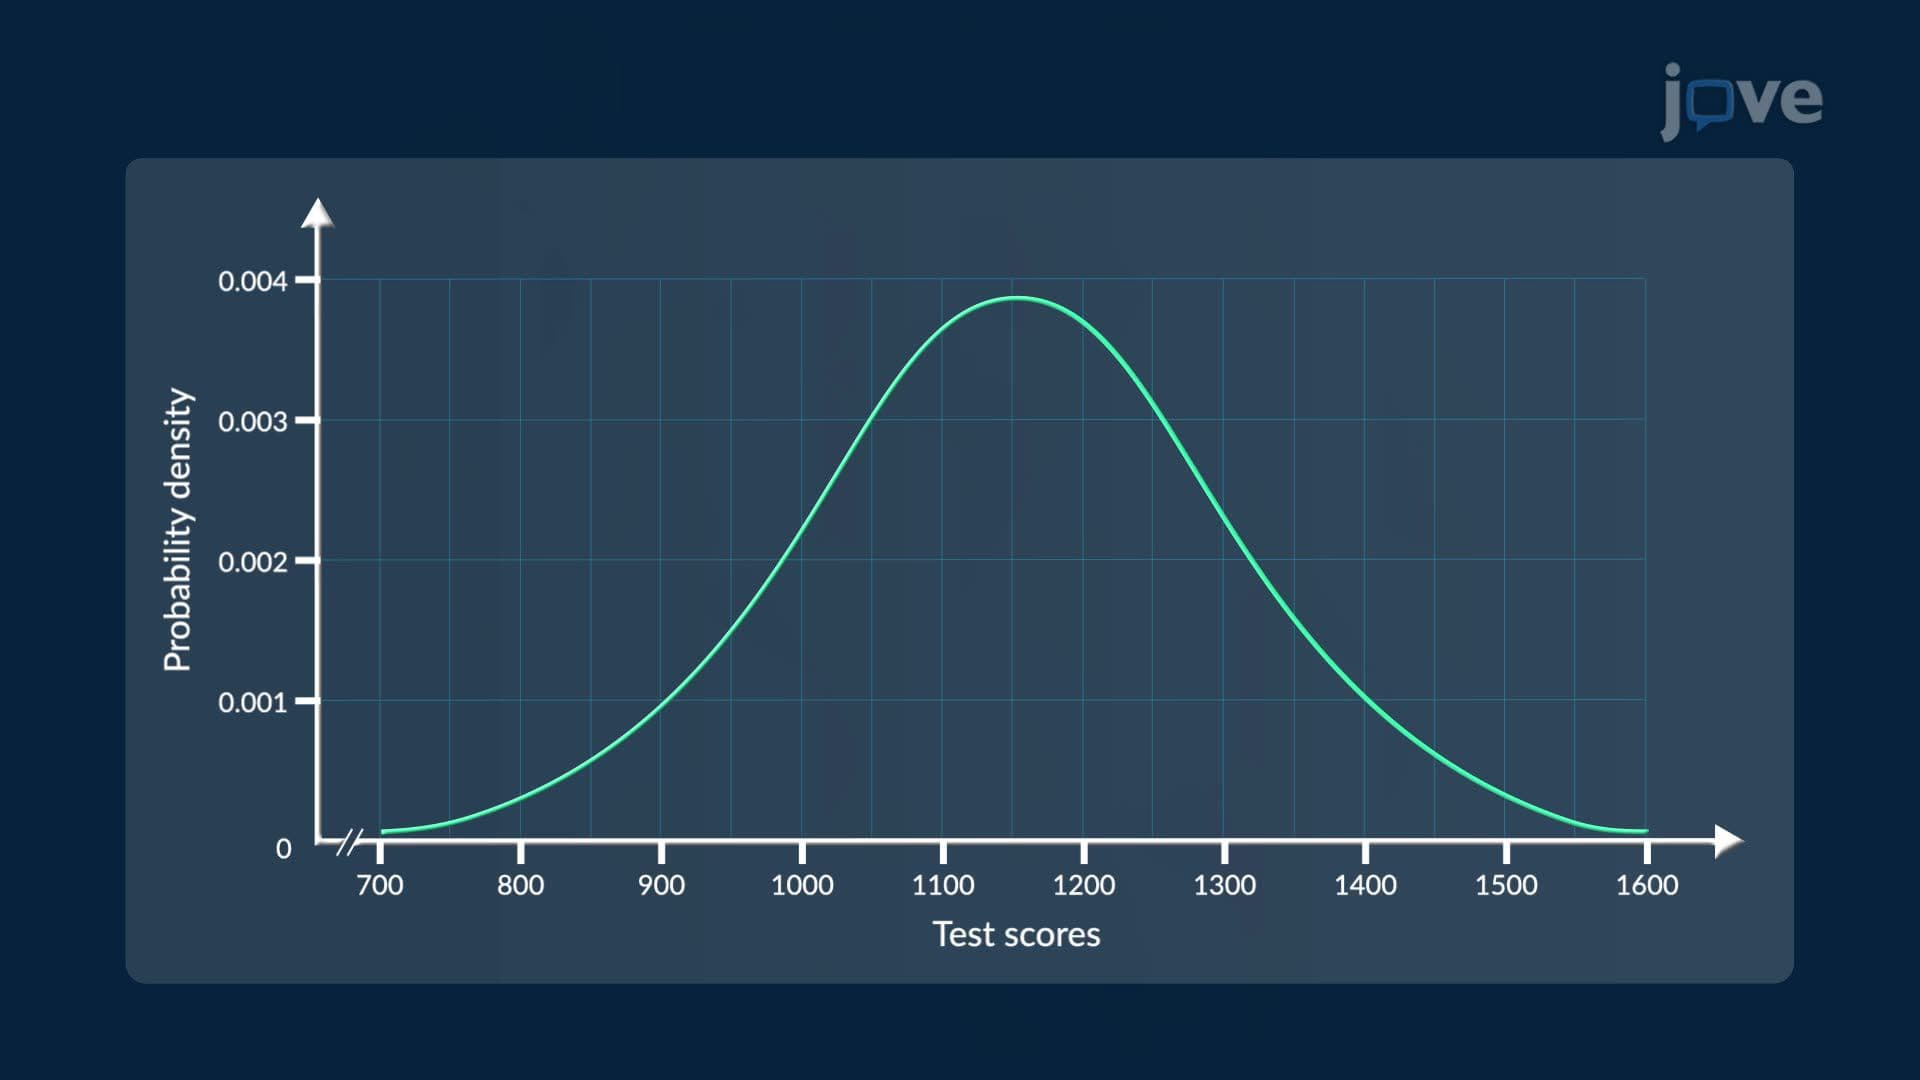
Standardized test scores often follow a symmetric distribution that can be modeled with the normal distribution, a fundamental concept in statistics. This distribution is particularly useful for interpreting test performance fairly across populations, as it provides a mathematical framework for understanding variability and central tendency in large datasets.From Histogram to Frequency DistributionRaw test data are often displayed using histograms, where the height of each bar represents the...
25
 01:16
Stratified Sampling Method
14.5K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a stratified sample, divide the population into groups called strata and then take a...
To choose a stratified sample, divide the population into groups called strata and then take a...
14.5K
 02:20
Correlations
35.8K
Correlation means that there is a relationship between two or more variables (such as ice cream consumption and crime), but this relationship does not necessarily imply cause and effect. When two variables are correlated, it simply means that as one variable changes, so does the other. We can measure correlation by calculating a statistic known as a correlation coefficient. A correlation coefficient is a number from -1 to +1 that indicates the strength and direction of the relationship between...
35.8K
 01:23
Test for Homogeneity
2.4K
The goodness–of–fit test can be used to decide whether a population fits a given distribution, but it will not suffice to decide whether two populations follow the same unknown distribution. A different test, called the test for homogeneity, can be used to conclude whether two populations have the same distribution. To calculate the test statistic for a test for homogeneity, follow the same procedure as with the test of independence. The hypotheses for the test for homogeneity can...
2.4K
 02:01
Group Design
10.2K
The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between...
10.2K