
使用合成虚拟类合成虚拟类的Softmax损失
Jiuzhou Chen1, Xiangyang Huang2, Shudong Zhang1
1School of Cyberspace Security (School of Cryptology), Hainan University, No. 58, Renmin Avenue, Haikou, 570228, Hainan, China.

概括
这项研究引入了一种新的边缘自适应合成虚拟软max损失 (SV-Softmax) 改进分类器的区分能力. 在大边缘学习任务中,SV-Softmax增强了概括和硬样本处理.
科学领域:
- 计算机科学 计算机科学
- 机器学习 机器学习
- 人工智能的人工智能
背景情况:
- 大边缘学习的目标是强大的歧视性分类器,但在概括和处理不平衡的样本难度方面面临挑战.
- 现有的方法往往因为任务概括的弱点和对容易与硬样本的偏见性处理而扎.
研究的目的:
- 提出一种新的边际自适应合成虚拟软max损失 (SV-Softmax),以解决当前大边际学习的局限性.
- 增强分类器的区分能力,任务概括和处理不平衡样本.
主要方法:
- 开发了SV-Softmax,它从嵌入式功能及其相应的原型中动态合成虚拟原型.
- 根据特征分布实施了基于特征分布的自适应性利调整,以改善特征-原型的接近性.
- 引入了硬样本采矿策略,对正确和不正确分类的样本进行差异合成.
主要成果:
- 在多个视觉分类和面部识别数据集中,SV-Softmax实现了竞争性或优异的性能.
- 与最先进的方法相比,对不平衡的简单和硬样本进行了改进的处理.
- 展示了最小的计算复杂性,不需要特征/重量规范化或超参数调整.
结论:
- 通过自适应调整利率,SV-Softmax有效地创建了明确的,有区别的决策边界.
- 拟议的方法提供了一个插即用解决方案,可以提高分类器的性能,而无需复杂的调整.
- SV-Softmax代表了大边缘学习的重大进步,特别是在具有挑战性的视觉识别任务中.
相关概念视频
 01:27
Margin of Error
7.0K
The margin of error is also called the maximum error of an estimate. The margin of error is the maximum possible or expected difference between the observed sample parameter value and the actual population parameter value. For proportion, it is the maximum difference between the value of sample proportion obtained from the data and the true value of population proportion. As the true value of the population parameter is not known, the margin of error is calculated using the sample statistic.
7.0K
 01:11
Residuals and Least-Squares Property
9.1K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
9.1K
 01:03
Prediction Intervals
3.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.3K
 01:18
Reducing Line Loss
367
In a three-phase circuit, line loss is an indicator of energy dissipated as heat due to the resistance of transmission lines. To address this, incorporating transformers into the system—a step-up transformer at the source and a step-down transformer at the load—is a strategic solution. Two three-phase transformers are introduced to improve this.
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...
367
 01:29
Aggregates Classification
972
Aggregate classification is generally based on its size, petrographic characteristics, weight, and source. Size classification ranges from coarse to fine aggregates, defined by the size of the particles. Coarse aggregates are particles that do not pass through ASTM sieve No. 4, and aggregates that pass through the sieve are fine aggregates.
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
972
 01:28
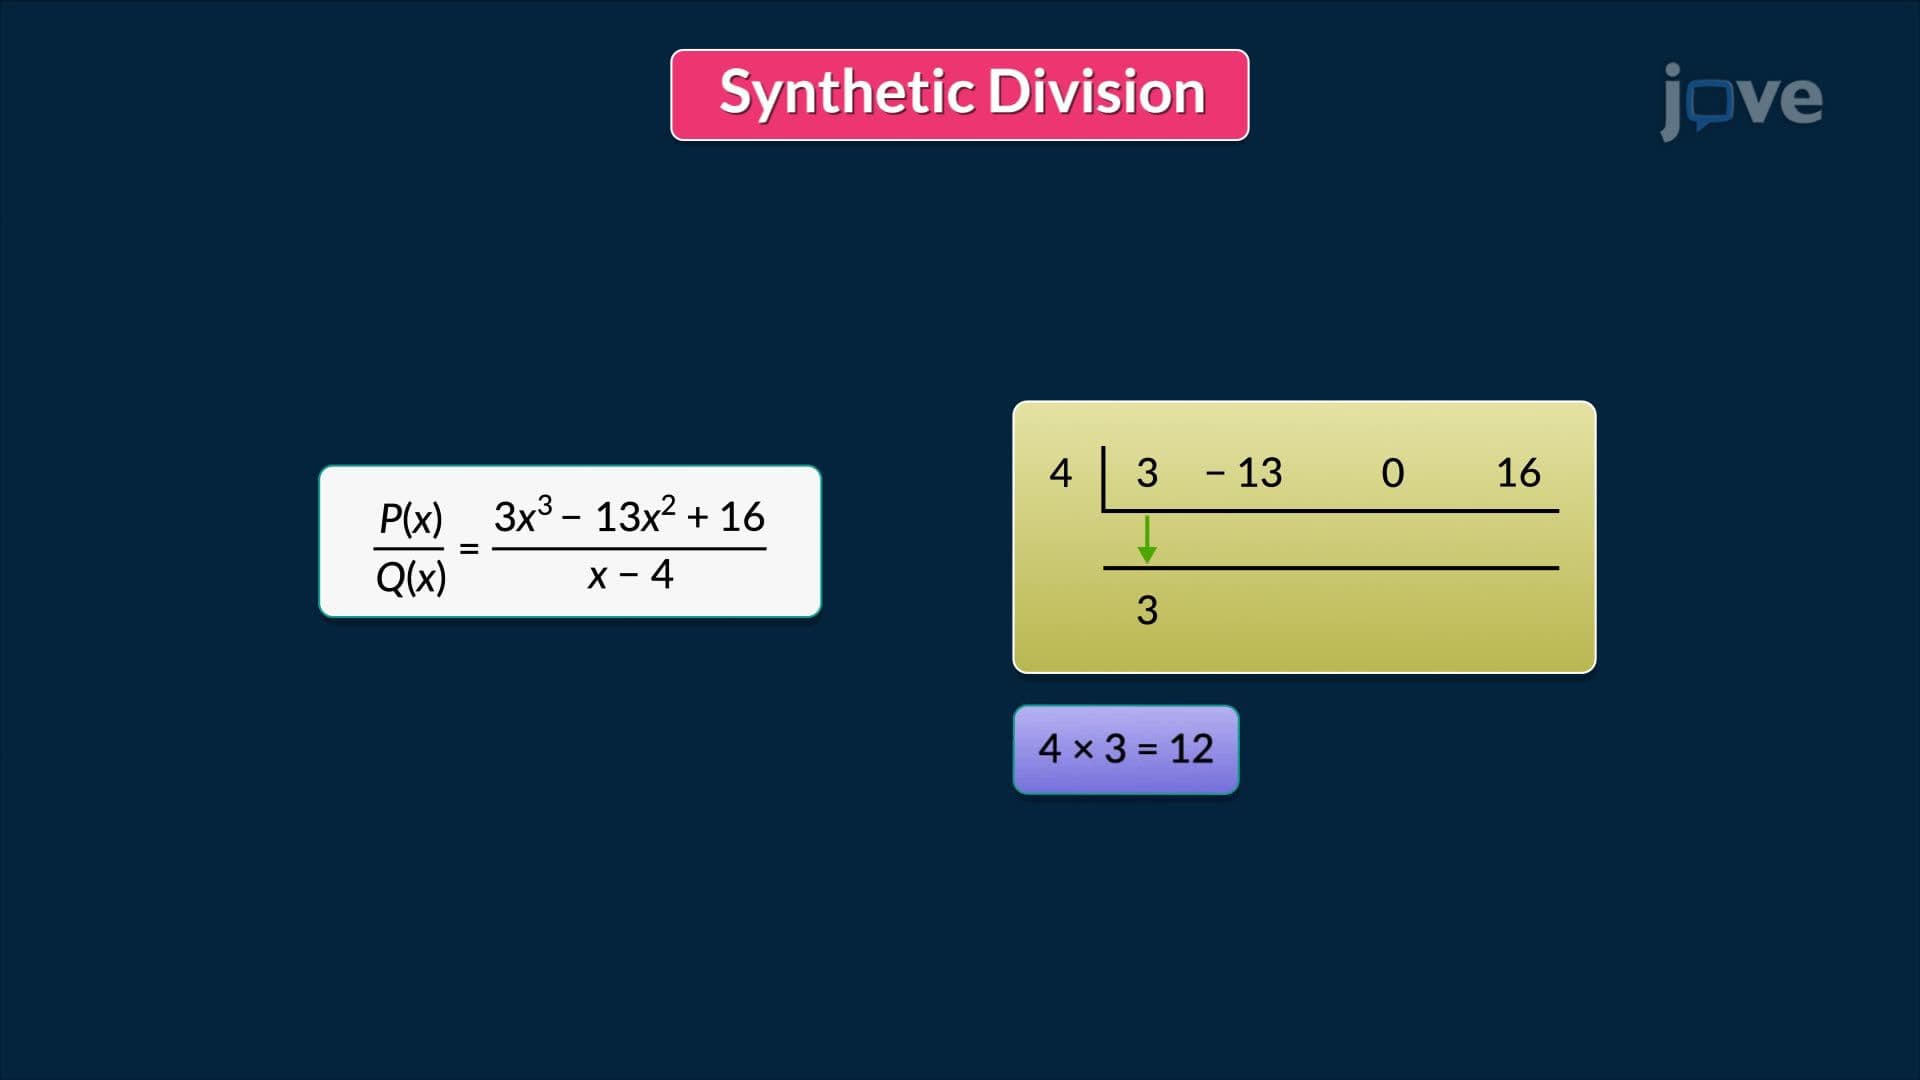
Synthetic Disvision of Polynomials
150
Synthetic division is an efficient algorithmic approach for dividing a polynomial by a linear binomial of the form x - c, where c is a real number. This method is helpful due to its streamlined process, which avoids the more cumbersome steps involved in the traditional long division of polynomials. It simplifies computation and serves as a practical tool for evaluating polynomials and identifying their factors.To perform synthetic division, one begins by listing the coefficients of the...
150