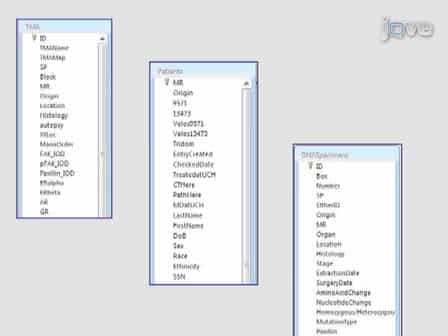

从原始数据到研究准备:基于FHIR的转型管道在现实世界瘤环境中
Antonella Carbonaro1, Luca Giorgetti1, Lorenzo Ridolfi2
1Department of Computer Science and Engineering - DISI, University of Bologna, Via dell'Università 50, 47521, Cesena, Italy.
Computers in biology and medicine
|September 13, 2025

概括
本研究引入了一个管道,将异质瘤学数据转换为含义丰富的数据集,使用快速医疗互操作性资源 (FHIR) 和资源描述框架 (RDF). 这使得更好的数据集成和研究的先进分析成为可能.
科学领域:
- 医疗信息学 医疗信息学
- 数据科学数据科学数据科学
- 计算生物学 计算生物学
背景情况:
- 医疗数据的指数增长需要提高互操作性和标准化.
- 异质的临床数据在数据交换和二次使用方面存在挑战,原因是数据不一致.
- 快速医疗互操作性资源 (FHIR) 是医疗数据协调的关键标准.
研究的目的:
- 利用RDF开发基于FHIR的管道,将异质瘤学数据转化为语义上丰富的,准备研究的数据集.
- 为了实现语义互操作性,并加强跨不同医疗保健系统的数据链接.
- 支持在瘤学研究中的自动推理和大规模二次数据使用.
主要方法:
- 开发了一个基于FHIR的转型管道,利用资源描述框架 (RDF).
- 以RDF图形表示FHIR资源,用于语义互操作性和自动推理.
- 采用了一个模板转换策略,用于域专家专注的声明映射.
- 将该方法应用于癌症虚拟实验室内的真实世界瘤学数据集.
主要成果:
- 从36,335个患者记录中成功将1,093,705个临床记录转换为1,151,559个基于RDF的FHIR资源类型.
- 证明了使用FHIR和RDF语义整合瘤学数据的可行性.
- 通过语法/语义验证和专家审查,确保技术正确性和临床相关性.
结论:
- FHIR-RDF管道有效地从瘤学数据中创建机器可读,可互操作的知识表示.
- 丰富的数据有助于提高数据质量,协调,纵向分析和人工智能驱动的决策支持.
- 该方法促进临床数据的大规模二次使用,以推进癌症研究和患者护理.
相关概念视频
 01:29
Issues And Trends In Healthcare Delivery System
The issues and trends in healthcare delivery are constantly changing. The COVID-19 pandemic is one recent issue that wreaked havoc on healthcare systems, causing a shortage of healthcare workers, high demand for medicines and supplies, and increased medical expenditure due to a lack of insurance. Other issues include rising healthcare costs and care fragmentation.
Cost Containment
Payment for healthcare services has historically promoted adoption of costly and often unnecessary or inefficient...
Cost Containment
Payment for healthcare services has historically promoted adoption of costly and often unnecessary or inefficient...
 02:07
Improving Translational Accuracy
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...