
一个需要谨慎的理由:识别突然的收益可能取决于所使用的结果衡量标准
Ashleigh B Correa1, Madelyne A Bisby1, Blake F Dear1
1eCentreClinic, School of Psychological Sciences, Faculty of Medicine and Health, Macquarie University, Sydney, Australia.
Cognitive behaviour therapy
|September 16, 2025

概括
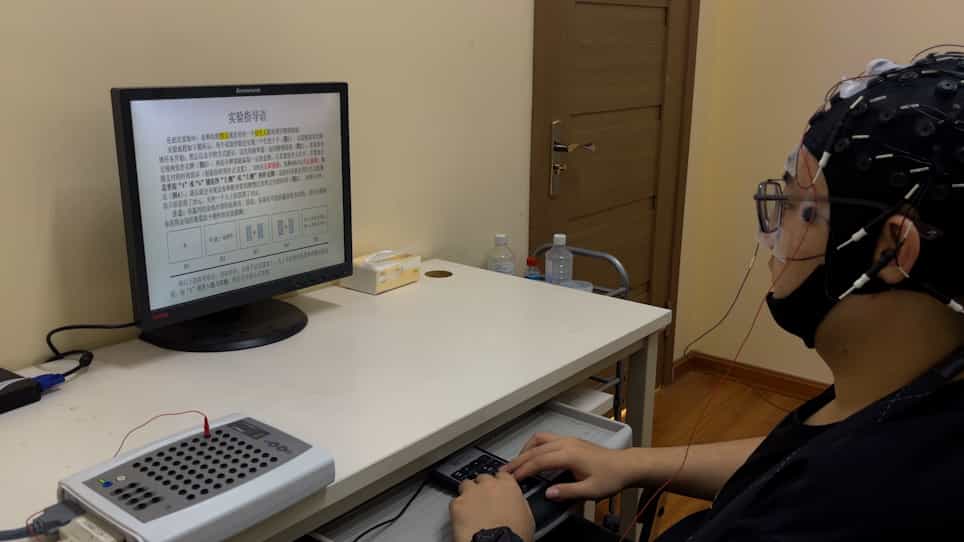
对抑郁和焦虑的超短尺度可能会错过治疗中的一些"突然收益",这可能会影响结果的比较. 标准和超简短的测量确定了不同的个体经历了这些快速症状改善.
科学领域:
- 精神病学是一个精神病学.
- 临床心理学 临床心理学
- 数字健康数字健康
背景情况:
- 被定义为快速而持久的症状减轻的突然增长与更好的治疗结果有关.
- 在临床研究中频繁测量症状可能会造成负担.
- 超短尺度提供了一种减少患者负担和提高完成率的方法.
研究的目的:
- 为了比较突然增强的时间,患病率和治疗结果.
- 用标准和超简短的自我报告措施来检查抑郁和焦虑的突然增长.
- 调查测量长度对在互联网提供的治疗中突然增强检测的影响.
主要方法:
- 分析了为期五周的大学生在互联网上接受治疗的现有数据 (N=937).
- 使用患者健康问卷 (PHQ-9) 和其超简短版本 (PHQ-2) 测量抑郁症.
- 使用通用焦虑障碍7项级 (GAD-7) 和其超短版本 (GAD-2) 测量焦虑.
主要成果:
- 标准的PHQ-9发现了比PHQ-2更多的突然增长;GAD-2发现了比GAD-7更多的突然增长.
- 关键的是,标准和超简短的测量标识了不同的个人经历了突然的增长.
- 突然增长与更高的基线症状严重程度有关.
结论:
- 测量尺度的选择 (标准与超简短) 影响突然增长的检测.
- 这些发现引发了关于使用不同测量工具的研究中突然增益研究的可比性的问题.
- 需要进一步的研究,以了解不同突发增益检测率的临床影响.
相关概念视频
 01:52
Regression Toward the Mean
6.9K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.9K
 01:04
Significance Testing: Overview
11.5K
Significance testing is a set of statistical methods used to test whether a claim about a parameter is valid. In analytical chemistry, significance testing is used primarily to determine whether the difference between two values comes from determinate or random errors. The effect of a particular change in the measurement protocol, analyst, or sample itself can cause a deviation from the expected result. In the case of a suspected deviation/outlier, we need to be able to confirm mathematically...
11.5K
 01:00
Detection of Gross Error: The Q Test
6.9K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.9K
 01:19
Testing a Claim about Standard Deviation
2.9K
A complete procedure to test a claim about population standard deviation or population variance is explained here.
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
2.9K
 01:12
Hindsight Biases
4.2K
Hindsight bias leads you to believe that the event you just experienced was predictable, even though it really wasn’t. In other words, you knew all along that things would turn out the way they did. Can you relate this to the phrase "Hindsight is 20/20" now?
4.2K
 01:14
Identifying Statistically Significant Differences: The F-Test
3.1K
The F-test is used to compare two sample variances to each other or compare the sample variance to the population variance. It is used to decide whether an indeterminate error can explain the difference in their values. The underlying assumptions that allow the use of the F-test include the data set or sets are normally distributed, and the data sets are independent of each other. The test statistic F is calculated by dividing one variance by another. In other words, the square of one standard...
3.1K