
使用基于scikit-learn的工具集AIDE进行可访问,统一的蛋白质性质预测
Evan Komp1,2, Kristoffer E Johansson3, Nicholas P Gauthier4,5
1Renewable Resources and Enabling Sciences Center, National Renewable Energy Laboratory, Golden Colorado, CO 80401, United States.
Bioinformatics (Oxford, England)
|September 24, 2025

概括
人工智能驱动的蛋白质估计 (AIDE) 软件简化了用于蛋白质性质预测的机器学习. 该工具标准化了各种蛋白质序列的零射击和监督方法,提高了可复制性和可访问性.
科学领域:
- 计算生物学 计算生物学
- 机器学习 机器学习
- 生物信息学是一种生物信息学.
背景情况:
- 蛋白质性质预测的机器学习正在迅速发展.
- 目前的方法往往是不同的,限制了广泛的应用和可复制性.
- 预测蛋白质变体和同类物质的特性需要灵活的工具.
研究的目的:
- 引入人工智能驱动的蛋白质估计 (AIDE),一个统一的软件包.
- 为了实现标准化实例化,优化和测试各种蛋白质性质预测模型.
- 为了促进可复制的机器学习工作流程蛋白质变体和同类.
主要方法:
- AIDE是一个与scikit-learn API兼容的Python包.
- 它支持零射击和监督学习方法.
- 该软件旨在实现模块化,并易于集成到现有管道中.
主要成果:
- AIDE为各种财产预测方法提供了一个标准化的API.
- 它允许在变长同类和变体上测试模型.
- 该软件包可安装在主要操作系统 (Windows,Mac,Linux) 上.
结论:
- AIDE提高了机器学习在蛋白质性质预测中的力量和可访问性.
- 它的模块化设计促进了可重现性,并简化了各种模型的测试.
- 该软件提供了全面的文档和用户指南.

相关概念视频
 02:26
Conservation of Protein Domains Over Different Proteins
13.9K
Protein domains are small structurally independent units that are part of a single amino acid chain. Although these domains are often structurally independent, they may rely on synergistic effects to perform their functions as part of a larger protein. Protein domains may be conserved within the same organism, as well as across different organisms.
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
13.9K
 01:19
Uniform Distribution
5.9K
The uniform distribution is a continuous probability distribution of events with an equal probability of occurrence. This distribution is rectangular.
Two essential properties of this distribution are
Two essential properties of this distribution are
5.9K
 01:03
Prediction Intervals
3.1K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.1K
 01:45
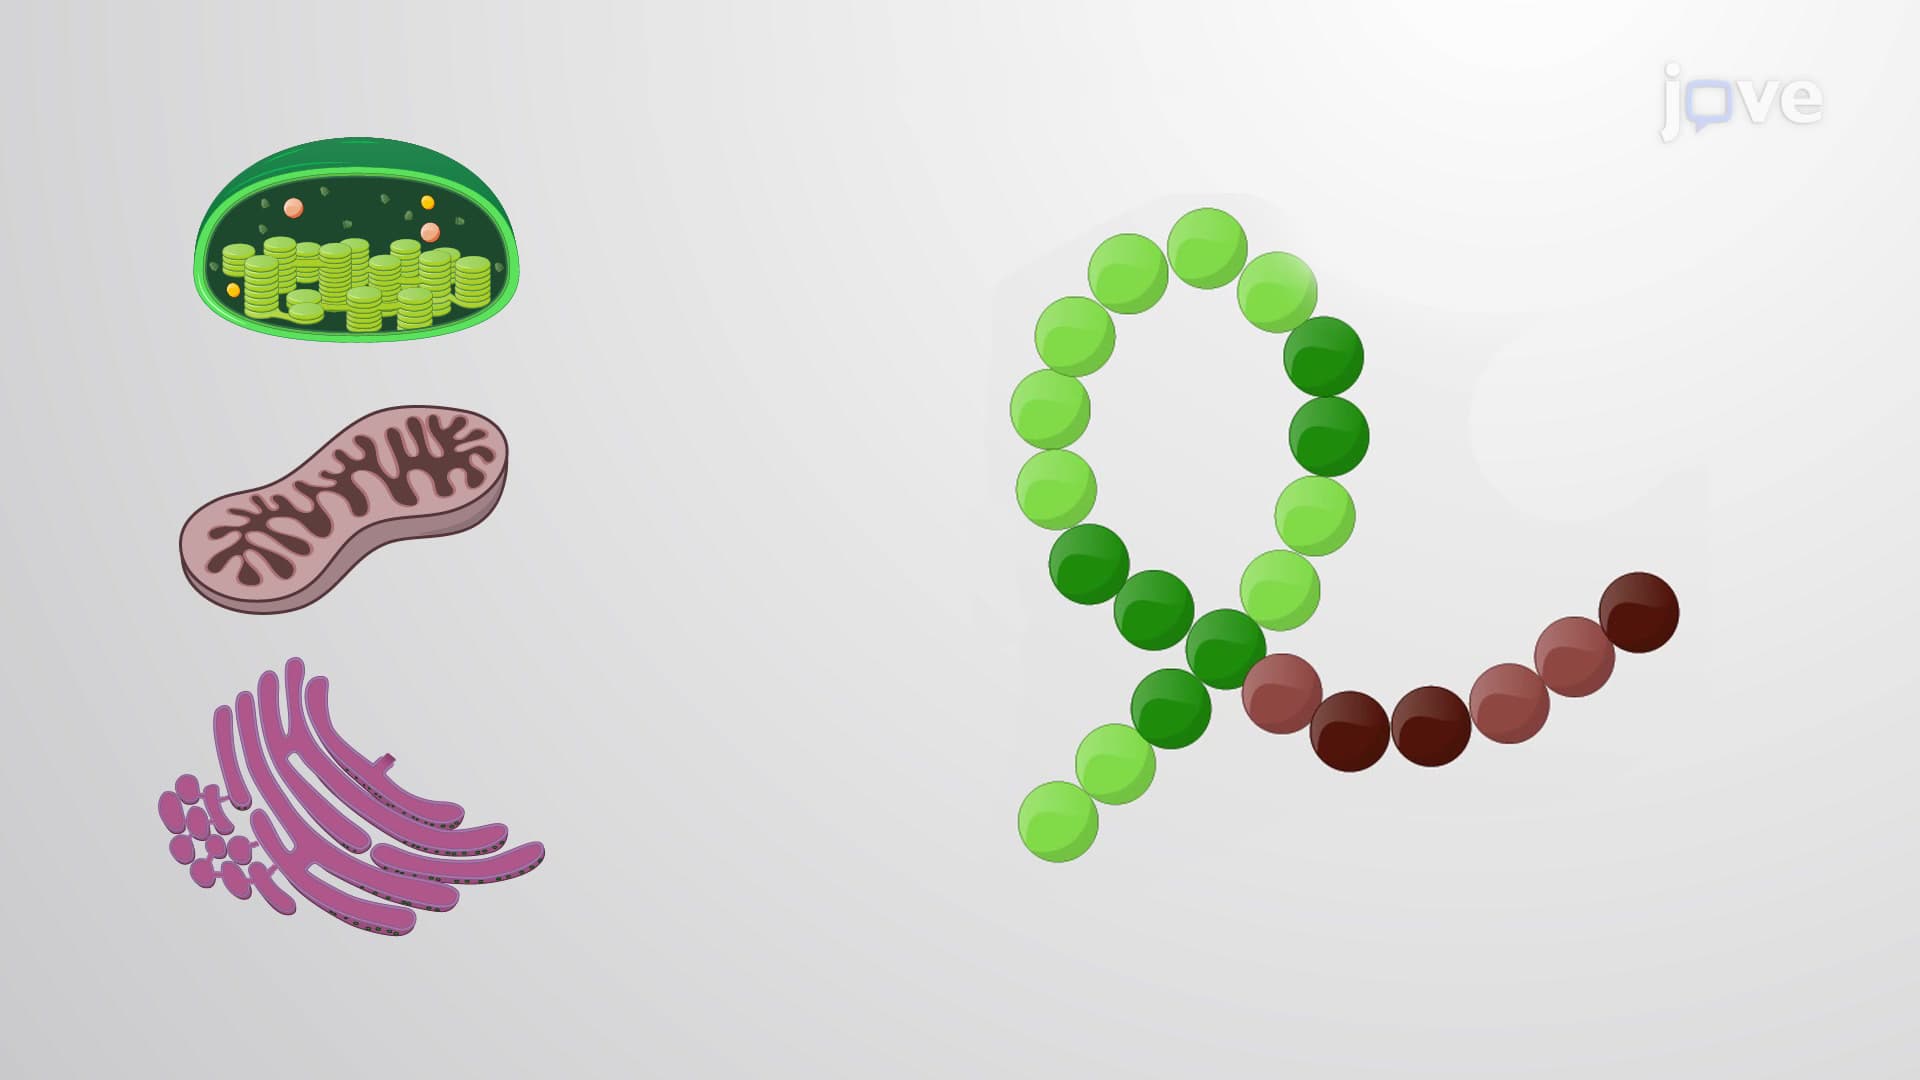
Overview of Protein Sorting and Transport
21.4K
Eukaryotic cells have different membrane-bound organelles with distinct protein requirements. The process by which proteins are targeted to a specific organelle is called protein sorting.
Protein sorting can be of two types: signal-based sorting and vesicle-based trafficking. In signal-based sorting, specific amino acid sequences called sorting signals target proteins to the proper location inside the cell either via gated transport or by protein translocation. In gated transport, folded...
Protein sorting can be of two types: signal-based sorting and vesicle-based trafficking. In signal-based sorting, specific amino acid sequences called sorting signals target proteins to the proper location inside the cell either via gated transport or by protein translocation. In gated transport, folded...
21.4K
 02:47
Protein Families
16.6K
Protein families are groups of homologous proteins; that is, they have similarities in amino acid sequences and three-dimensional structures. Protein families usually occur because of gene duplication, where an additional copy of a gene is inserted into the genome of an organism. Mutations that change the amino acids but still allow the protein to be properly synthesized, will lead to new protein family members. If these new proteins contain similar amino acids in key...
16.6K
 01:49
Conserved Binding Sites
5.0K
Many proteins’ biological role depends on their interactions with their ligands, small molecules that bind to specific locations on the protein known as ligand-binding sites. Ligand-binding sites are often conserved among homologous proteins as these sites are critical for protein function.
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally...
5.0K